Weibo Trending Scraper
hipersoft/weibo-scraper
Scrape the Weibo (微博) hot-search / trending board: rank, topic, heat value, category and label (new/hot/boiling). Realtime board or government board.
Total users
2Monthly users
1Total runs
85Per topic scraped
$0.001Last rebuilt
Oct 26, 2026Overview
Scrape Weibo hot-search and trending data into clean JSON, CSV, Excel or XML. This Weibo scraper extracts the full 微博热搜 hot-search board — rank, topic, heat value (搜索指数), category and label (new / hot / boiling / exploding) for every trending topic, plus a ready-to-open search link. A fast, cheap, no-code way to track what China is talking about right now.
No login, no setup and no complicated tooling: add your inputs, click Run, and get a structured dataset of Weibo's live trending topics you can push straight into analytics, dashboards, an LLM pipeline or a spreadsheet.
What does the Weibo Scraper do?
The Weibo Scraper crawls and extracts the public Weibo hot-search / trending board and returns it as structured data points — the rank of each topic, its heat value, its category, its status label and a direct search URL. Choose the main realtime board (微博热搜) or the side board (government + realtime), set how many topics you want, and export everything as JSON, CSV, Excel or XML. Because the board updates in real time, you can schedule the Actor to build a running time series of trending topics, viral hashtags and breaking news across Chinese social media.
What data can you scrape from Weibo?
| Group | Fields |
|---|---|
| 🔥 Trending topic | rank, topic / hashtag text, heat value (搜索指数), board |
| 🏷️ Status & category | label (新 new / 热 hot / 沸 boiling / 爆 exploding), category, is-new flag, is-hot flag |
| 🔗 Link | direct Weibo search URL for the topic |
| ⏱️ Timestamp | collectedAt — when the topic was captured, for building time series |
Use cases
- China social-trend monitoring — track the realtime hot-search board and see what's trending across Chinese social media minute by minute.
- PR & brand tracking — get alerted when your brand, campaign or executive lands on the Weibo trending board.
- News & story discovery — surface breaking stories and viral topics before they hit Western outlets.
- Virality & marketing research — study how topics climb the ranks, peak on heat value and fade, and time your own posts.
- Build a trending dataset — schedule the Actor to record rank and heat over time for topic modelling and forecasting.
- Competitor & industry watch — filter by category to follow entertainment, tech, auto, sports or finance topics.
- Content & editorial planning — feed live trending topics into a newsroom or content calendar.
- Academic & market research — analyse public attention, agenda-setting and information flow on the world's largest Chinese microblog.
How to scrape Weibo trending data
- Click Try for free / Start to open the Weibo Scraper.
- Choose the board —
realtimefor the main 微博热搜 hot-search board, orsidefor the government + realtime side board. - Set maxItems — how many trending topics you want per run.
- Click Run.
- Download the results as JSON, CSV, Excel or XML, or pull them from the Apify API.
Input
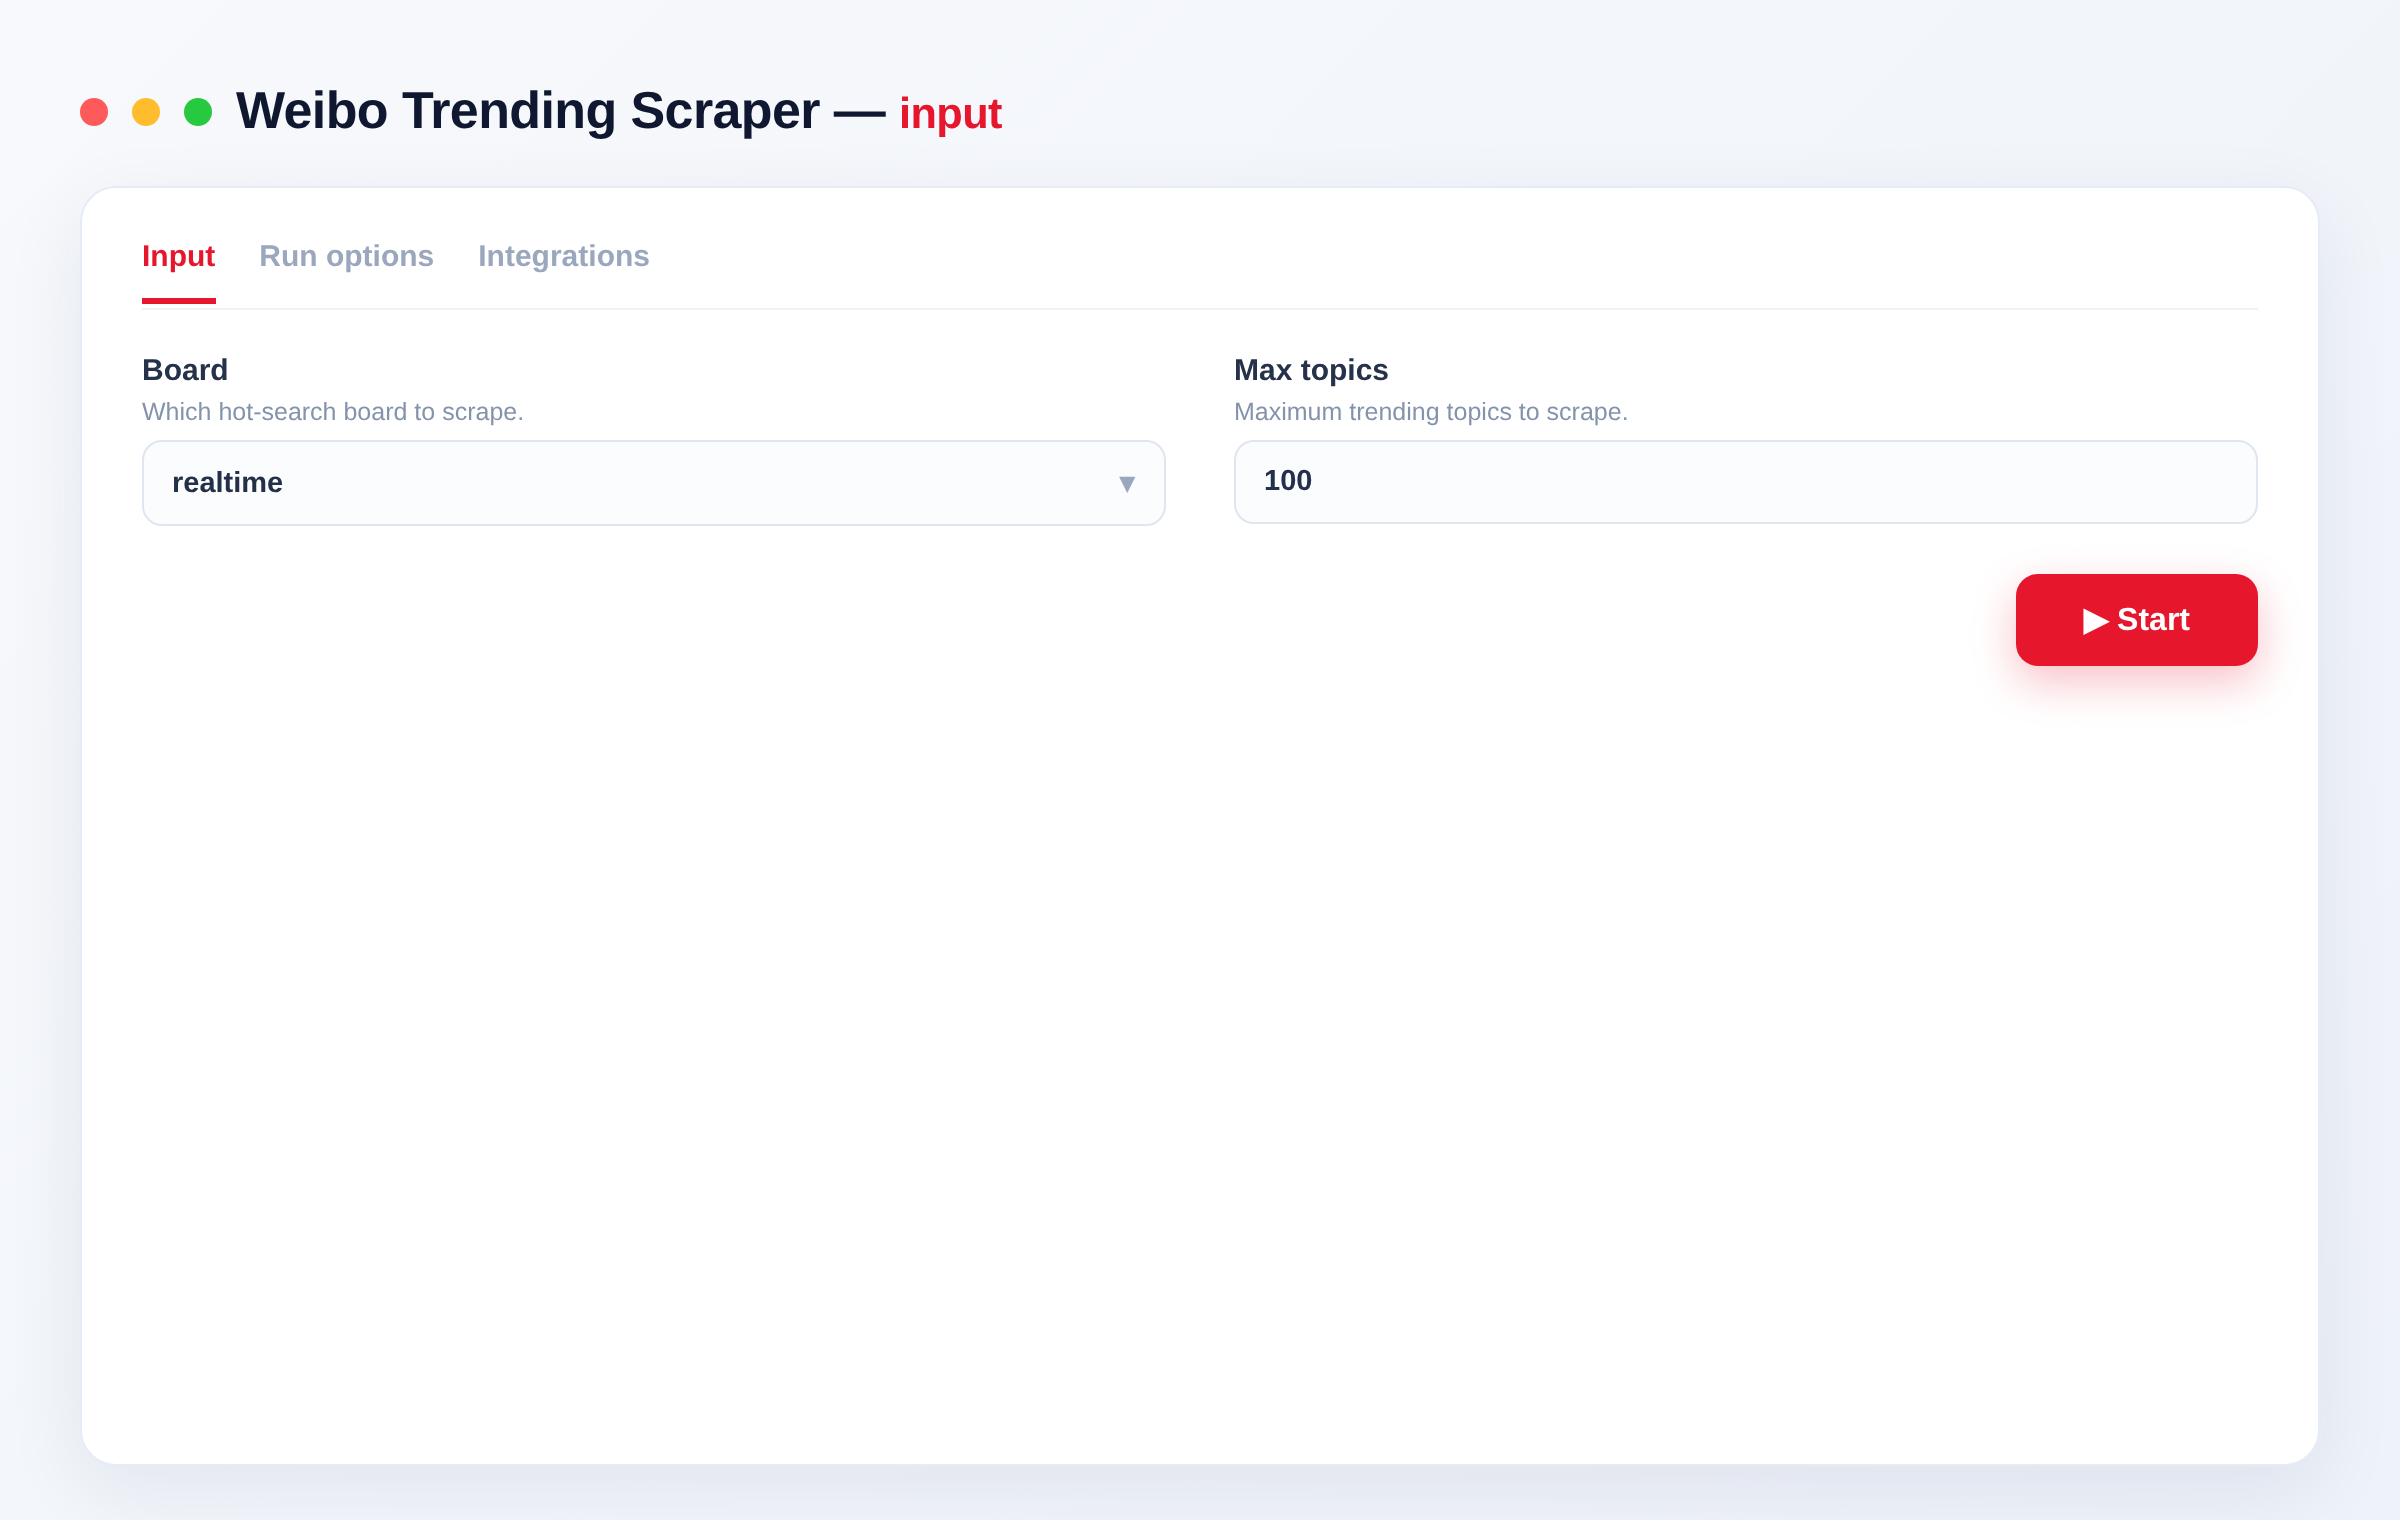
Pick a board and a topic limit — that's the whole setup.
{
  "board": "realtime",
  "maxItems": 100
}
| Field | Type | Description |
|---|---|---|
board |
string | Which board to scrape: realtime (the main 微博热搜 hot-search board) or side (government + realtime side board). Default realtime. |
maxItems |
integer | Maximum number of trending topics to scrape (1–1000, default 100). The board typically returns about 50 realtime topics. |
Scrape the realtime hot-search board (微博热搜)
Set board to realtime to pull the iconic Weibo hot-search list — roughly 50 live topics ranked by heat, the same board millions of users refresh throughout the day.
Scrape the side board (gov + realtime)
Set board to side to add the government board alongside the realtime topics, useful for policy, news and official-topic monitoring.
Output
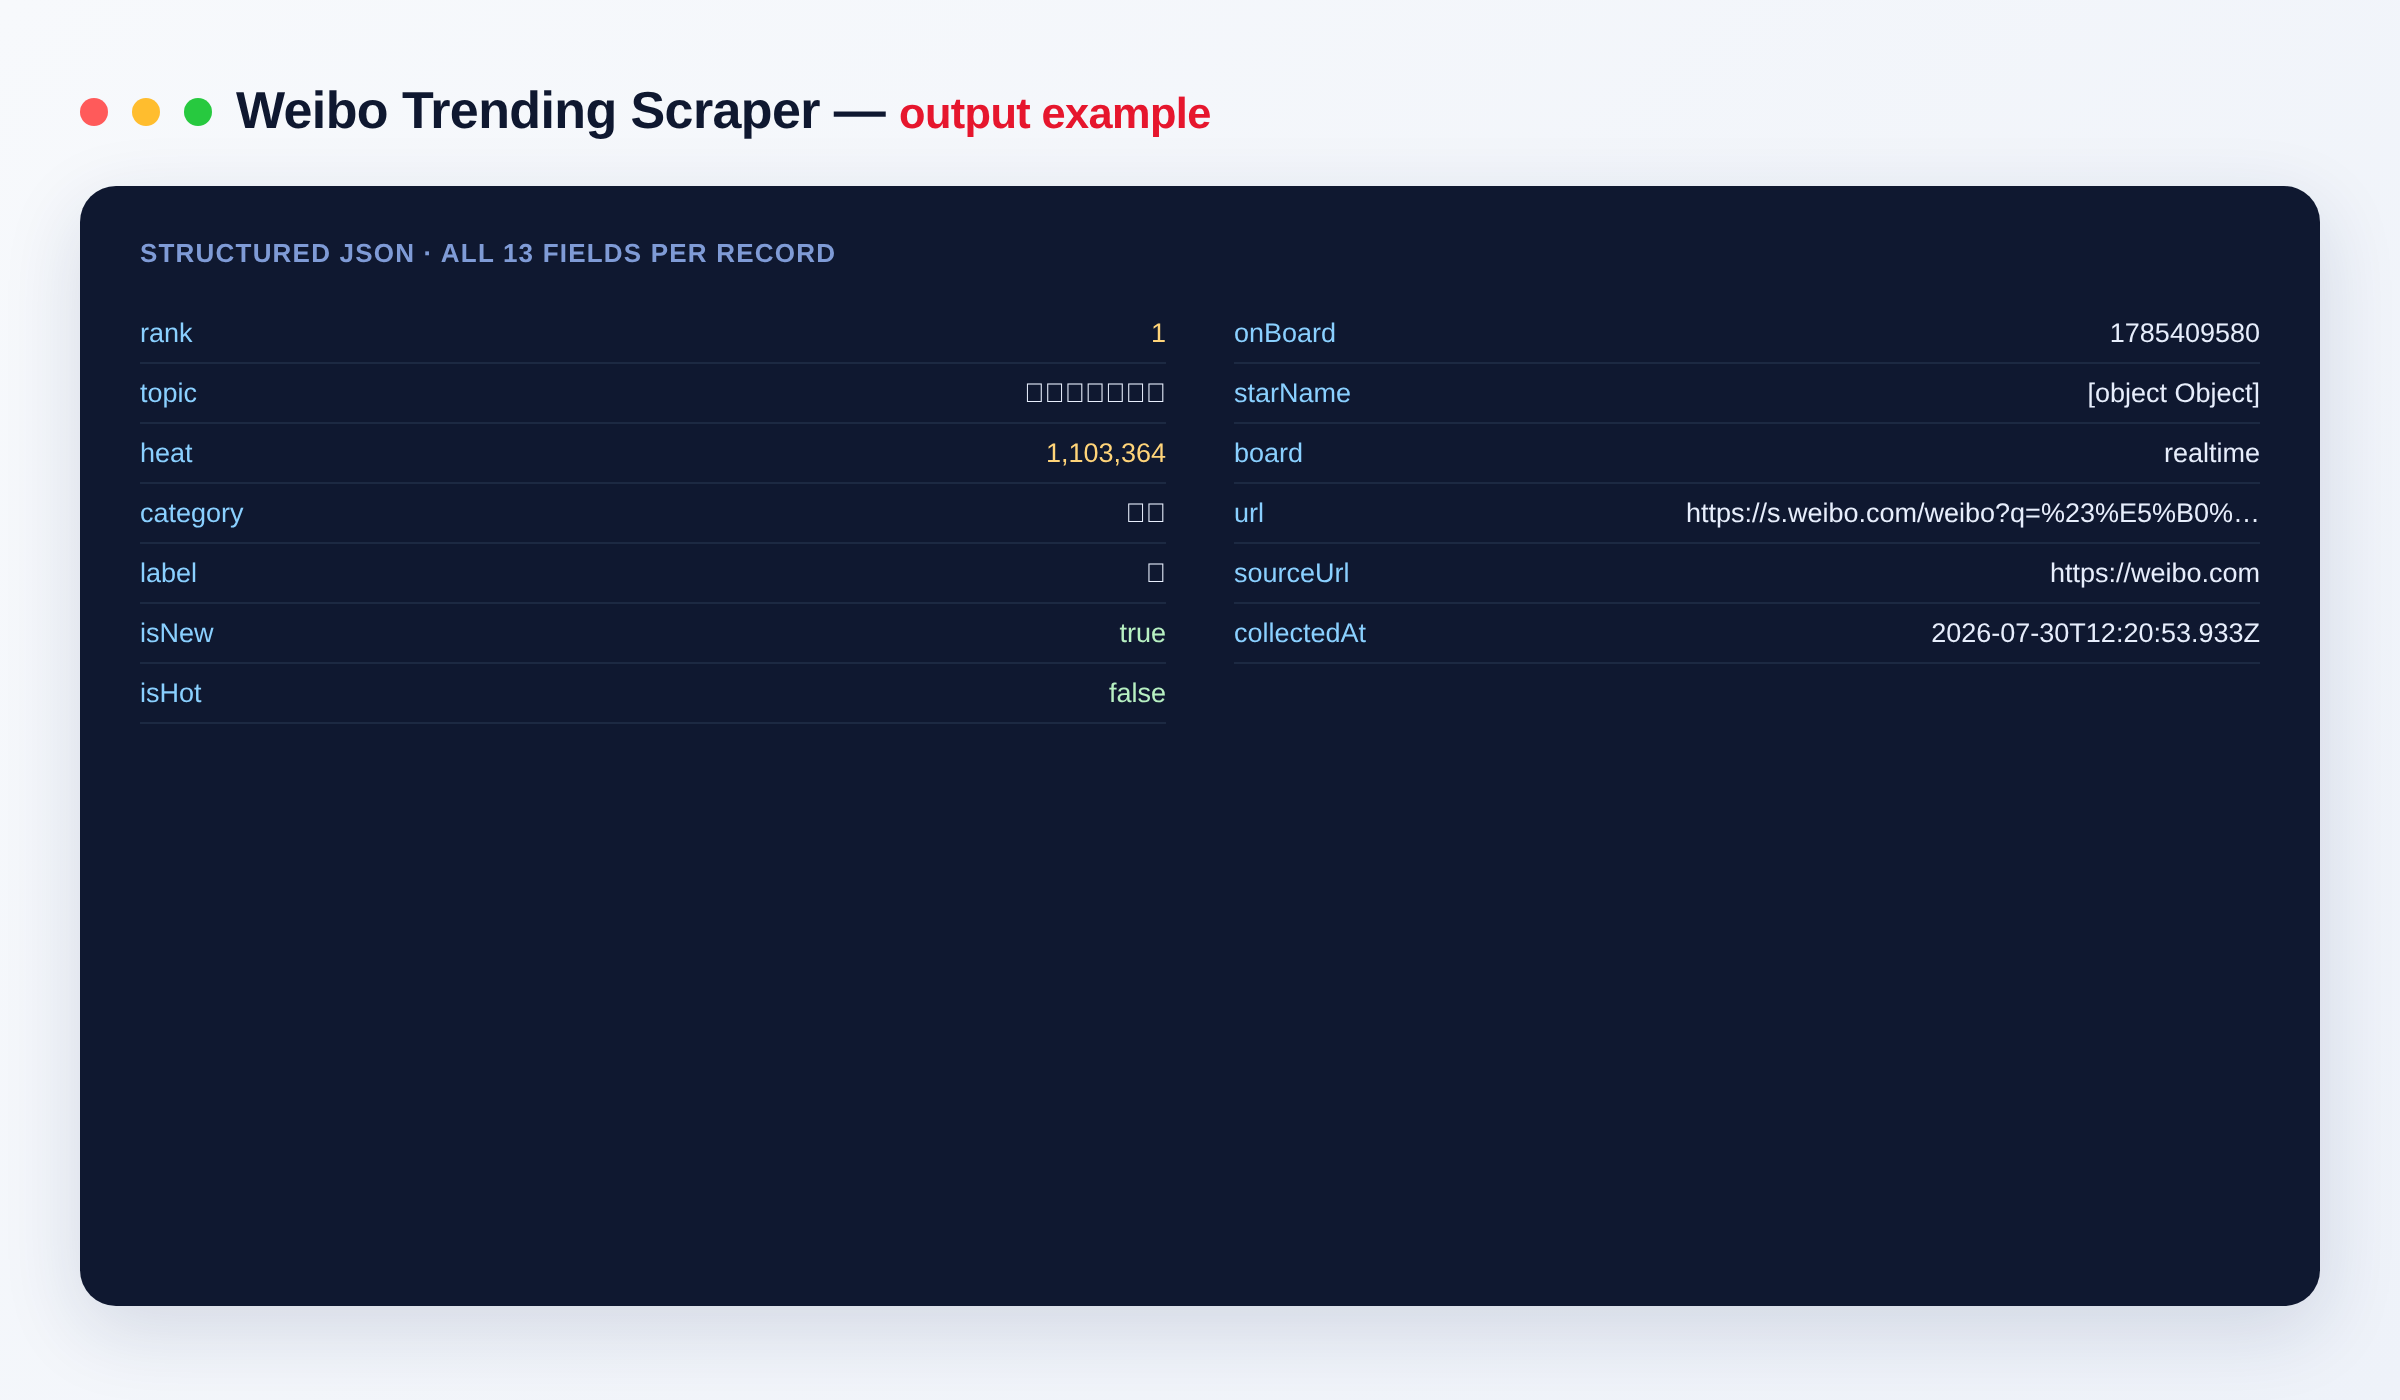
Each trending topic is one dataset item:
{
  "rank": 1,
  "topic": "小米发布会",
  "heat": 1092924,
  "category": "汽车",
  "label": "新",
  "isNew": true,
  "isHot": false,
  "board": "realtime",
  "url": "https://s.weibo.com/weibo?q=%23%E5%B0%8F%E7%B1%B3%E5%8F%91%E5%B8%83%E4%BC%9A%23",
  "collectedAt": "2026-07-30T12:00:00.000Z"
}
Output schema
| Field | Type | Description |
|---|---|---|
rank |
integer | Position of the topic on the board (1 = hottest). |
topic |
string | The trending topic or hashtag text. |
heat |
integer | Weibo's heat value / search index (搜索指数) — higher means hotter. |
category |
string | Topic category, e.g. entertainment, tech, auto, sports. |
label |
string | Status label: 新 (new), 热 (hot), 沸 (boiling) or 爆 (exploding). |
isNew |
boolean | Whether the topic is flagged as newly trending. |
isHot |
boolean | Whether the topic carries the hot (热) label. |
board |
string | Which board the topic came from — realtime or side. |
url |
string (URL) | Direct Weibo search URL for the topic. |
collectedAt |
string (ISO date) | Timestamp when the topic was captured, for building time series. |
Need more Chinese platform data?
Building a wider view of Chinese social media and culture? Pair the Weibo Scraper with our other China-focused Actors:
- Bilibili Scraper — videos, channels, views and stats from China's biggest video platform.
- Xiaohongshu Scraper — notes, posts and creators from RED / Little Red Book.
- Douban Scraper — movie, book and TV ratings and reviews.
- Toutiao Scraper — trending news articles and headlines.
FAQ
Do I need a Weibo account or login? No. There's no setup and no login — just choose a board, set a topic limit and run.
How many topics can I scrape per run?
The realtime hot-search board returns roughly 50 topics; the side board adds a government board. Use maxItems to cap how many you keep per run.
How fresh is the data? The hot-search board is realtime. Schedule the Actor (for example every 15–30 minutes) to build a continuous time series of what's trending in China.
Can I filter by category?
Every item includes a category and status label, so you can filter the dataset to entertainment, tech, auto, sports, finance and more after each run.
How does billing work? You pay only per topic you get, so a run costs in proportion to the data it returns — one of the cheapest ways to monitor Weibo trends.
What export formats are supported? JSON, CSV, Excel and XML, plus webhooks and the Apify API.
Can I automate or integrate the Weibo Scraper? Yes. The Weibo Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes — get a notification, or kick off another process such as loading your data downstream.
Is scraping Weibo legal? The Actor collects only public data. You are responsible for how you use it and for complying with Weibo's terms and applicable laws.
Notes
Original clean-room implementation. Collects only public Weibo data; you are responsible for how you use the data and for complying with Weibo's terms. This is an independent tool and is not affiliated with or endorsed by Weibo.
Input
| Field | Type | Description |
|---|---|---|
boardBoard | string · realtime, side | Which hot-search board to scrape. Default: "realtime" |
maxItemsMax topics | integer | Maximum trending topics to scrape. Default: 100 |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~weibo-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/weibo-scraper").call(run_input={})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/weibo-scraper').call({});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Topic scraped One trending topic scraped. | $0.001 | $0.001 |
| API request One Weibo API request. | $0.0008 | $0.0008 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Europe PMC Scraper
Bulk-scrape life-science and biomedical literature from Europe PMC (40M+ records: PubMed, PMC, preprints, patents): title, abstract, authors, journal, year, DOI, PMID/PMCID, citation count, MeSH terms, open-access flag and full-text/PDF links. Thousands per run. No setup.
325 runs · 5 users · $0.001 / article scraped
arXiv Papers Scraper
Search and extract arXiv papers: title, abstract, authors, categories, published/updated dates, DOI, journal reference, and direct PDF links. Filter by category and sort by newest, recently updated or relevance. Fetch by arXiv ID too. For research, lit reviews and AI/ML monitoring. No setup.
140 runs · 2 users · $0.0025 / paper scraped
Letterboxd Scraper
Scrape Letterboxd films with ratings, rating counts, genres, director, cast, runtime and synopsis. Feed it film pages, a user's films/watchlist/diary, any list URL, or browse pages. For film data, recommendations and research.
139 runs · 7 users · $0.0042 / film scraped
OpenLibrary Book Scraper
Search millions of books on OpenLibrary by keyword, author, subject or ISBN and get title, authors, publisher, year, subjects, ISBNs, edition count, ratings, page count and cover. Clean, no setup.
124 runs · 5 users · $0.002 / book scraped
Semantic Scholar Scraper
Bulk-scrape academic papers from Semantic Scholar's 200M+ corpus: title, abstract, AI TLDR summary, authors, venue, year, citation & influential-citation counts, fields of study, DOI/PubMed/arXiv IDs and open-access PDF links. Filter by year, field and citations. Thousands per run. No setup.
123 runs · 7 users · $0.001 / paper scraped
Wikipedia Scraper
Search Wikipedia or look up exact articles and get the full plain-text content, summary, categories, image, Wikidata ID and monthly pageview trends. Any language. Great for research, RAG and AI datasets. No setup.
121 runs · 1 users · $0.001 / article scrapedSend the site and the fields. We build it and you get it first.