Scrapers / Developer & File Tools
Douban Scraper
hipersoft/douban-scraper
Scrape Douban (豆瓣) movies, TV and shows: rating, votes, genres, cast, directors, year and cover. Hot lists, keyword search, or details by subject id.
Total users
2Monthly users
1Total runs
93Per item scraped
$0.002Last rebuilt
Oct 26, 2026Overview
Scrape Douban (豆瓣), China's biggest film, TV and culture rating site, into clean JSON, CSV or Excel. This Douban scraper extracts rating, vote count, genres, cast, directors, year, original title, countries, runtime and cover image for movies, TV series and variety shows. Pull hot lists, run a keyword search, or fetch full details by subject id. Fast and reliable.
Perfect for China film and TV intelligence, rating benchmarks, catalog enrichment and content research.
What does Douban Scraper do?
The Douban Scraper collects movie, TV and variety-show entries from Douban and returns them as structured data. It supports three modes — browse a hot-list collection, search by keyword, or fetch details by subject id — and extracts the full metadata for each title, including the Douban rating and number of votes, so you can build a complete Chinese film and TV dataset.
What data can you scrape from Douban?
| Category | Fields |
|---|---|
| ⭐ Ratings | rating, rating count, comment count |
| 🎬 Title | title, original title, type, year |
| 🎭 People & genre | directors, actors, genres, countries, durations |
| 📝 Content | summary, cover image |
| 🔗 Links & meta | subject id, listing URL, source URL, collected date |
What you get
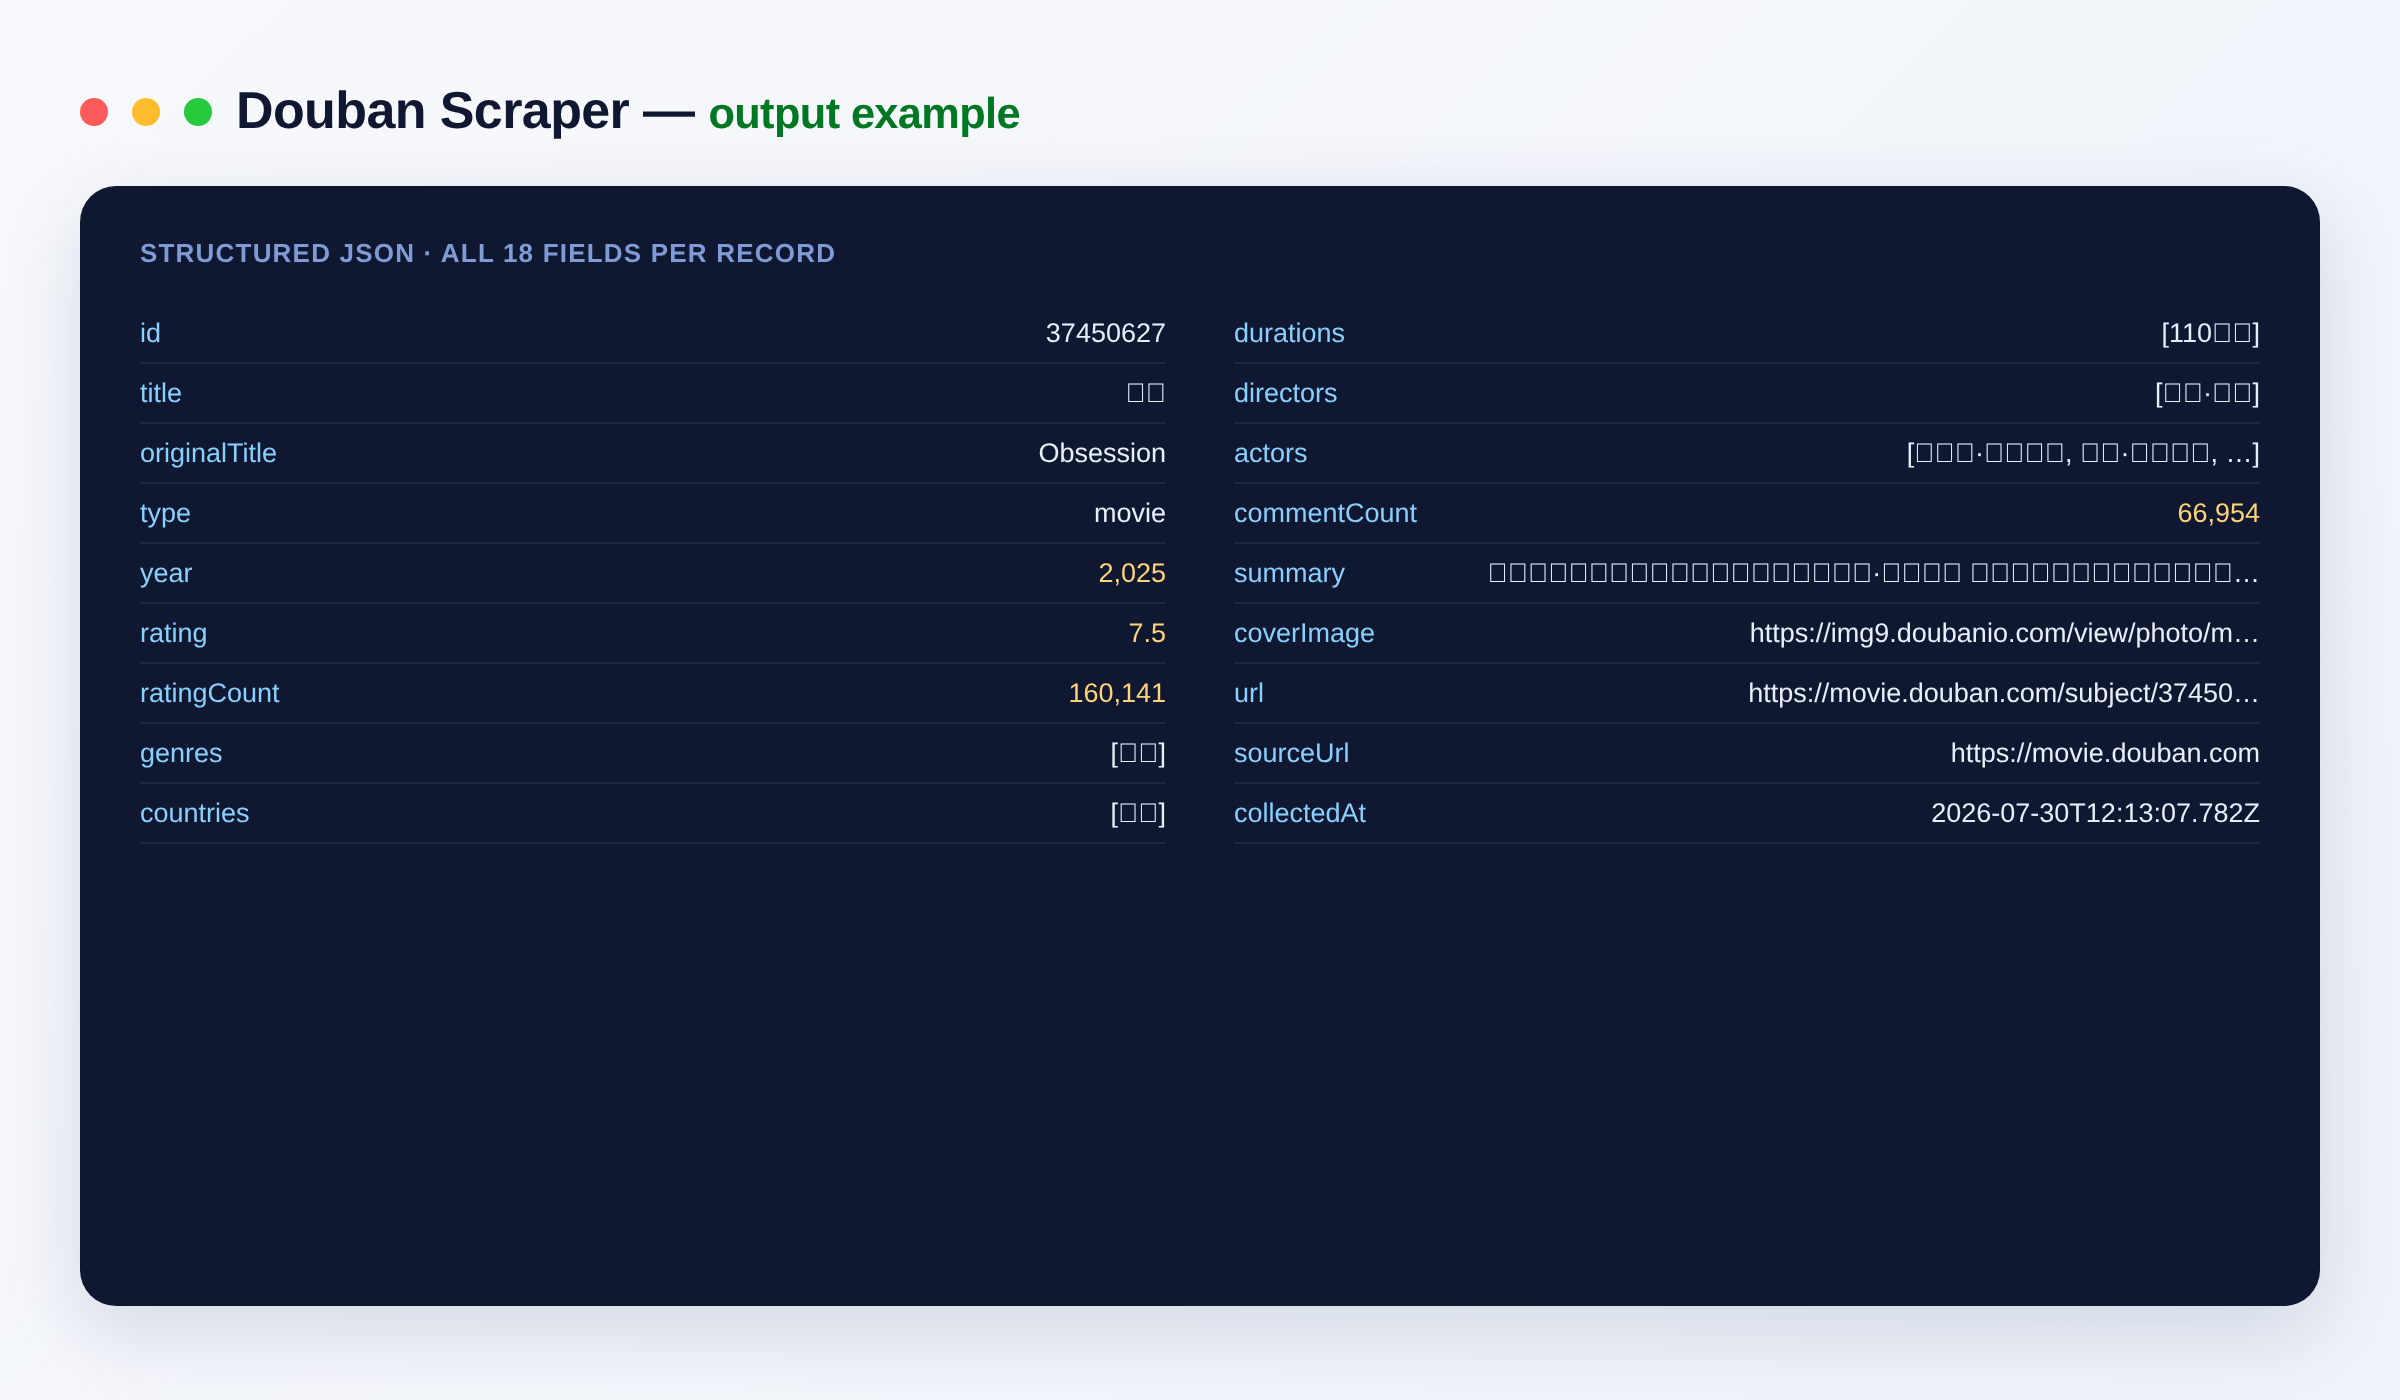
Each title is returned as one clean record. Example output:
{
  "id": "37450627",
  "title": "痴迷",
  "originalTitle": "Obsession",
  "type": "movie",
  "year": 2025,
  "rating": 7.5,
  "ratingCount": 160122,
  "genres": ["恐怖"],
  "countries": ["美国"],
  "durations": ["110分钟"],
  "directors": ["库里·巴克"],
  "actors": ["迈克尔·约翰斯顿", "印达·纳瓦雷特"],
  "commentCount": 4821,
  "summary": "A chilling supernatural thriller...",
  "coverImage": "https://img9.doubanio.com/...",
  "url": "https://movie.douban.com/subject/37450627/",
  "sourceUrl": "https://movie.douban.com/explore",
  "collectedAt": "2026-07-30T12:00:00.000Z"
}
Output schema
| Field | Type | Description |
|---|---|---|
id |
string | Douban subject id of the title. |
title |
string | Title as shown on Douban. |
originalTitle |
string | Original-language title. |
type |
string | Content type, e.g. movie or TV. |
year |
integer | Release year. |
rating |
number | Douban rating on a 0–10 scale. |
ratingCount |
integer | Number of ratings received. |
genres |
array | List of genres. |
countries |
array | List of production countries or regions. |
durations |
array | Runtime values for the title. |
directors |
array | List of directors. |
actors |
array | List of main cast members. |
commentCount |
integer | Number of user comments. |
summary |
string | Plot summary or synopsis. |
coverImage |
string (URL) | Cover poster image URL. |
url |
string (URL) | Direct link to the Douban page. |
sourceUrl |
string (URL) | Source page URL for the record. |
collectedAt |
string (ISO date) | Timestamp when the record was collected. |
Use cases
- Rating benchmarks — compare Douban scores and vote counts across titles and genres.
- Catalog enrichment — add Chinese-market metadata and ratings to your media database.
- Content research — track hot movies, TV and variety shows over time.
- Recommendation engines — feed genres, cast and ratings into similarity models.
- Market intelligence — analyze how titles perform with Chinese audiences.
- Cast and crew analysis — map directors and actors across a body of work.
How to scrape Douban data
- Add the Douban Scraper to your Apify account.
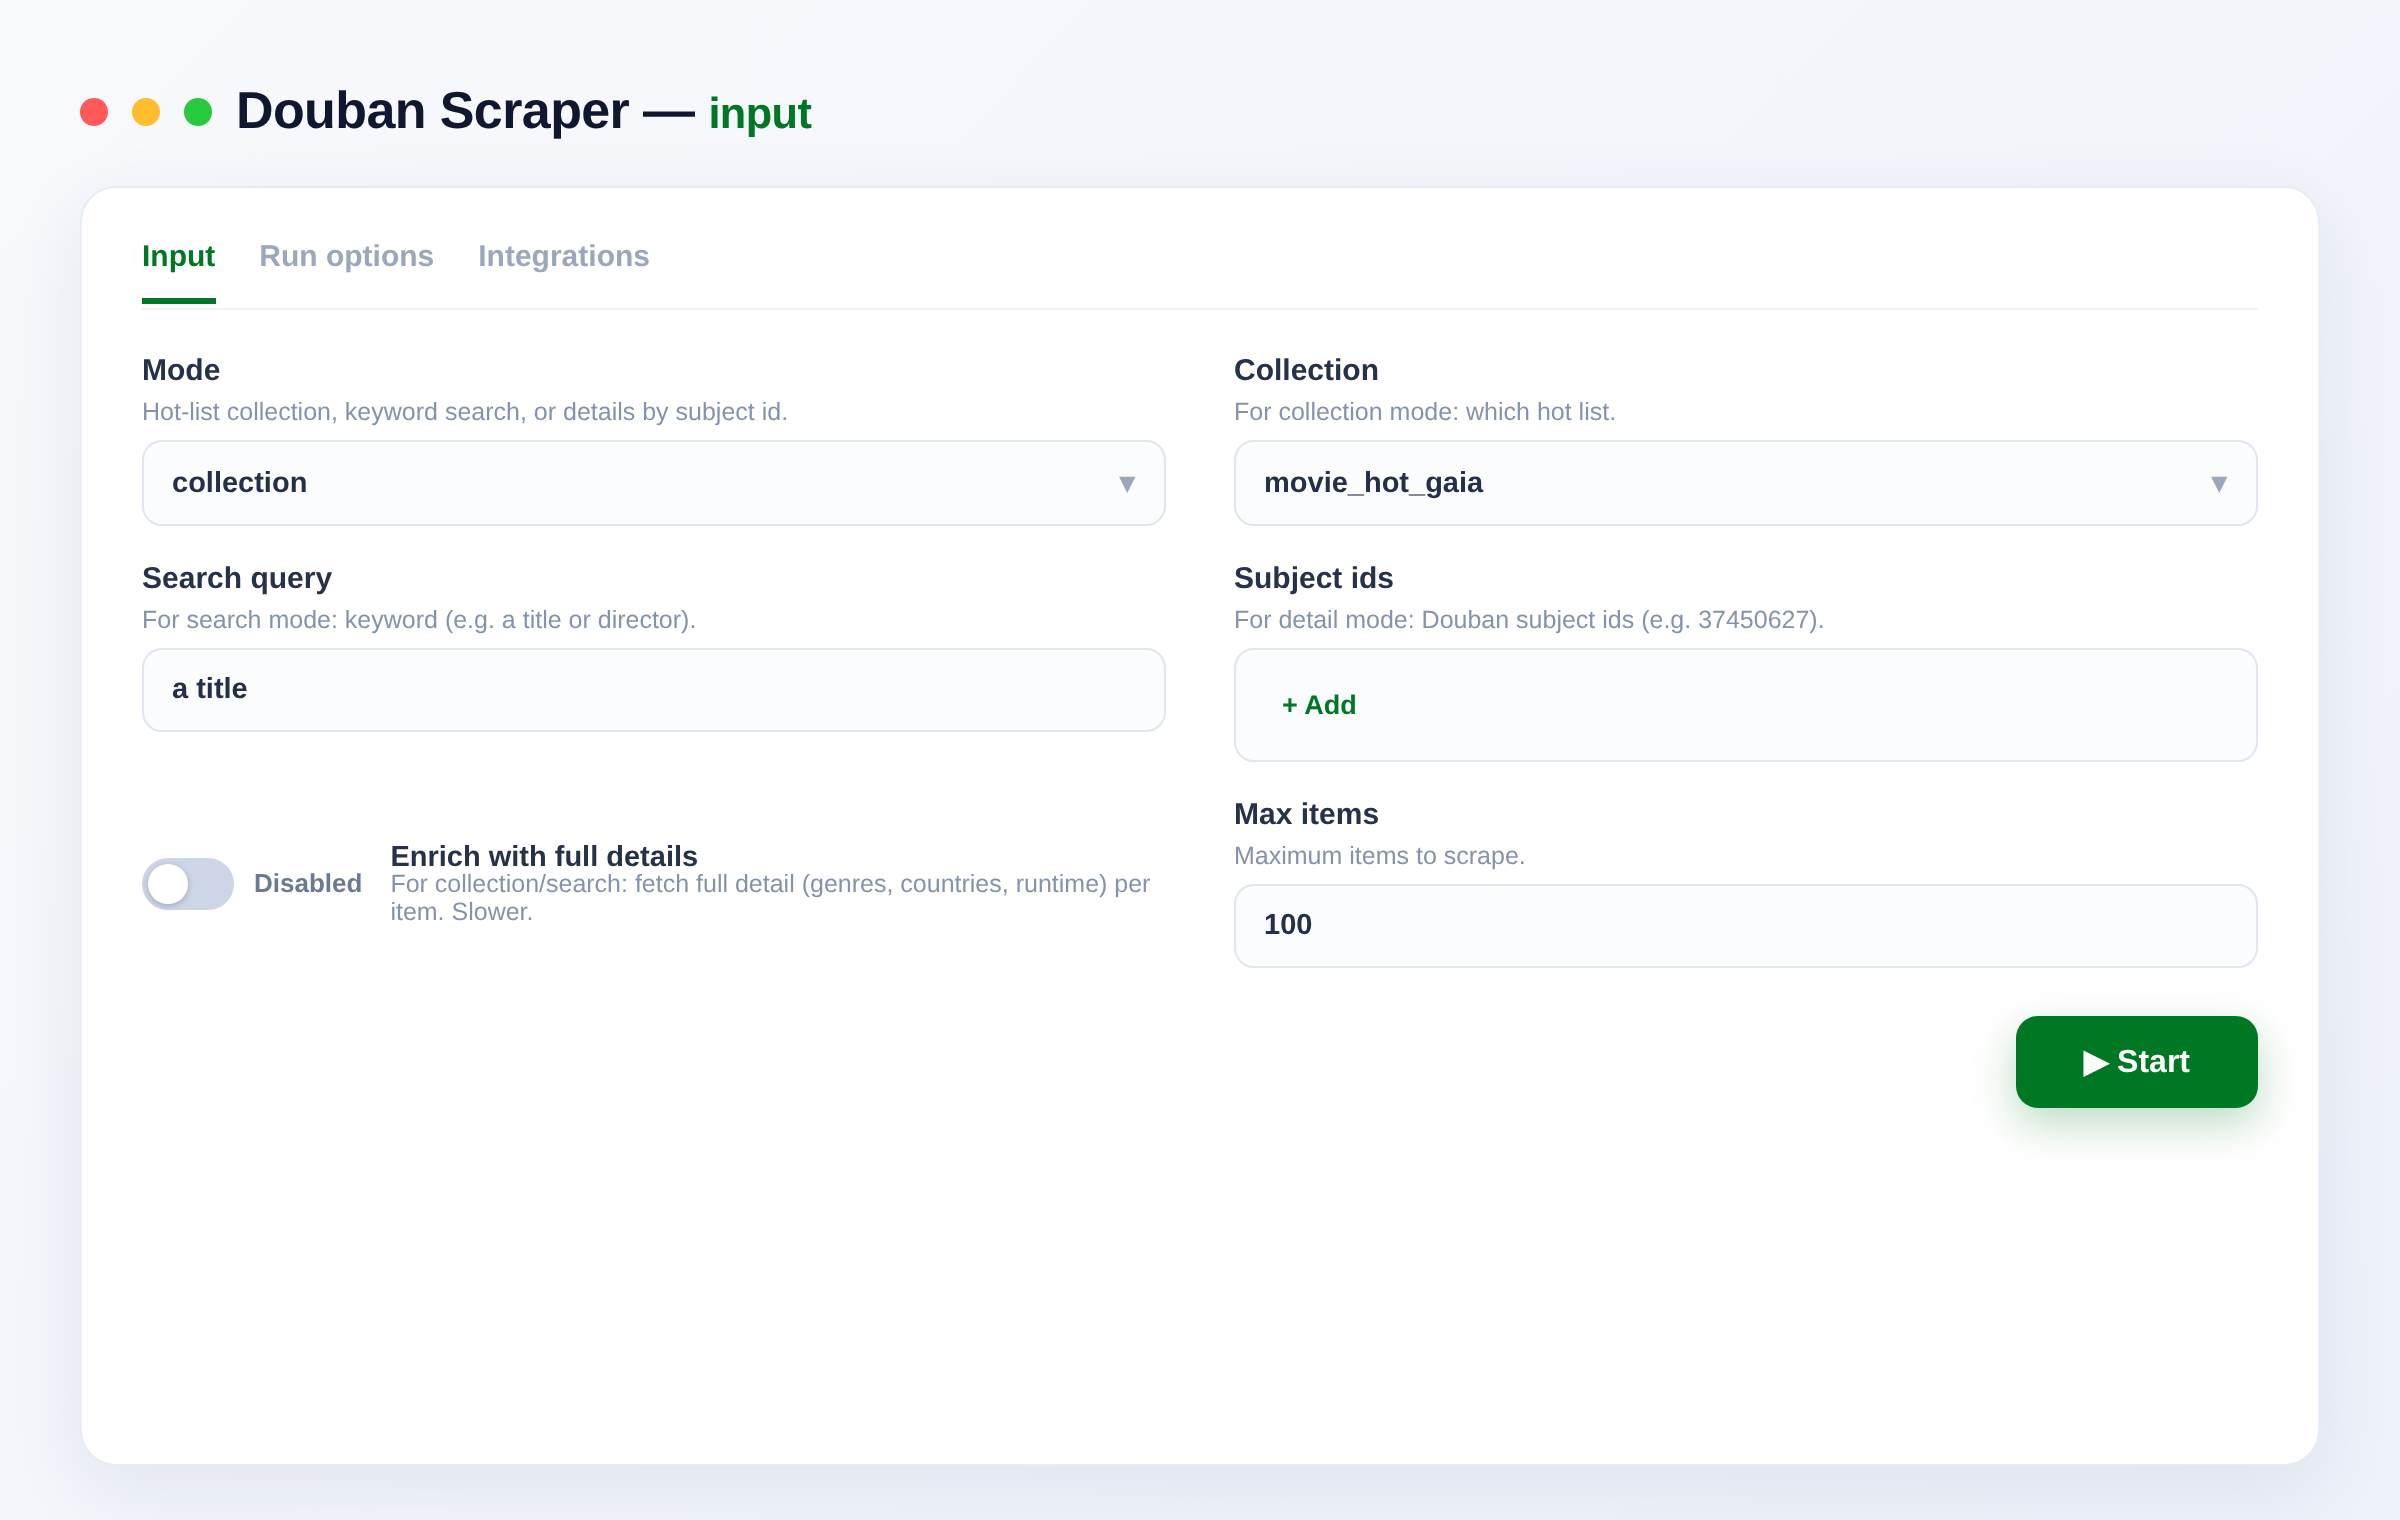
- Pick a mode — collection (hot list), search (keyword), or detail (by subject id).
- Set the collection, search query or subject ids, and a max item limit.
- Optionally turn on Enrich with full details to add genres, countries and runtime.
- Click Run, then export as JSON, CSV, Excel or XML, or pull via the Apify API.
Input
{
  "mode": "collection",
  "collection": "movie_hot_gaia",
  "maxItems": 100
}
Search, enriched with full details:
{ "mode": "search", "searchQuery": "诺兰", "enrichDetails": true, "maxItems": 40 }
Details by id:
{ "mode": "detail", "subjectIds": ["37450627", "35267208"] }
| Field | Type | Description |
|---|---|---|
mode |
string | collection, search, or detail. |
collection |
string | Which hot list to pull (hot movies, hot TV, Korean TV, animation and more). |
searchQuery |
string | Keyword for search mode (a title or a person). |
subjectIds |
array | Douban subject ids for detail mode. |
enrichDetails |
boolean | For collection/search: fetch full detail (genres, countries, runtime) per item. |
maxItems |
integer | Maximum number of items to scrape. |
Need more media and culture data?
FAQ
How many titles can I scrape?
As many as you like — set maxItems to cap the run, or leave it high to pull everything available.
Do I need any setup or a login? No setup and no login. Just add the actor, choose a mode, and run.
Why are genres, countries or runtime empty in collection mode?
List mode returns the core fields quickly. Turn on Enrich with full details (or use detail mode) to add genres, countries and runtime per title.
Can I search for a specific title or director?
Yes. Use search mode with a keyword, or detail mode with subject ids.
What export formats are supported? JSON, CSV, Excel and XML, plus programmatic access through the Apify API.
How does billing work? You pay only per item you get, so costs scale with the number of titles you scrape.
Is the data only public data? Yes — the scraper returns only publicly available title information.
Can I integrate this with other tools? The Douban Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Notes
Original clean-room implementation. Returns only public data; you are responsible for compliance with Douban's terms. Not affiliated with Douban.
Input
| Field | Type | Description |
|---|---|---|
modeMode | string · collection, search, detail | Hot-list collection, keyword search, or details by subject id. Default: "collection" |
collectionCollection | string · movie_hot_gaia, tv_hot, show_hot, tv_domestic, tv_american, tv_korean… | For collection mode: which hot list. Default: "movie_hot_gaia" |
searchQuerySearch query | string | For search mode: keyword (e.g. a title or director). |
subjectIdsSubject ids | array | For detail mode: Douban subject ids (e.g. 37450627). |
enrichDetailsEnrich with full details | boolean | For collection/search: fetch full detail (genres, countries, runtime) per item. Slower. Default: false |
maxItemsMax items | integer | Maximum items to scrape. Default: 100 |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~douban-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/douban-scraper").call(run_input={})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/douban-scraper').call({});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Item scraped One movie/TV/show scraped. | $0.002 | $0.002 |
| API request One Douban API request. | $0.0008 | $0.0008 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Bulk Image Downloader
Download thousands of images from a list of URLs and store each in the key-value store with a public link. Returns content type, size, dimensions and SHA-256 per image. Bulk-ready. Great for datasets, backups and media pipelines.
8,102 runs · 103 users · $0.056 / url processed
Text to Speech
Convert any text to natural-sounding speech as an MP3 download. 300+ premium neural voices across 70+ languages, adjustable rate, pitch and volume. Great for voiceovers, videos, accessibility and audio content. No setup.
278 runs · 22 users · $0.01 / audio generated
Google Maps Email Extractor
Search Google Maps for businesses, then crawl each business website to extract emails, social profiles and extra phone numbers. Turns any Maps search into a ready lead list. No setup.
159 runs · 8 users · $0.006 / business lead scraped
Website Screenshot
Capture full-page or viewport screenshots of any URL as PNG or JPEG, at any device size. For monitoring, previews, thumbnails and automation workflows.
156 runs · 3 users · $0.004 / screenshot captured
Bulk URL Status Checker
Check thousands of URLs over plain HTTP: status codes, broken links (404/410/5xx), full redirect chains, response time, content type, page title and SSL certificate expiry.
154 runs · 13 users · $0.002 / url checked
Google Search Scraper
Scrape Google Search results (organic listings) for any query: title, URL, displayed URL, snippet and position. Multi-query, per-country/language, pagination. Uses Google SERP proxy — reliable, no captcha, no setup.
121 runs · 8 users · $0.001 / result scrapedSend the site and the fields. We build it and you get it first.