Europe PMC Scraper
hipersoft/europepmc-scraper
Bulk-scrape life-science and biomedical literature from Europe PMC (40M+ records: PubMed, PMC, preprints, patents): title, abstract, authors, journal, year, DOI, PMID/PMCID, citation count, MeSH terms, open-access flag and full-text/PDF links. Thousands per run. No setup.
Total users
5Monthly users
1Total runs
325Per article scraped
$0.001Last rebuilt
Oct 28, 2026Overview
Bulk-scrape biomedical and life-science literature from Europe PMC — a 40M+ record index spanning PubMed, PubMed Central, preprints, patents and agricultural literature. Get titles, abstracts, authors, journals, years, DOIs, PMIDs/PMCIDs, citation counts, MeSH terms, open-access flags and direct full-text / PDF links. Thousands of records per run. No account, no API key. Export to JSON, CSV or Excel.
Features
- 🔎 Broad life-science coverage — PubMed + PMC + preprints + patents in one search
- 📄 Full-text & PDF links — direct links where the article is openly available
- 📈 Citation counts —
citedByCountper article - 🏷️ Rich metadata — MeSH terms, keywords, publication types, journal, IDs (DOI/PMID/PMCID)
- 🔓 Open-access filter — restrict to freely readable articles
- 📊 Bulk & cursor-paginated — scales to hundreds of thousands of records per query
What you get
One record per article.
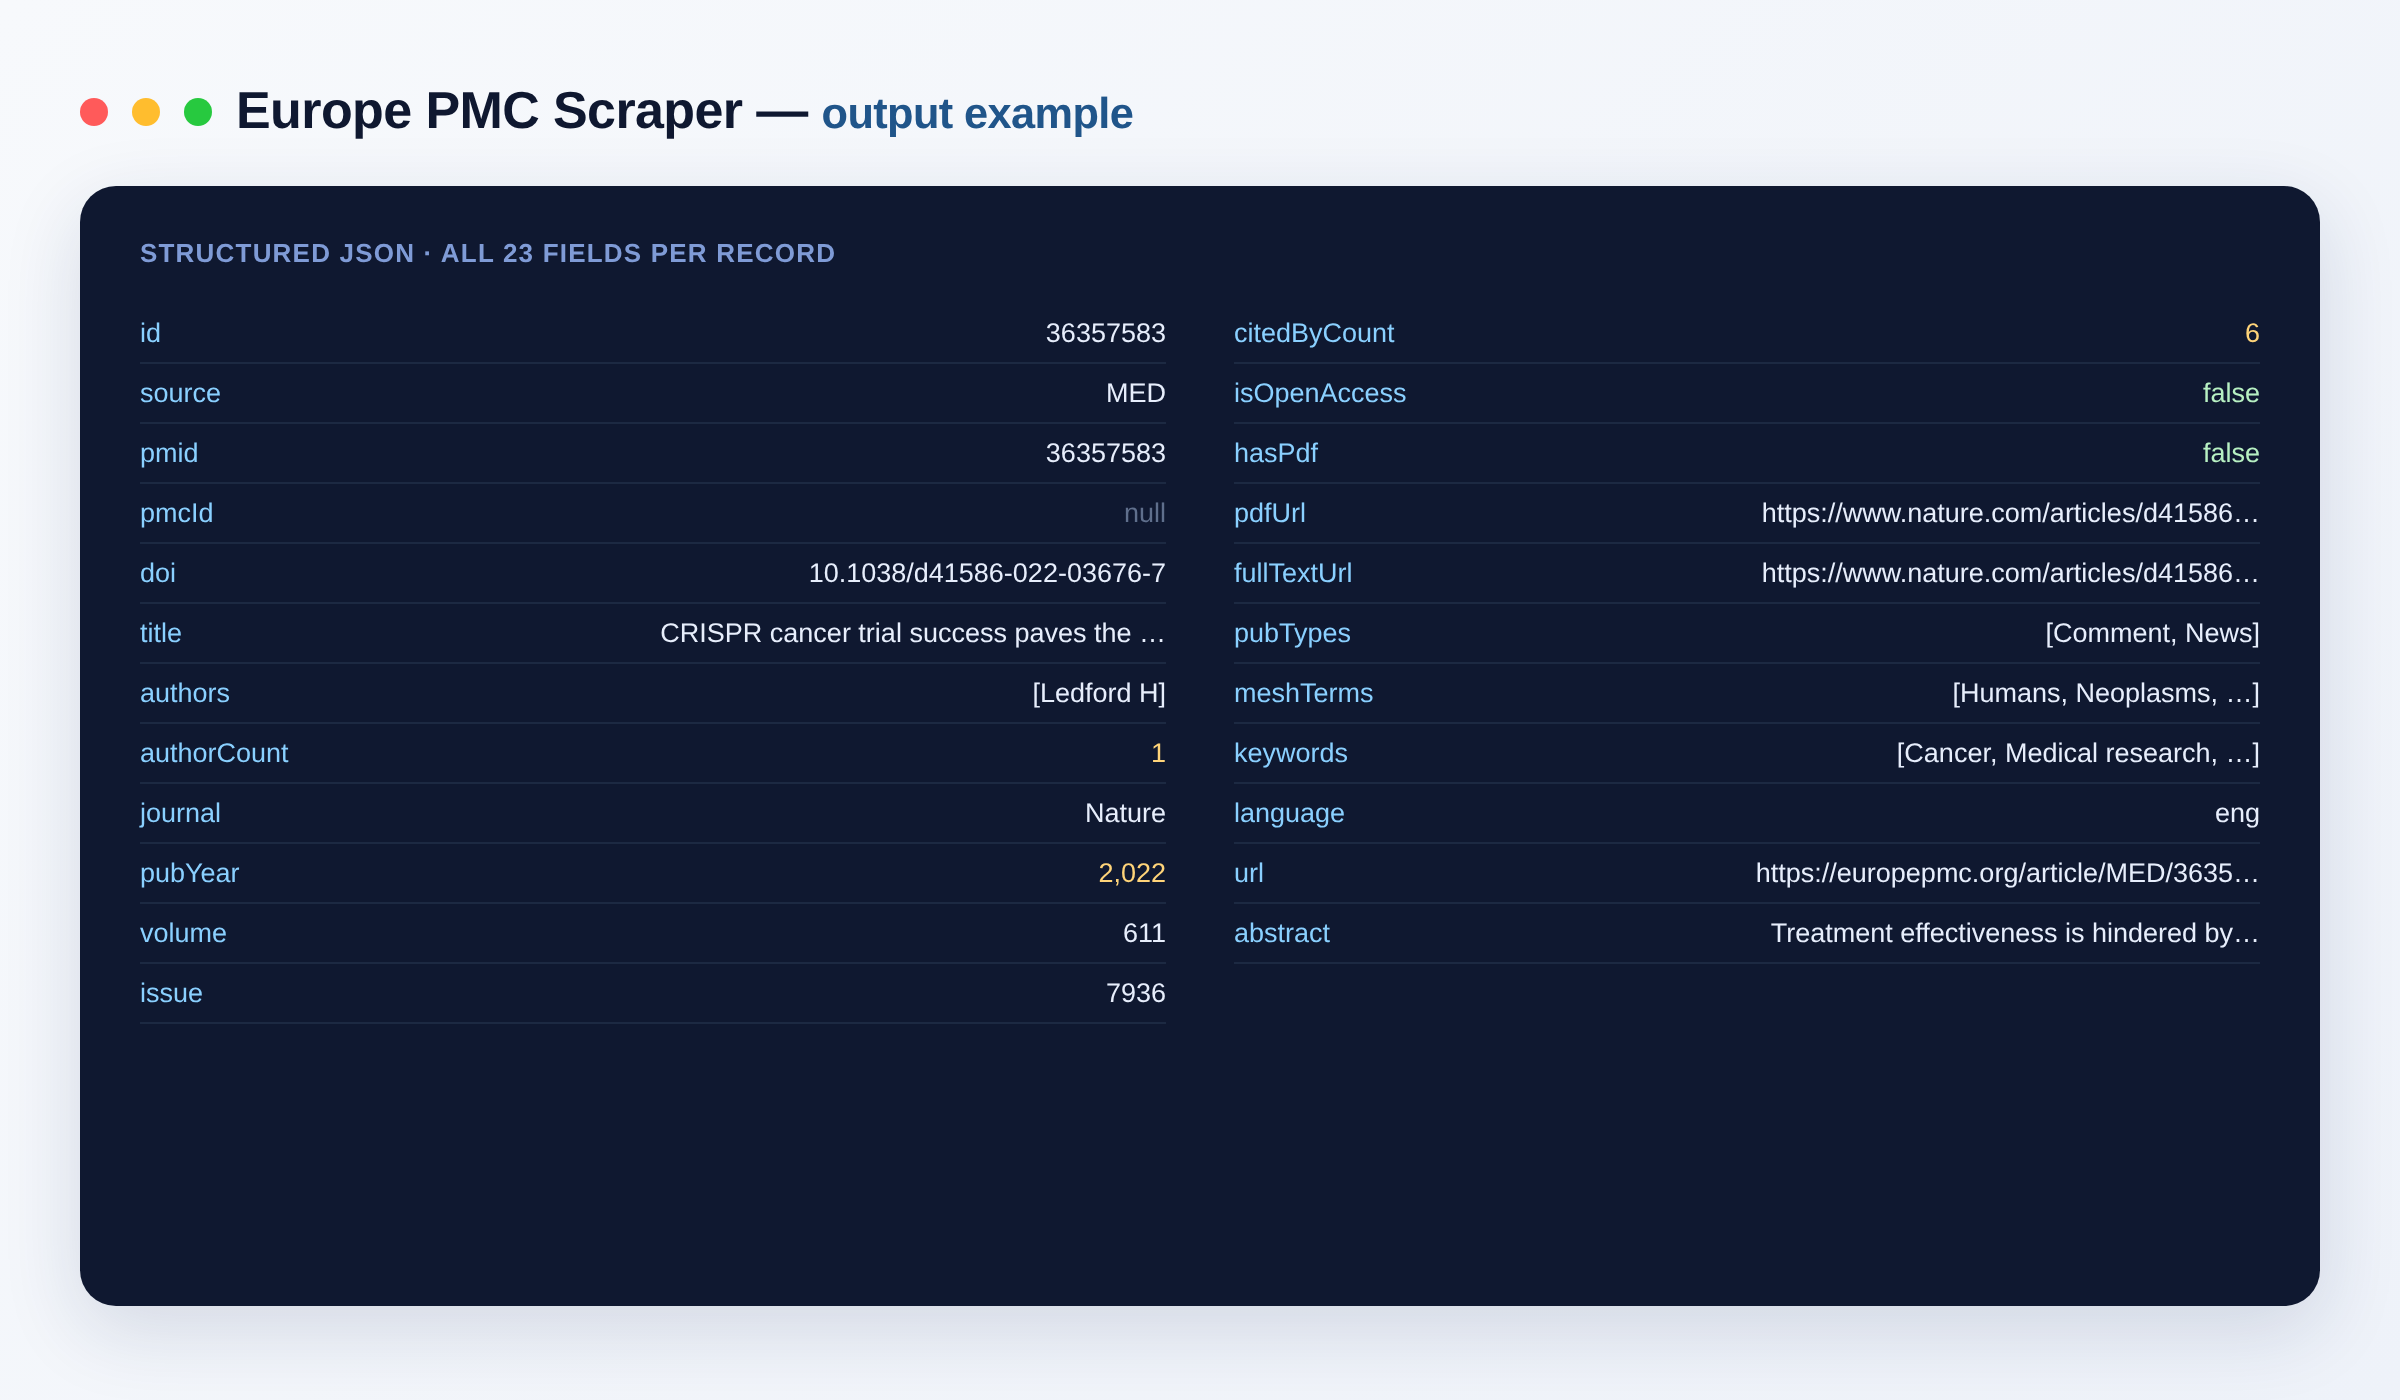
{
  "id": "38512345",
  "source": "MED",
  "pmid": "38512345",
  "pmcId": "PMC10987654",
  "doi": "10.1038/s41586-024-00000-0",
  "title": "…",
  "authors": ["Jane A Smith", "…"],
  "journal": "Nature",
  "pubYear": 2024,
  "citedByCount": 37,
  "isOpenAccess": true,
  "hasPdf": true,
  "pdfUrl": "https://europepmc.org/articles/PMC10987654?pdf=render",
  "fullTextUrl": "https://europepmc.org/articles/PMC10987654",
  "meshTerms": ["…"],
  "url": "https://europepmc.org/article/MED/38512345",
  "abstract": "…"
}
Output schema
| Field | Type | Description |
|---|---|---|
id |
string | Europe PMC internal record ID. |
source |
string | Source database code (e.g. MED, PMC, PPR). |
pmid |
string | PubMed ID. |
pmcId |
string | PubMed Central ID. |
doi |
string | Digital Object Identifier. |
title |
string | Article title. |
authors |
array | List of author names. |
authorCount |
integer | Number of authors. |
journal |
string | Journal or source title. |
pubYear |
integer | Publication year. |
volume |
string | Journal volume. |
issue |
string | Journal issue. |
citedByCount |
integer | Number of citing articles. |
isOpenAccess |
boolean | Whether the article is open access. |
hasPdf |
boolean | Whether a PDF is available. |
pdfUrl |
string (URL) | Direct PDF link where available. |
fullTextUrl |
string (URL) | Full-text (HTML) link where available. |
pubTypes |
array | Publication type labels. |
meshTerms |
array | MeSH subject terms. |
keywords |
array | Author-supplied keywords. |
language |
string | Article language. |
url |
string (URL) | Public Europe PMC article page. |
abstract |
string | Abstract text (when included). |
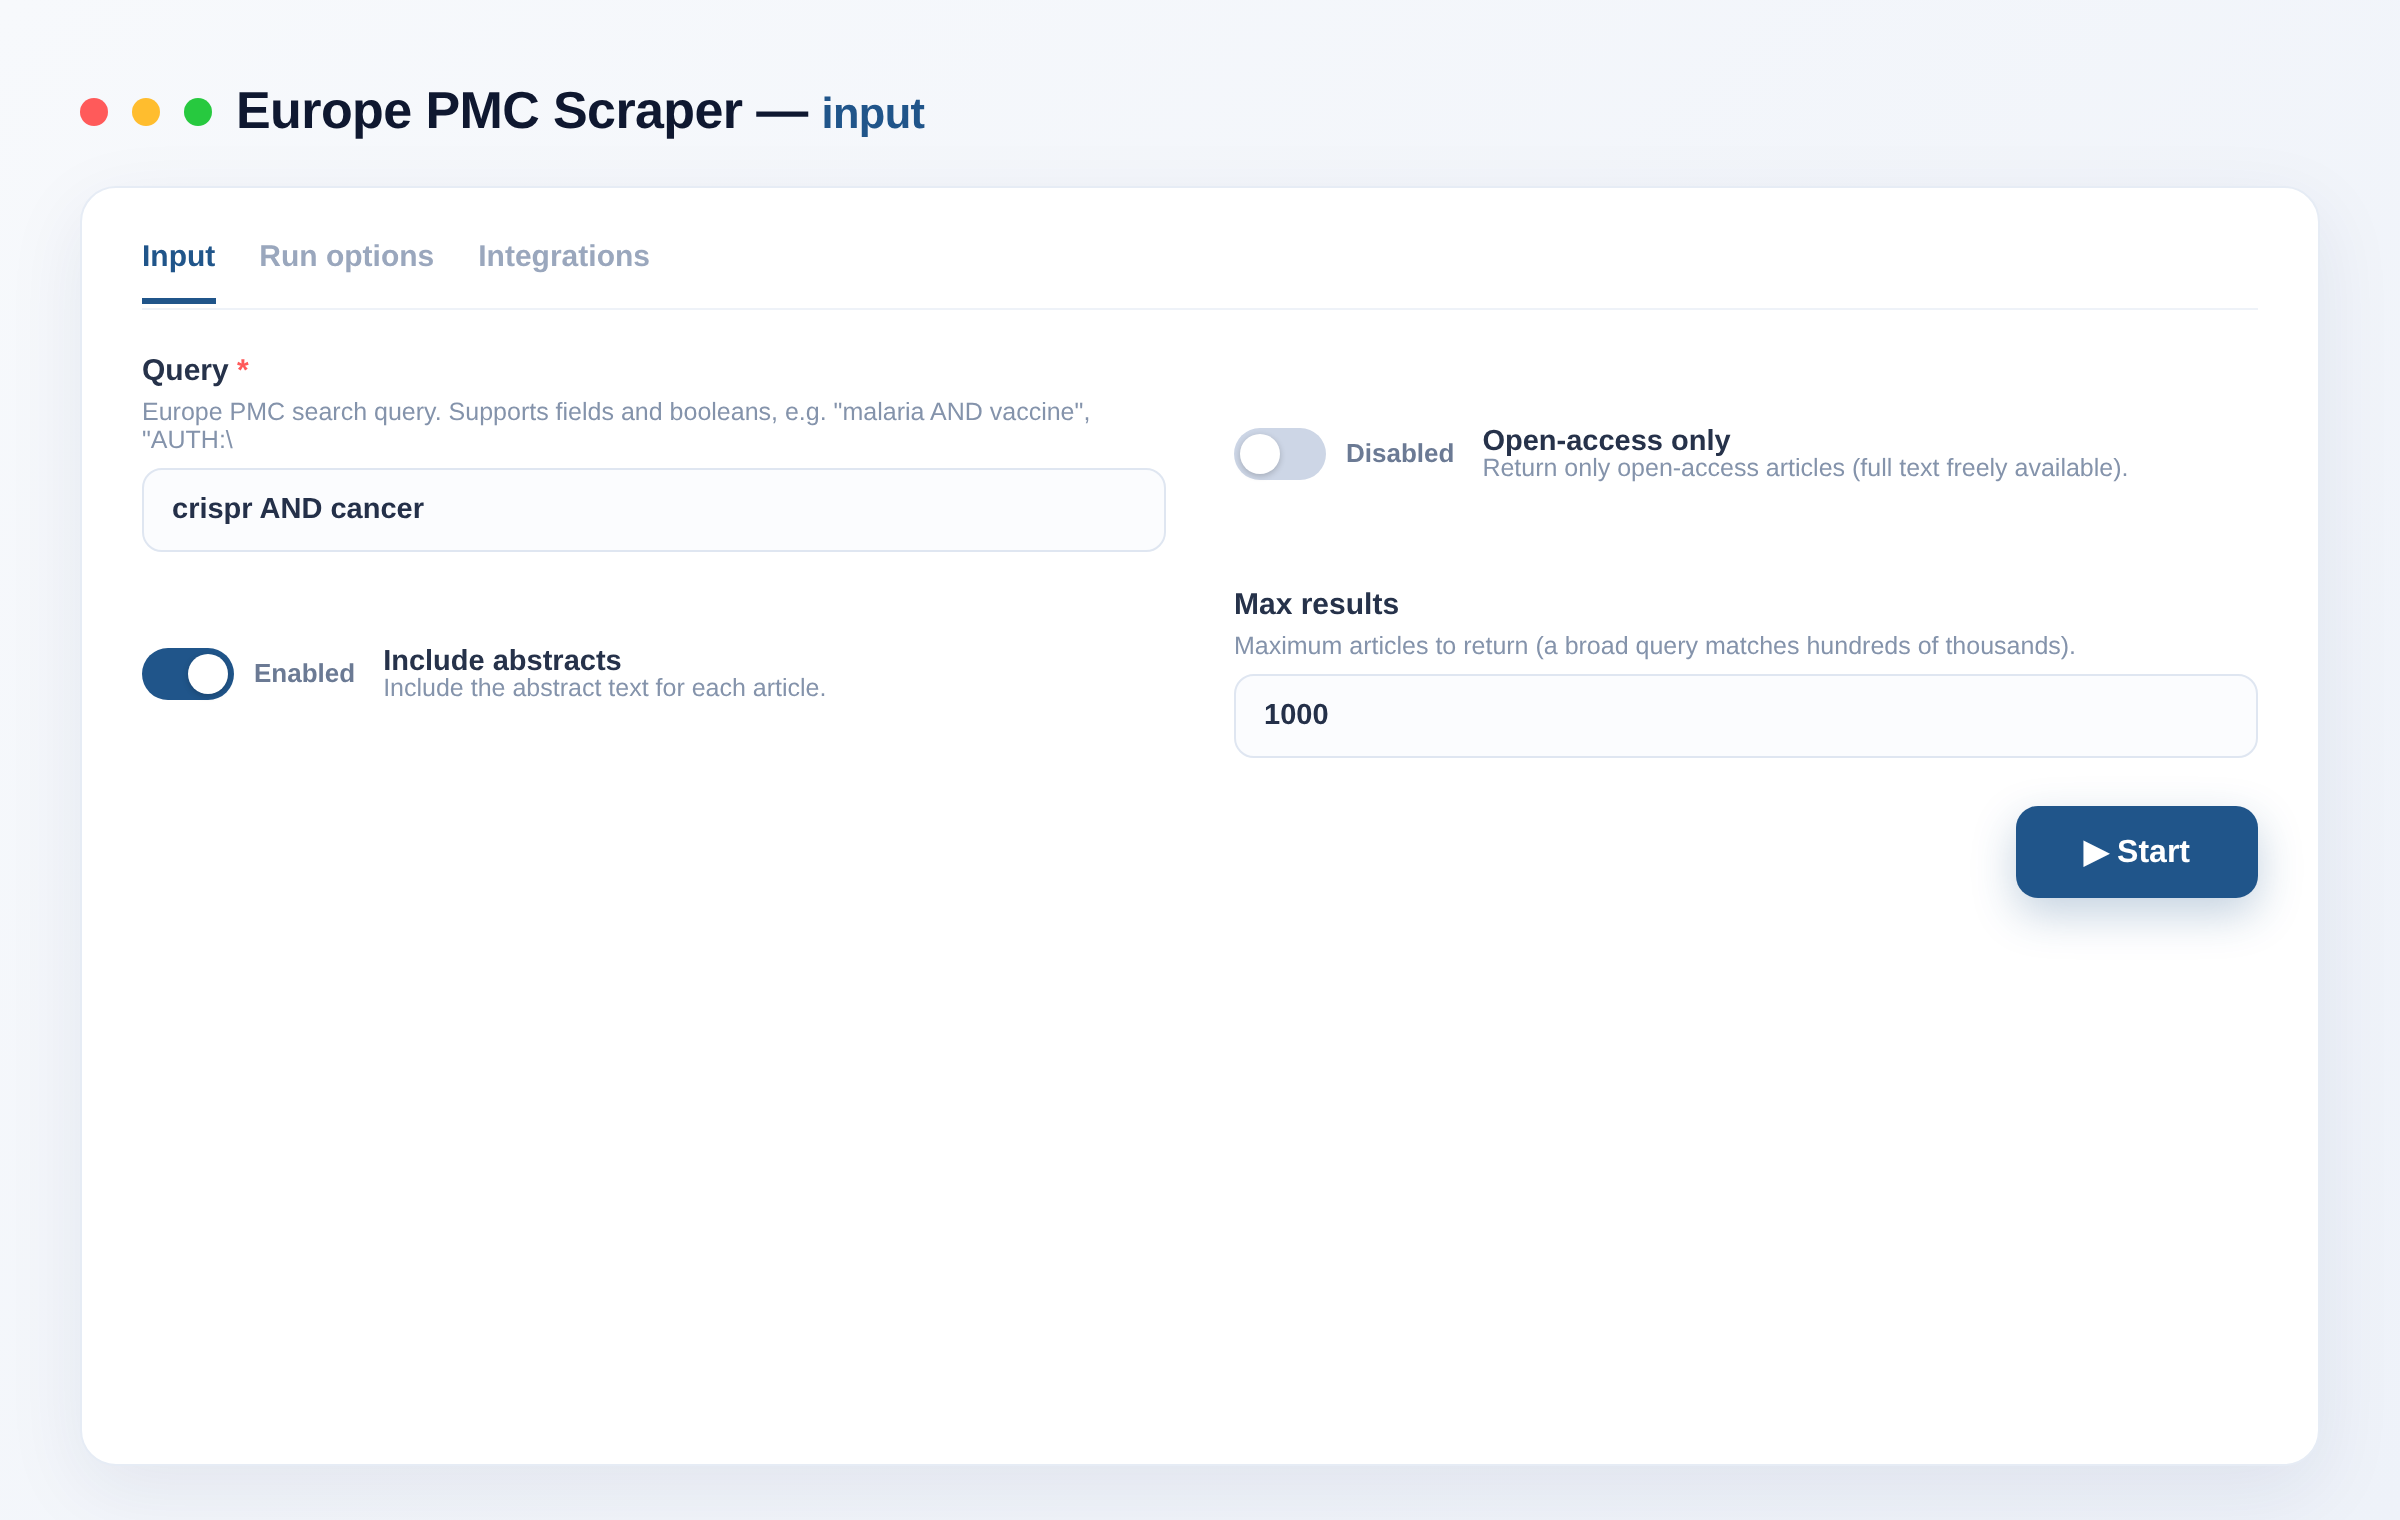
Input
{
  "query": "crispr AND cancer",
  "openAccessOnly": false,
  "maxResults": 5000
}
| Field | Description |
|---|---|
query |
Europe PMC query (supports fields like AUTH:, JOURNAL:, PUB_YEAR:, booleans). |
openAccessOnly |
Only open-access articles. |
includeAbstract |
Include abstract text. |
maxResults |
Max articles to return. |
Use cases
- Systematic & literature reviews — every relevant paper with abstracts and citations
- Full-text mining — grab open-access PDF/HTML links at scale
- Bibliometrics — rank by citations across PubMed + PMC + preprints
- Biomedical datasets — build corpora with MeSH-indexed metadata
Pricing
Pay-per-event: a small amount per article scraped. See the Pricing tab for current rates.
FAQ
Do I need an API key? No. This Actor uses the public Europe PMC REST API — no account, login or API key required.
How many articles can I scrape per run?
Set maxResults as high as you need — the API is cursor-paginated and scales to hundreds of thousands of records per query.
Is scraping Europe PMC legal? Yes. Europe PMC openly publishes its life-science index through a public REST API, and this Actor reads only those openly available records and returns them as-is.
What format is the output? Structured JSON — one record per article — exportable as JSON, CSV or Excel. Each record includes title, abstract, authors, journal, year, DOI, PMID/PMCID, citation count, MeSH terms, open-access flags and direct full-text/PDF links.
Can I filter by open access or use field search?
Yes. Flip openAccessOnly to keep only freely readable articles, and the query field supports Europe PMC syntax like AUTH:, JOURNAL:, PUB_YEAR: and booleans.
Can I connect this Actor to other apps? The Europe PMC Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Building a biomedical literature dataset? These other hipersoft scrapers pair well with this one:
- PubMed Scraper — biomedical papers, abstracts and MeSH terms from the NLM index
- ClinicalTrials.gov Scraper — bulk clinical trial records, sponsors and locations
- OpenAlex Scraper — 250M+ scholarly works with citations and abstracts
- Crossref Scraper — DOIs, citation counts and metadata from 150M+ works
Notes
Uses the public Europe PMC REST API. Returns its openly-available metadata as-is. This is an independent tool and is not affiliated with or endorsed by Europe PMC or EMBL-EBI.
Input
| Field | Type | Description |
|---|---|---|
query requiredQuery | string | Europe PMC search query. Supports fields and booleans, e.g. "malaria AND vaccine", "AUTH:\"Doudna\"", "cancer AND PUB_YEAR:2023". |
openAccessOnlyOpen-access only | boolean | Return only open-access articles (full text freely available). Default: false |
includeAbstractInclude abstracts | boolean | Include the abstract text for each article. Default: true |
maxResultsMax results | integer | Maximum articles to return (a broad query matches hundreds of thousands). Default: 1000 |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~europepmc-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "query": "crispr AND cancer"
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/europepmc-scraper").call(run_input={
"query": "crispr AND cancer"
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/europepmc-scraper').call({
"query": "crispr AND cancer"
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Article scraped One life-science article with metadata and abstract | $0.001 | $0.0005 |
| API request One Europe PMC page request | $0.0005 | $0.0005 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
arXiv Papers Scraper
Search and extract arXiv papers: title, abstract, authors, categories, published/updated dates, DOI, journal reference, and direct PDF links. Filter by category and sort by newest, recently updated or relevance. Fetch by arXiv ID too. For research, lit reviews and AI/ML monitoring. No setup.
140 runs · 2 users · $0.0025 / paper scraped
Letterboxd Scraper
Scrape Letterboxd films with ratings, rating counts, genres, director, cast, runtime and synopsis. Feed it film pages, a user's films/watchlist/diary, any list URL, or browse pages. For film data, recommendations and research.
139 runs · 7 users · $0.0042 / film scraped
OpenLibrary Book Scraper
Search millions of books on OpenLibrary by keyword, author, subject or ISBN and get title, authors, publisher, year, subjects, ISBNs, edition count, ratings, page count and cover. Clean, no setup.
124 runs · 5 users · $0.002 / book scraped
Semantic Scholar Scraper
Bulk-scrape academic papers from Semantic Scholar's 200M+ corpus: title, abstract, AI TLDR summary, authors, venue, year, citation & influential-citation counts, fields of study, DOI/PubMed/arXiv IDs and open-access PDF links. Filter by year, field and citations. Thousands per run. No setup.
123 runs · 7 users · $0.001 / paper scraped
Wikipedia Scraper
Search Wikipedia or look up exact articles and get the full plain-text content, summary, categories, image, Wikidata ID and monthly pageview trends. Any language. Great for research, RAG and AI datasets. No setup.
121 runs · 1 users · $0.001 / article scraped
OpenAlex Scholarly Works Scraper
Search 250M+ academic papers via OpenAlex: title, abstract, authors, institutions, venue, citation count, DOI, open-access status and topics. Filter by year, type and open access. For research, R&D and lit reviews. No setup.
118 runs · 1 users · $0.001 / work scrapedSend the site and the fields. We build it and you get it first.