Dice Job Scraper
hipersoft/dice-scraper
Scrape tech job listings from Dice.com: title, company, location, salary, remote/visa flags, and full job descriptions. Fast, reliable.
Total users
2Monthly users
1Total runs
124Per job scraped
$0.001Last rebuilt
Oct 28, 2026Overview
Dice Jobs Scraper extracts tech job listings from Dice.com by keyword and location and returns clean, structured JSON — title, company, location, salary, employment type, posted date, sponsored flag and the apply link. Export to JSON, CSV, Excel or XML. Fast and reliable, with no account or API key to set up. Built for recruiters, job-board operators and anyone researching the tech labor market.
What does the Dice Scraper do?
This Dice crawler walks each search across multiple pages, de-duplicates by Dice's jobId, and returns every matching role as a structured record. Give it keywords and locations and export a fresh tech-jobs dataset for your board, CRM or research pipeline.
What data can you scrape from Dice?
| Data point | Description |
|---|---|
| Role | title, employmentType, summary |
| Company | company |
| Location | location |
| Pay | salary |
| Posting | posted, featured |
| Links | url |
| Source | jobId |
What you get
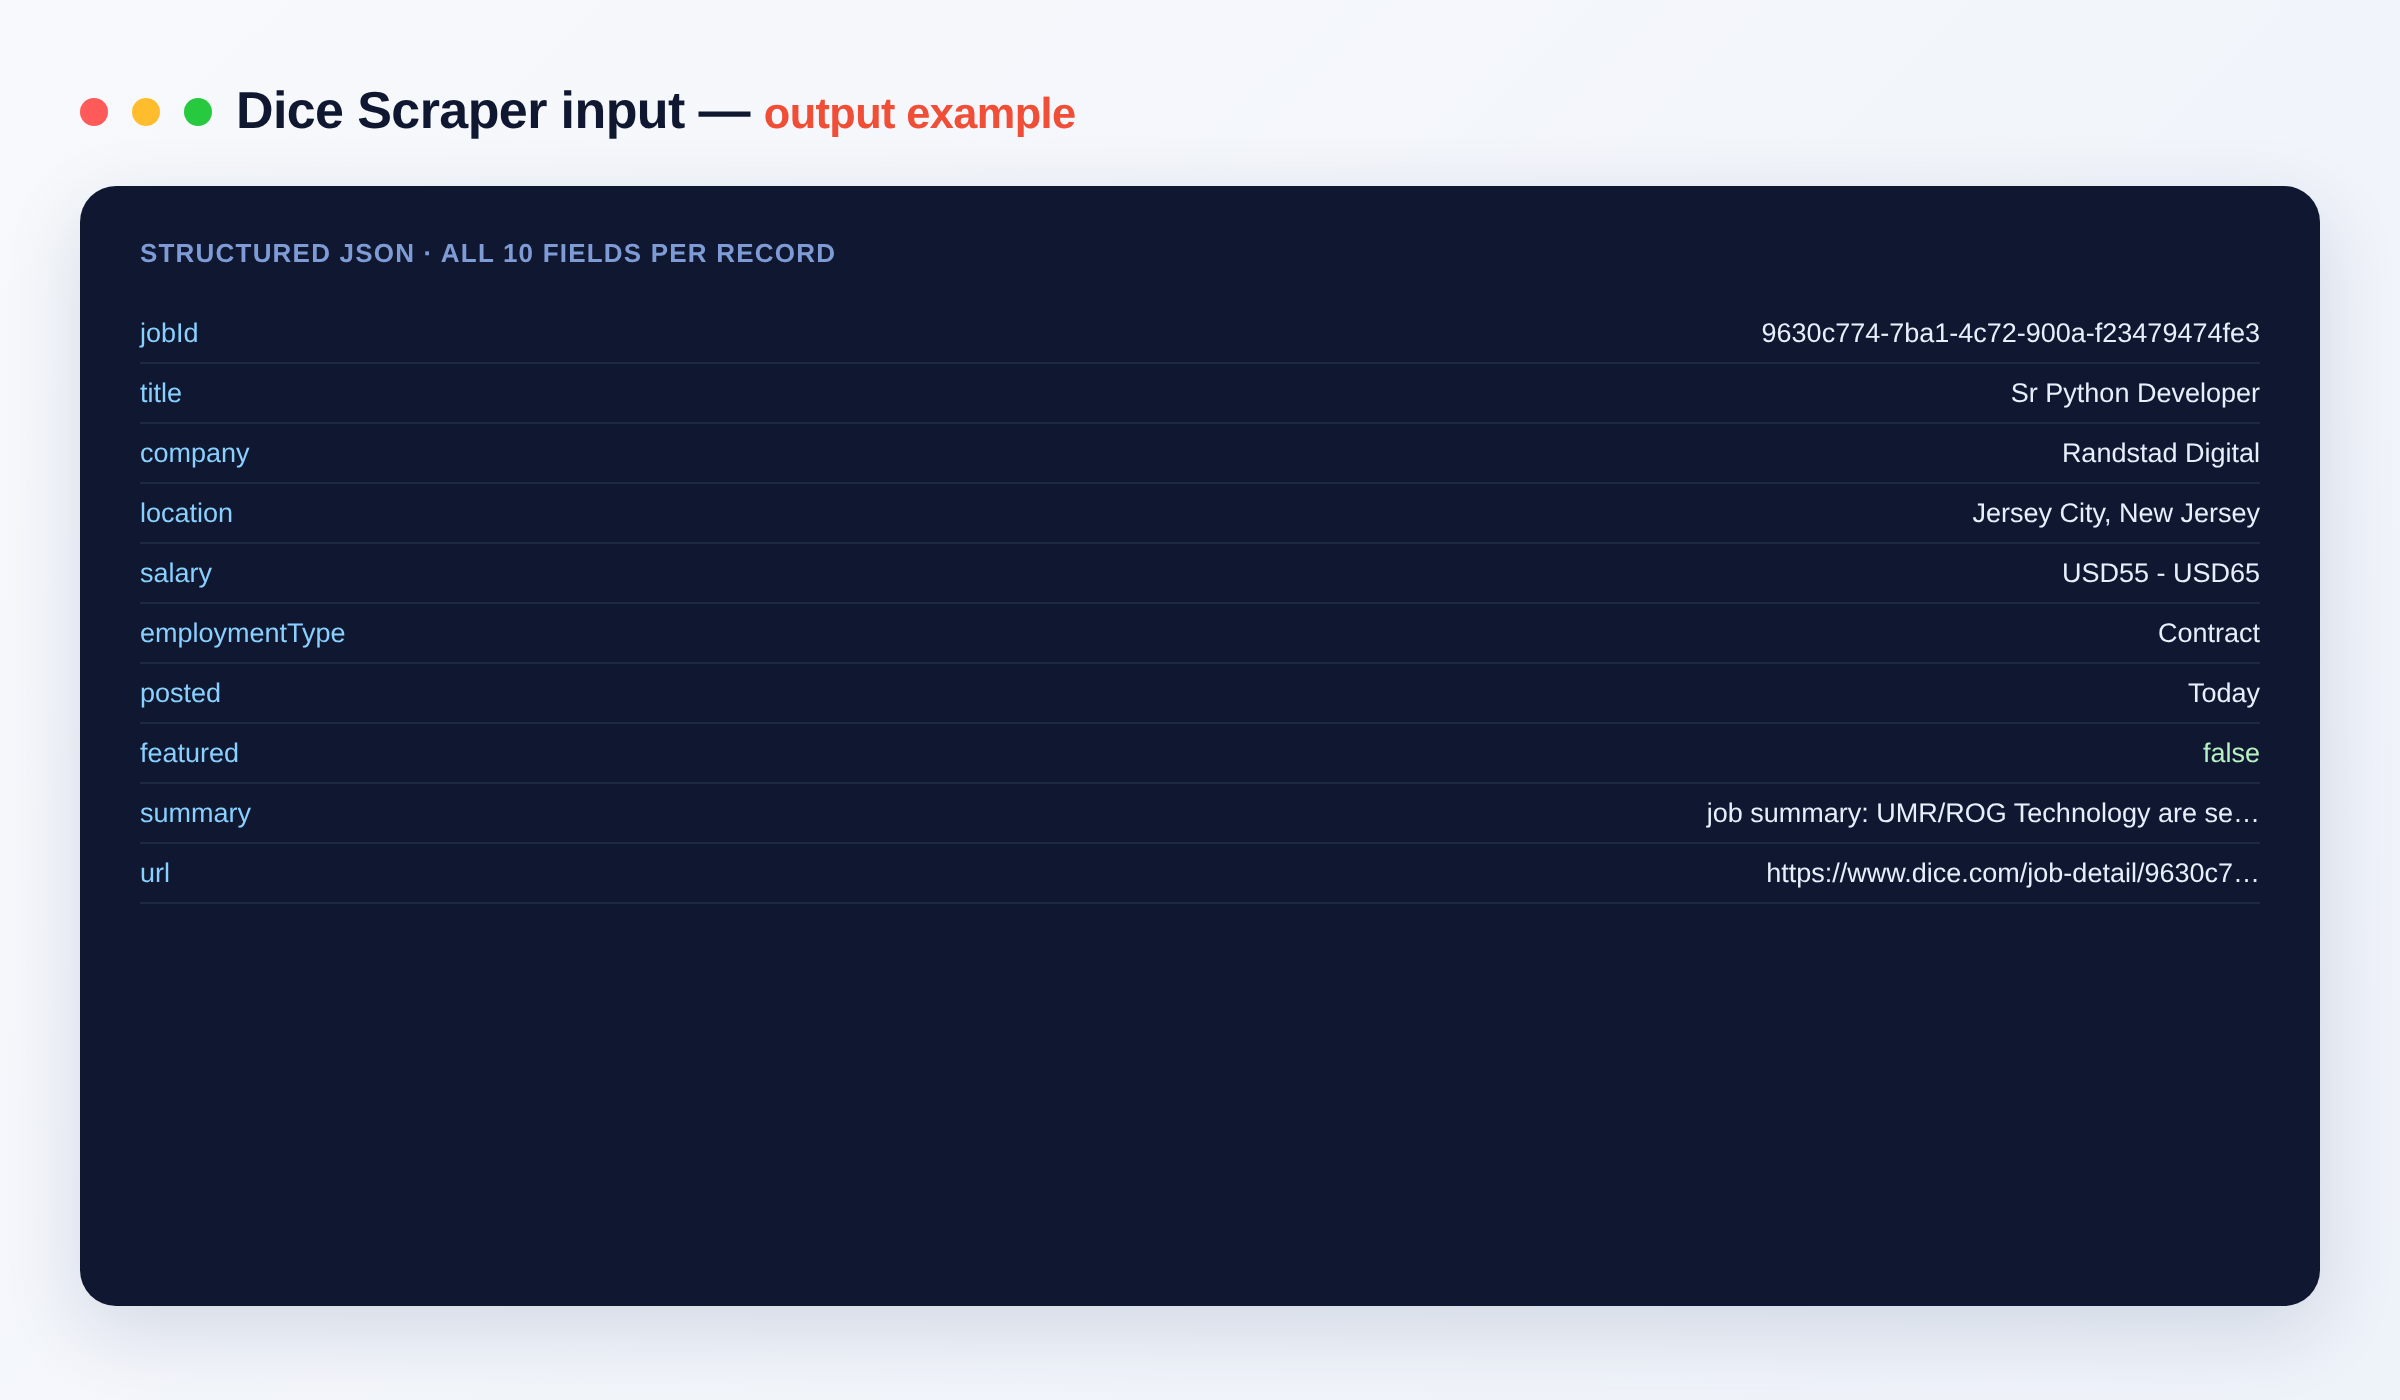
Every job becomes one clean dataset record. Export the full table to JSON, CSV, Excel or XML.
{
  "jobId": "a1b2c3d4-0000-1111-2222-333344445555",
  "title": "Senior Software Engineer",
  "company": "Acme Technologies",
  "location": "Remote",
  "salary": "$140,000 - $170,000",
  "employmentType": "Full-time",
  "posted": "2 days ago",
  "featured": false,
  "summary": "We're hiring a senior engineer to build and scale our backend platform...",
  "url": "https://www.dice.com/job-detail/a1b2c3d4-0000-1111-2222-333344445555"
}
Output schema
| Field | Type | Description |
|---|---|---|
jobId |
string | Dice's unique identifier for the job, used to de-duplicate results. |
title |
string | Job title. |
company |
string | Hiring company name. |
location |
string | Location of the role (city, state or Remote). |
salary |
string | Salary or pay range as listed on the card, when available. |
employmentType |
string | Employment type such as full-time or contract. |
posted |
string | How long ago the job was posted (e.g. 2 days ago). |
featured |
boolean | Whether the listing is a sponsored/paid placement. |
summary |
string | Short description snippet from the job card. |
url |
string (URL) | Direct link to the job detail and apply page. |
Use cases
- Build or refresh a tech job board with fresh, salaried Dice listings.
- Source candidates by collecting roles for a specific stack in a target city.
- Track tech salary ranges and employment types across markets over time.
- Feed a labor-market or compensation dashboard with structured hiring data.
- Monitor how many roles a competitor is posting on Dice.
How to scrape Dice data
- Add the Dice Jobs Scraper to your Apify account and open its input.
- Enter searches as
"keyword|location"undersearches, or paste a full Dice jobs URL. - Set
maxPagesPerSearchandmaxItemsto control depth and total volume. - Click Run and let it paginate through every search.
- Export the results as JSON, CSV, Excel or XML, or pull them via the Apify API.
Input
{
  "searches": ["software engineer|Remote", "data scientist|New York, NY"],
  "maxItems": 200,
  "maxPagesPerSearch": 10
}
| Field | Description |
|---|---|
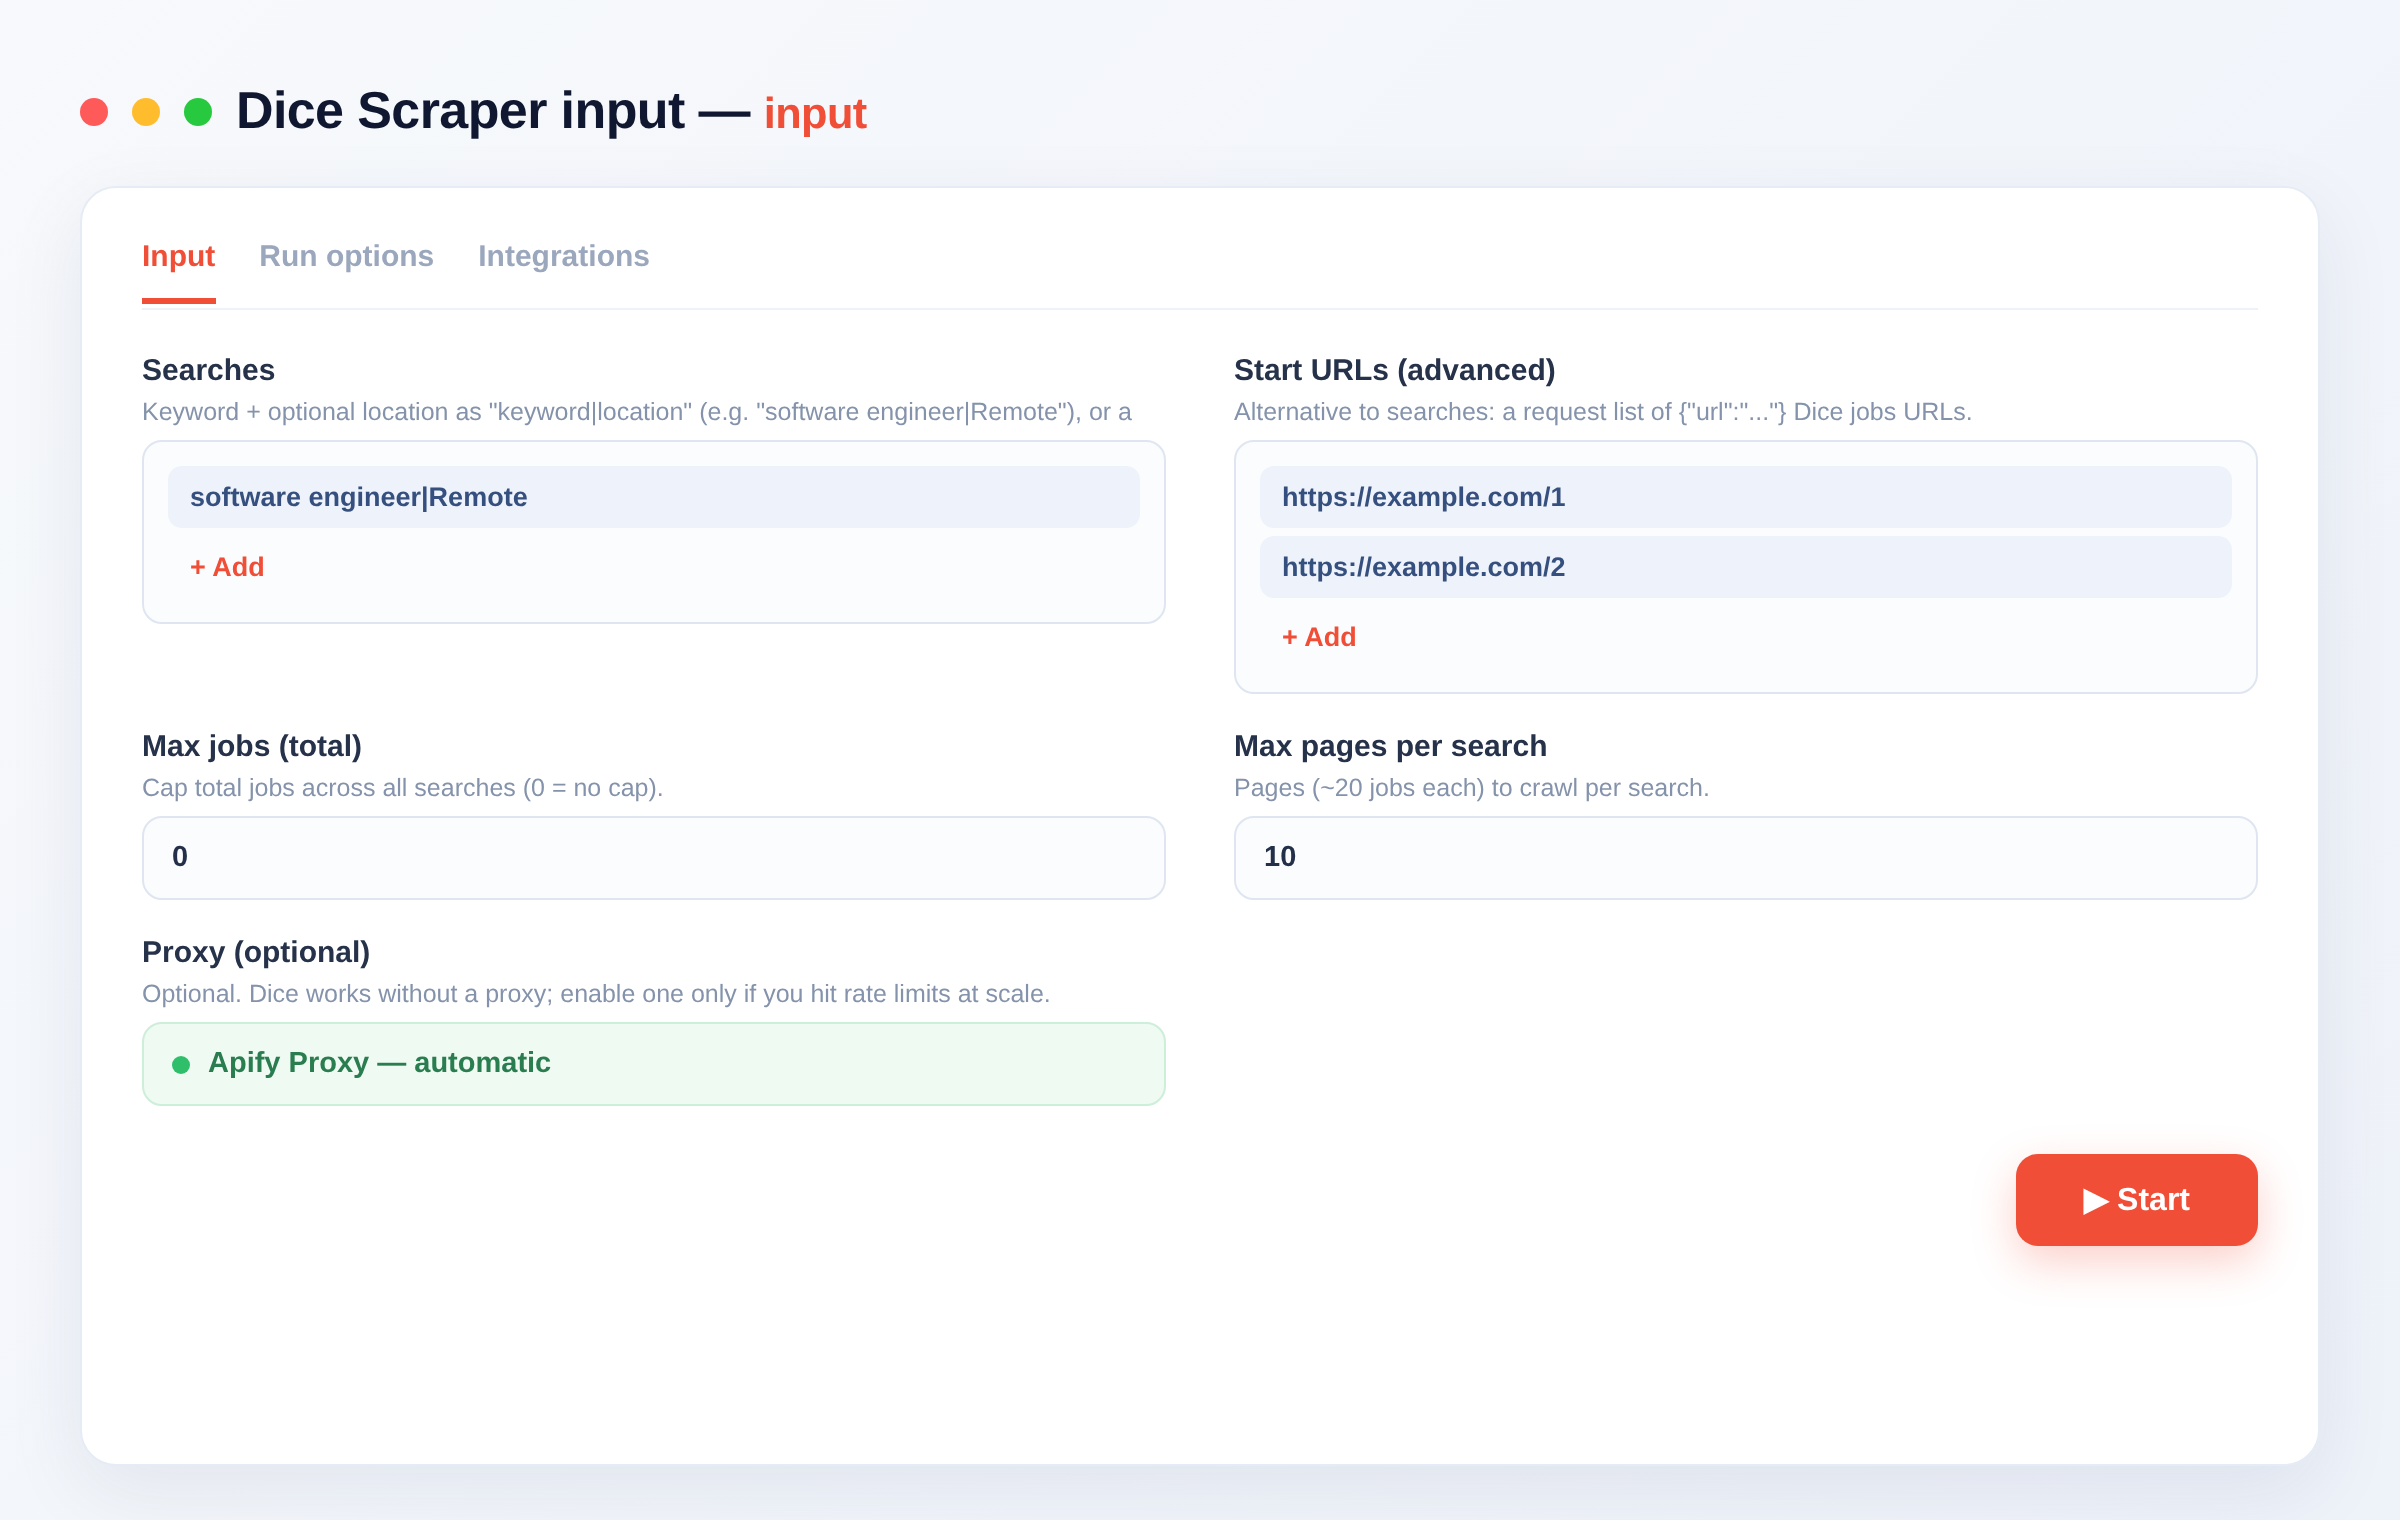
searches |
Keyword + optional location as "keyword|location", or a full Dice jobs URL. One per line. |
startUrls |
Advanced alternative: a request list of {"url":"..."} Dice jobs URLs. |
maxItems |
Cap on total jobs across all searches (0 = no cap). |
maxPagesPerSearch |
Pages (~20 jobs each) to crawl per search. |
proxyConfiguration |
Optional proxy settings for the run. |
Need more jobs data?
- Company Careers Job Scraper — open roles from Greenhouse, Lever and Ashby career pages.
- Reed Job Scraper — UK jobs from Reed.co.uk with salaries and full descriptions.
- RemoteOK Job Scraper — remote roles with tags and salary ranges.
- Remote Jobs Aggregator — five remote boards merged and de-duplicated.
FAQ
Do I need a Dice account or API key? No. Just add your search terms or a Dice jobs URL and run — no login or API key.
How many jobs can I get per run?
Each Dice search page holds roughly 20 jobs. Use maxPagesPerSearch to control how deep it paginates and maxItems to cap the total across all your searches.
Can I filter by location or keyword?
Yes. Pass searches as "keyword|location" (e.g. "software engineer|Remote"), or drop in a full dice.com/jobs URL with the filters you want.
What export formats are supported? JSON, CSV, Excel and XML, plus programmatic access through the Apify API.
How does billing work? You pay per item you get, so cost scales with the number of jobs you actually collect. See the Pricing tab for current rates.
Can I connect this to other tools? The Dice Jobs Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Is scraping Dice legal? The scraper only reads publicly available listings that Dice serves to any visitor. You are responsible for reviewing Dice's Terms of Service and your local regulations for your use case.
Notes
Original clean-room implementation. Returns only public listings Dice serves to any visitor. Not affiliated with Dice or DHI Group; "Dice" is a trademark of its respective owner.
Input
| Field | Type | Description |
|---|---|---|
searchesSearches | array | Keyword + optional location as "keyword|location" (e.g. "software engineer|Remote"), or a full dice.com/jobs URL. One per line. |
startUrlsStart URLs (advanced) | array | Alternative to searches: a request list of {"url":"..."} Dice jobs URLs. |
maxItemsMax jobs (total) | integer | Cap total jobs across all searches (0 = no cap). Default: 0 |
maxPagesPerSearchMax pages per search | integer | Pages (~20 jobs each) to crawl per search. Default: 10 |
proxyConfigurationProxy (optional) | object | Optional. Dice works without a proxy; enable one only if you hit rate limits at scale. Default: {"useApifyProxy": false} |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~dice-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "searches": [
    "software engineer|Remote"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/dice-scraper").call(run_input={
"searches": [
"software engineer|Remote"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/dice-scraper').call({
"searches": [
"software engineer|Remote"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Job scraped One job listing scraped with company, location, salary, remote and visa flags | $0.001 | $0.0005 |
| Description scraped Full job description text and structured salary for one job | $0.004 | $0.004 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Dribbble Shots Scraper
Scrape public design shots from Dribbble: title, high-res image, tags, likes, views and designer credit. Filter by category or sort, export JSON, CSV or Excel.
359 runs · 5 users · $0.003 / shot scraped
Computrabajo Scraper
Scrape Computrabajo job listings across Latin America (Mexico, Colombia, Argentina, Chile, Peru and more): title, company, location, salary, posted date and apply URL. Filter by country and keyword. No setup.
206 runs · 4 users · $0.002 / listing scraped
Kraken Market Data Scraper
Fetch Kraken spot market data in bulk: ticker stats (ask, bid, last, 24h high/low/volume/vwap), OHLC candles for any interval, order book depth (top bids/asks), and tradable pair metadata. Fast, clean and cheap.
165 runs · 4 users · $0.001 / pair scraped
Bayt Scraper
Scrape Bayt.com job listings across the Middle East (UAE, Saudi Arabia, Egypt, Qatar and more): title, company, location, posted date and apply URL. Filter by country and keyword.
134 runs · 4 users · $0.003 / job scraped
GitHub Scraper
Search GitHub and scrape repositories (stars, forks, language, topics, license, dates) or user profiles (name, company, location, bio, followers, public email, repos). Uses the GitHub REST API; optional token for higher rate limits. For developer lead generation, OSS research and recruiting.
131 runs · 7 users · $0.0008 / item scraped
Hacker News Scraper
Scrape Hacker News stories, comments, Ask HN, Show HN, jobs and polls by keyword, points, comments and date range. Sort by relevance or newest. Title, URL, author, points, comment count, text and HN link. Fast clean HTTP via the HN Algolia API, no setup.
130 runs · 2 users · $0.004 / item scrapedSend the site and the fields. We build it and you get it first.