GitHub Scraper
hipersoft/github-scraper
Search GitHub and scrape repositories (stars, forks, language, topics, license, dates) or user profiles (name, company, location, bio, followers, public email, repos). Uses the GitHub REST API; optional token for higher rate limits. For developer lead generation, OSS research and recruiting.
Total users
7Monthly users
3Total runs
131Per item scraped
$0.0008Last rebuilt
Oct 28, 2026Overview
Search GitHub and scrape repositories (stars, forks, language, topics, license, dates) or user profiles (name, company, location, bio, followers, public email, repos) into clean, structured JSON. It uses the official GitHub REST API and works out of the box with no login — add an optional token for higher rate limits. Built for developer lead generation, open-source research and technical recruiting.
Features
- 🔀 Two modes — search
repositoriesoruserswith the same powerful GitHub query syntax. - 🔎 Full query power — use qualifiers like
stars:>10000 language:typescriptorlocation:berlin followers:>500. - ⭐ Repo metrics —
stars,forks,watchers,openIssues,language,topics,licenseand activity dates. - 👤 Profile enrichment — optionally fetch each user's full profile for
email,company,followersandbio. - ↕️ Sort & order — sort repos by stars/forks/updated or users by followers/repositories/joined, ascending or descending.
- 🔑 Optional token — supply a personal access token for ~5000 requests/hour instead of unauthenticated limits.
- ⚙️ Reliable by design — respects rate-limit resets and retries on 403/429 so large runs complete cleanly.
What you get
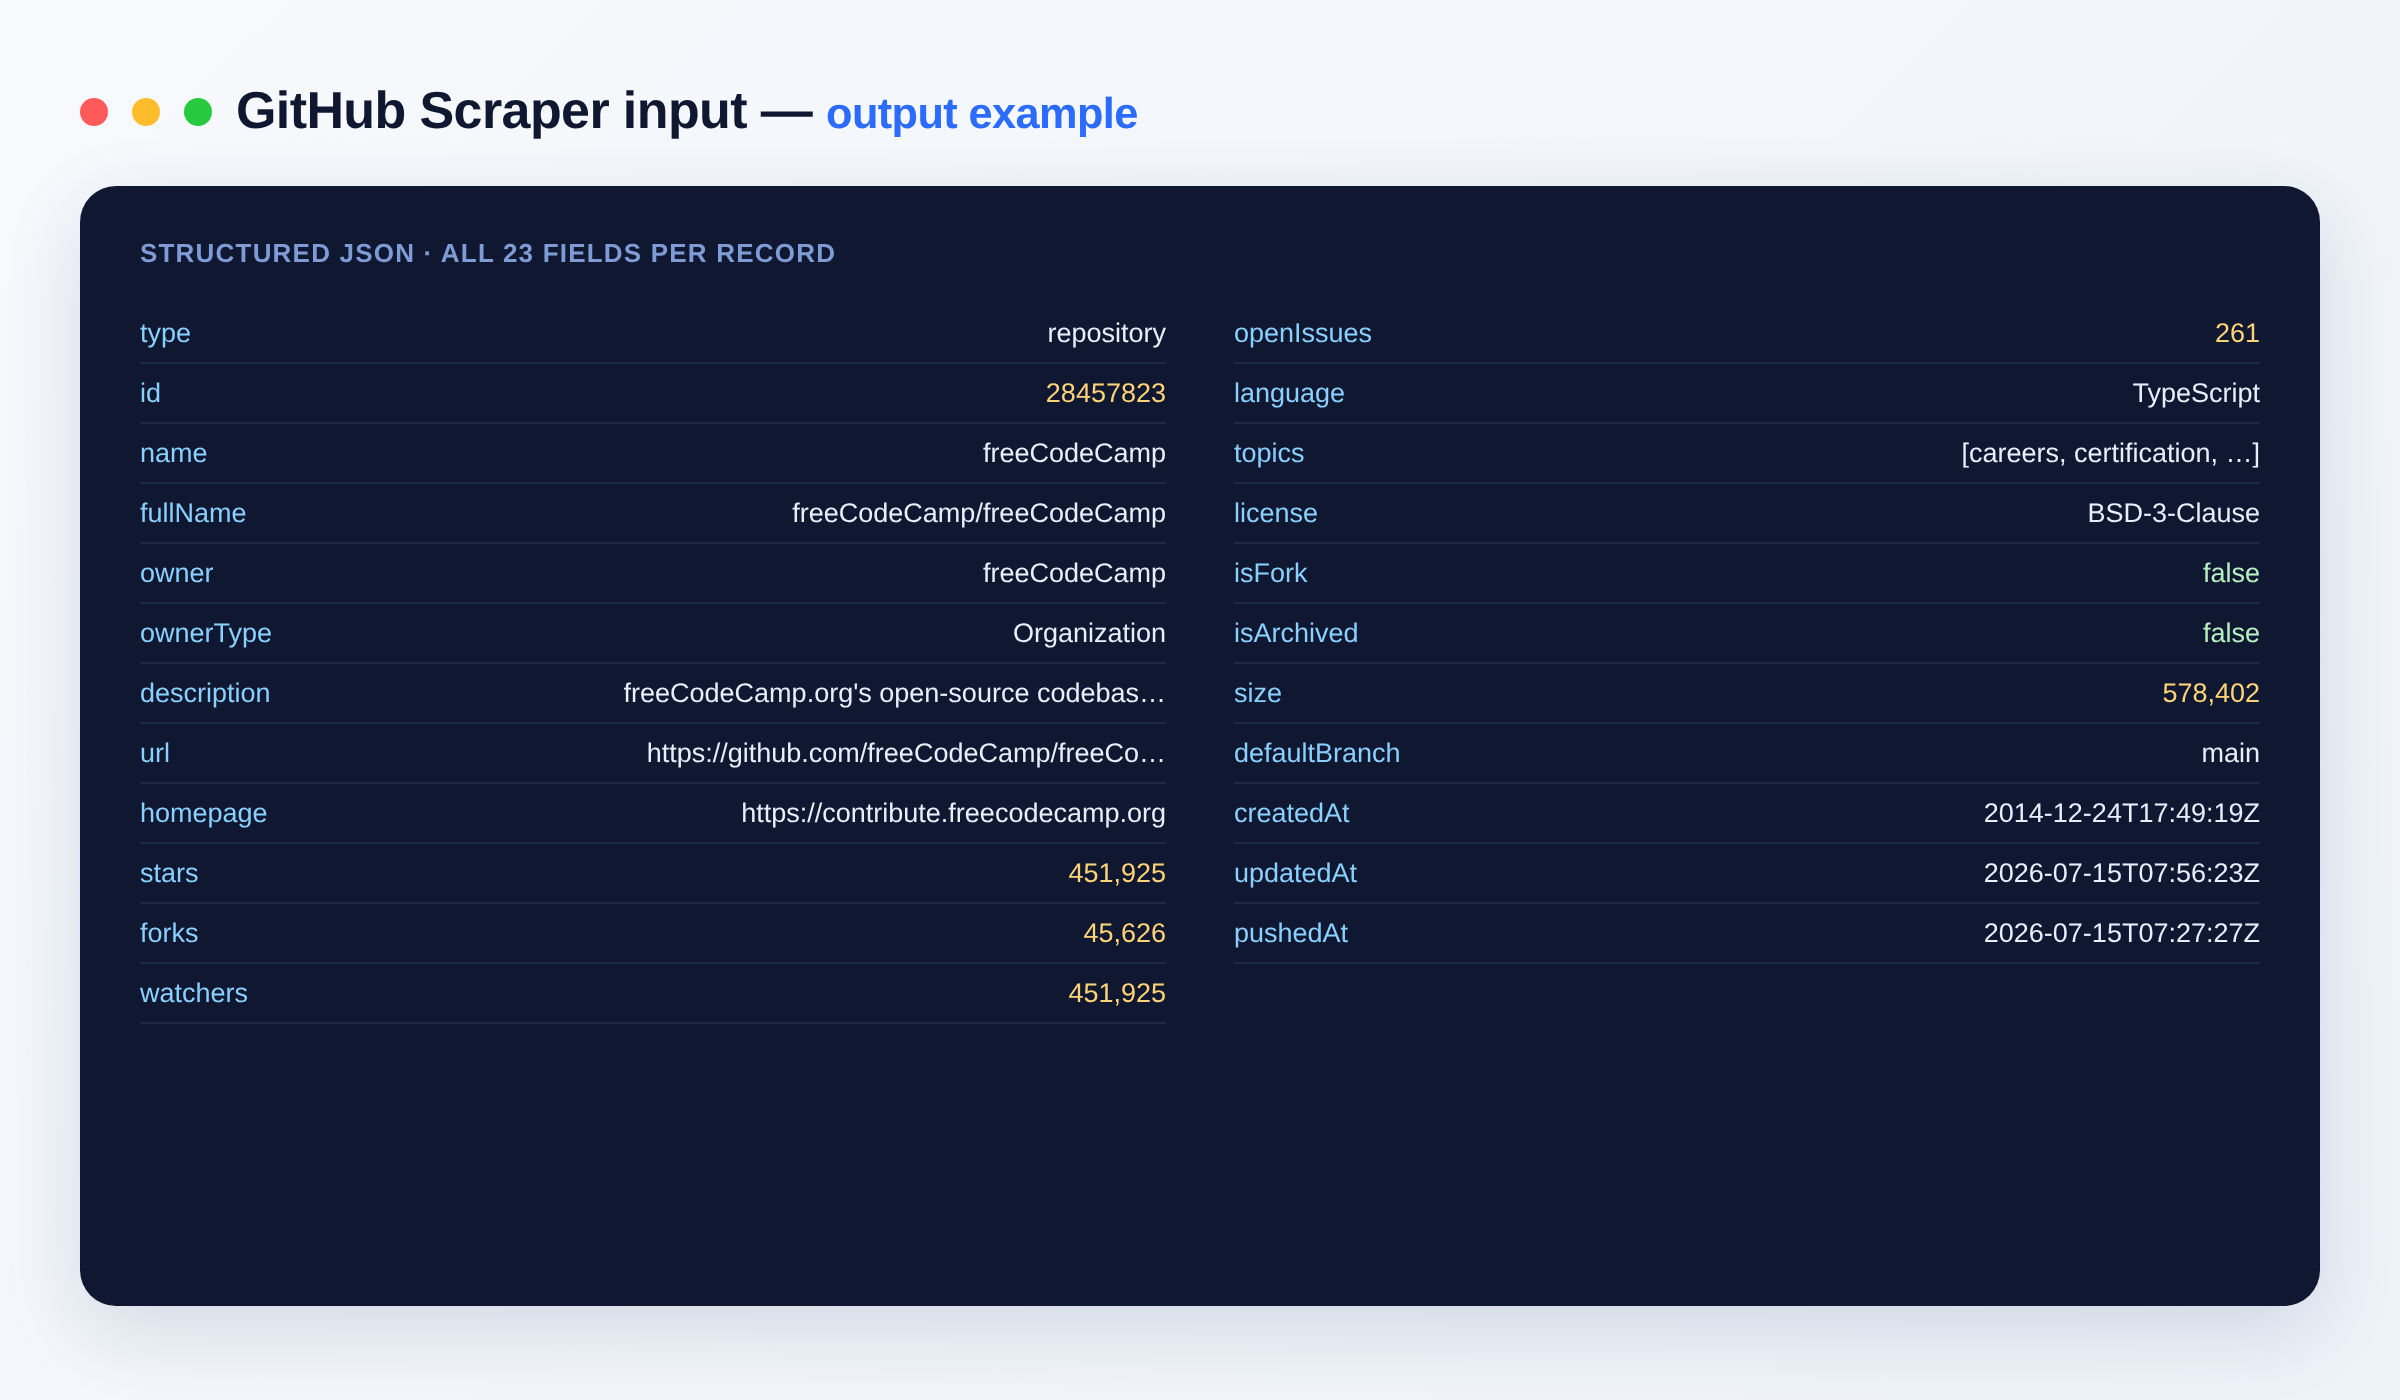
Repository mode returns one clean JSON record per repo:
{
  "type": "repository",
  "id": 20929025,
  "name": "TypeScript",
  "fullName": "microsoft/TypeScript",
  "owner": "microsoft",
  "ownerType": "Organization",
  "description": "TypeScript is a superset of JavaScript that compiles to clean JavaScript output.",
  "url": "https://github.com/microsoft/TypeScript",
  "homepage": "https://www.typescriptlang.org",
  "stars": 99123,
  "forks": 12987,
  "watchers": 99123,
  "openIssues": 5721,
  "language": "TypeScript",
  "topics": ["typescript", "javascript", "compiler"],
  "license": "Apache-2.0",
  "isFork": false,
  "isArchived": false,
  "size": 1234567,
  "defaultBranch": "main",
  "createdAt": "2014-06-17T15:28:39Z",
  "updatedAt": "2024-05-30T08:11:02Z",
  "pushedAt": "2024-05-30T07:59:41Z"
}
In users mode each record instead includes login, name, company, location, email, blog, twitter, hireable, followers, following, publicRepos, publicGists and bio.
Output schema (repositories mode)
Every repository record contains these fields:
| Field | Type | Description |
|---|---|---|
type |
string | Record type — repository. |
id |
integer | GitHub's numeric repository ID. |
name |
string | Repository name, e.g. TypeScript. |
fullName |
string | Owner and name, e.g. microsoft/TypeScript. |
owner |
string | Owner login (user or organization). |
ownerType |
string | User or Organization. |
description |
string | The repository's short description. |
url |
string (URL) | Public GitHub URL of the repository. |
homepage |
string (URL) | Project homepage, when set. |
stars |
integer | Stargazer count. |
forks |
integer | Number of forks. |
watchers |
integer | Number of watchers. |
openIssues |
integer | Count of open issues and pull requests. |
language |
string | Primary programming language. |
topics |
array | List of topic tags on the repository. |
license |
string | SPDX license identifier, e.g. MIT, Apache-2.0. |
isFork |
boolean | Whether the repository is a fork. |
isArchived |
boolean | Whether the repository is archived. |
size |
integer | Repository size in kilobytes. |
defaultBranch |
string | Default branch name, e.g. main. |
createdAt |
string (ISO date) | When the repository was created. |
updatedAt |
string (ISO date) | Last metadata update timestamp. |
pushedAt |
string (ISO date) | Last push (code change) timestamp. |
Input
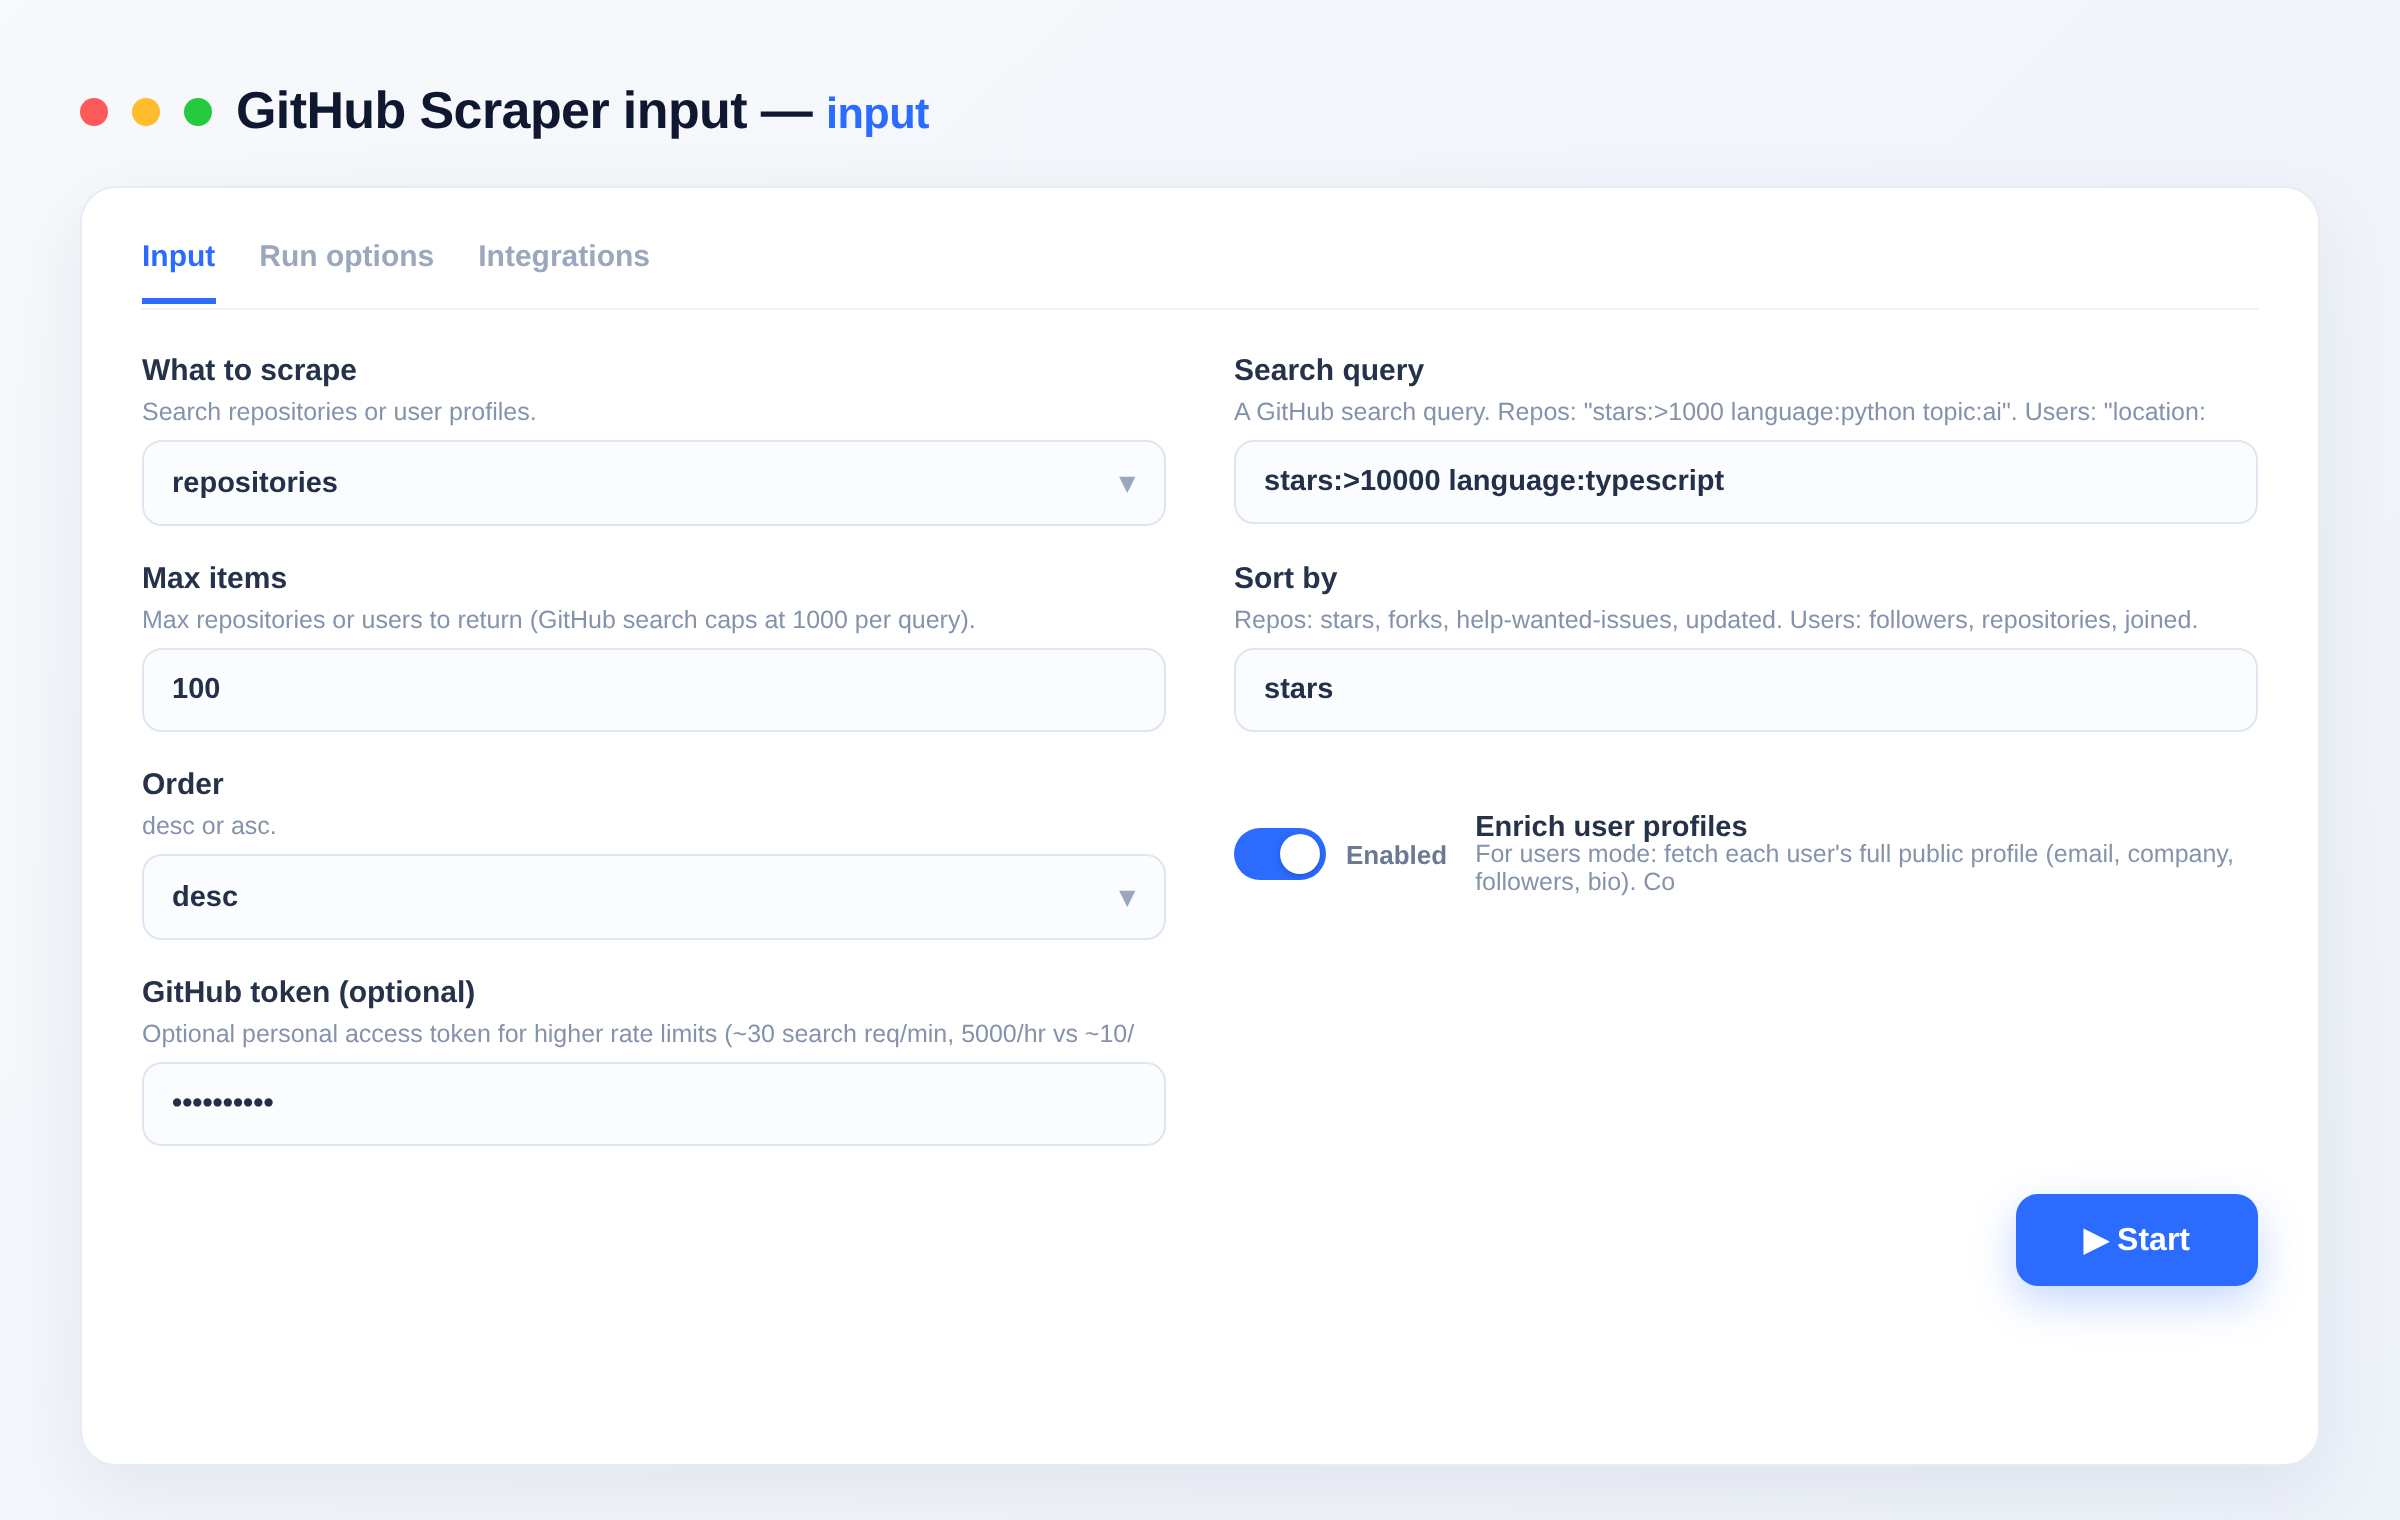
Set what to scrape (repositories or users), a GitHub search query, and how many results — then click Start. No login or setup required.
{
  "mode": "repositories",
  "query": "stars:>10000 language:typescript",
  "maxItems": 100,
  "sort": "stars",
  "order": "desc",
  "enrichUserProfiles": true,
  "githubToken": ""
}
| Field | Description |
|---|---|
mode |
Scrape repositories or users / profiles. |
query |
A GitHub search query, e.g. stars:>1000 language:python topic:ai or location:berlin language:go. |
maxItems |
Max repositories or users to return (GitHub caps search at 1000 per query). |
sort / order |
Sort field (stars, forks, followers, joined…) and direction (desc or asc). |
enrichUserProfiles |
In users mode, fetch each user's full profile (email, company, followers, bio). |
githubToken |
Optional personal access token for higher rate limits; no scopes needed for public data. |
Use cases
- Build developer lead lists from user profiles filtered by location, language and followers.
- Research the top repositories in a technology or topic for competitive analysis.
- Source open-source maintainers with public emails for outreach or recruiting.
- Track stars, forks and activity across a curated set of projects over time.
Pricing
Pay-per-event: you're billed a small amount per run and per item scraped — you only pay for what you get. See the Pricing tab for current rates.
FAQ
Do I need a GitHub token or API key? No. The actor works out of the box against the official GitHub REST API with no login. A personal access token is optional — supply one to raise the rate limit to about 5000 requests/hour; no scopes are needed for public data.
How many repositories or users can I scrape per run?
Up to 1000 per query — GitHub caps its search API at 1000 results per query. Use maxItems to set your own lower limit and refine the query to stay within that window.
Is scraping GitHub allowed? This actor uses GitHub's own public REST API and reads only publicly available data, respecting rate-limit resets and retrying on 403/429. Review GitHub's Acceptable Use Policies before large-scale or commercial reuse, especially of profile emails.
What's the output format?
Structured JSON — in repositories mode, one record per repo (stars, forks, language, topics, license, dates); in users mode, one profile per user (login, company, location, email, followers, bio). Export as JSON, CSV, Excel or via the API.
Can I filter by stars, language or location?
Yes. Use GitHub's query qualifiers directly, e.g. stars:>10000 language:typescript for repos or location:berlin followers:>500 for users, and sort by stars, forks, updated, followers or joined.
Can I connect the GitHub Scraper to Zapier, Make, Slack or Google Drive? Yes. The GitHub Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes — get a notification or kick off another process downstream.
Doing developer research, lead-gen or recruiting? Combine this with our other developer-data scrapers:
- npm Package Scraper — search and look up npm packages with metadata, dependencies and downloads.
- PyPI Package Scraper — metadata, dependencies, licenses and downloads for Python packages.
- Stack Overflow & Stack Exchange Scraper — questions by tag or search across Stack Exchange sites.
- Hacker News Scraper — stories, comments and Ask/Show HN by keyword and filters.
Notes
This actor uses the public GitHub REST API and reads only publicly available data. It is an independent tool and is not affiliated with, endorsed by, or sponsored by GitHub, Inc. or Microsoft; "GitHub" is a trademark of GitHub, Inc.
Input
| Field | Type | Description |
|---|---|---|
modeWhat to scrape | string · repositories, users | Search repositories or user profiles. Default: "repositories" |
querySearch query | string | A GitHub search query. Repos: "stars:>1000 language:python topic:ai". Users: "location:berlin language:go followers:>500". |
maxItemsMax items | integer | Max repositories or users to return (GitHub search caps at 1000 per query). Default: 100 |
sortSort by | string | Repos: stars, forks, help-wanted-issues, updated. Users: followers, repositories, joined. Empty = best match. Default: "stars" |
orderOrder | string · desc, asc | desc or asc. Default: "desc" |
enrichUserProfilesEnrich user profiles | boolean | For users mode: fetch each user's full public profile (email, company, followers, bio). Costs one extra request per user. Default: true |
githubTokenGitHub token (optional) | string | Optional personal access token for higher rate limits (~30 search req/min, 5000/hr vs ~10/min unauthenticated). No scopes needed for public data. |
proxyConfigurationProxy (optional) | object | Optional. The GitHub API works without a proxy. Default: {"useApifyProxy": false} |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~github-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "query": "stars:>10000 language:typescript"
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/github-scraper").call(run_input={
"query": "stars:>10000 language:typescript"
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/github-scraper').call({
"query": "stars:>10000 language:typescript"
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Item scraped One repository or user profile with full metadata | $0.0008 | $0.0004 |
| API request One GitHub API request (a search page or a user-profile enrichment) | $0.001 | $0.001 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Dribbble Shots Scraper
Scrape public design shots from Dribbble: title, high-res image, tags, likes, views and designer credit. Filter by category or sort, export JSON, CSV or Excel.
359 runs · 5 users · $0.003 / shot scraped
Computrabajo Scraper
Scrape Computrabajo job listings across Latin America (Mexico, Colombia, Argentina, Chile, Peru and more): title, company, location, salary, posted date and apply URL. Filter by country and keyword. No setup.
206 runs · 4 users · $0.002 / listing scraped
Kraken Market Data Scraper
Fetch Kraken spot market data in bulk: ticker stats (ask, bid, last, 24h high/low/volume/vwap), OHLC candles for any interval, order book depth (top bids/asks), and tradable pair metadata. Fast, clean and cheap.
165 runs · 4 users · $0.001 / pair scraped
Bayt Scraper
Scrape Bayt.com job listings across the Middle East (UAE, Saudi Arabia, Egypt, Qatar and more): title, company, location, posted date and apply URL. Filter by country and keyword.
134 runs · 4 users · $0.003 / job scraped
Hacker News Scraper
Scrape Hacker News stories, comments, Ask HN, Show HN, jobs and polls by keyword, points, comments and date range. Sort by relevance or newest. Title, URL, author, points, comment count, text and HN link. Fast clean HTTP via the HN Algolia API, no setup.
130 runs · 2 users · $0.004 / item scraped
RemoteOK Job Scraper
Scrape remote job listings from RemoteOK: position, company, tags, location, salary range, and full job description. One request, complete records.
126 runs · 2 users · $0.001 / job scrapedSend the site and the fields. We build it and you get it first.