USASpending.gov Scraper
hipersoft/usaspending-scraper
Search US federal spending: contracts, grants, loans and direct payments by keyword, agency, date and amount. Get recipient, amount, agency, description, dates and location. For gov-contractor and grant intelligence. No setup.
Total users
1Monthly users
1Total runs
116Per award scraped
$0.002Last rebuilt
Oct 28, 2026Overview
Search the US government's official spending database and get federal awards back as clean, structured JSON. Query contracts, grants, loans, direct payments or other financial assistance by keyword, awarding agency, date range and minimum amount — then pull recipient, amount, agency, description, dates and place of performance for each award. No account, no API key. Built for government-contractor intelligence, grant research and competitive analysis.
Features
- 🏛️ Every award type — switch
awardTypebetweencontracts,grants,loans,direct_paymentsandother. - 🔍 Keyword search — match recipient names and award descriptions with
keywordslikesoftwareorcybersecurity. - 🏢 Agency filtering — narrow to top-tier awarding agencies such as
Department of DefenseorNational Aeronautics and Space Administration. - 📅 Date range — bound results by award action date with
fromDate/toDate(defaults to today). - 💵 Minimum amount — set
minAmountto focus on material awards only. - 📊 Sorted by value — awards come back largest-first, so a
maxResultscap keeps the biggest ones. - 🔗 Direct links — each record includes a
urlback to the award page on USASpending.gov.
What you get
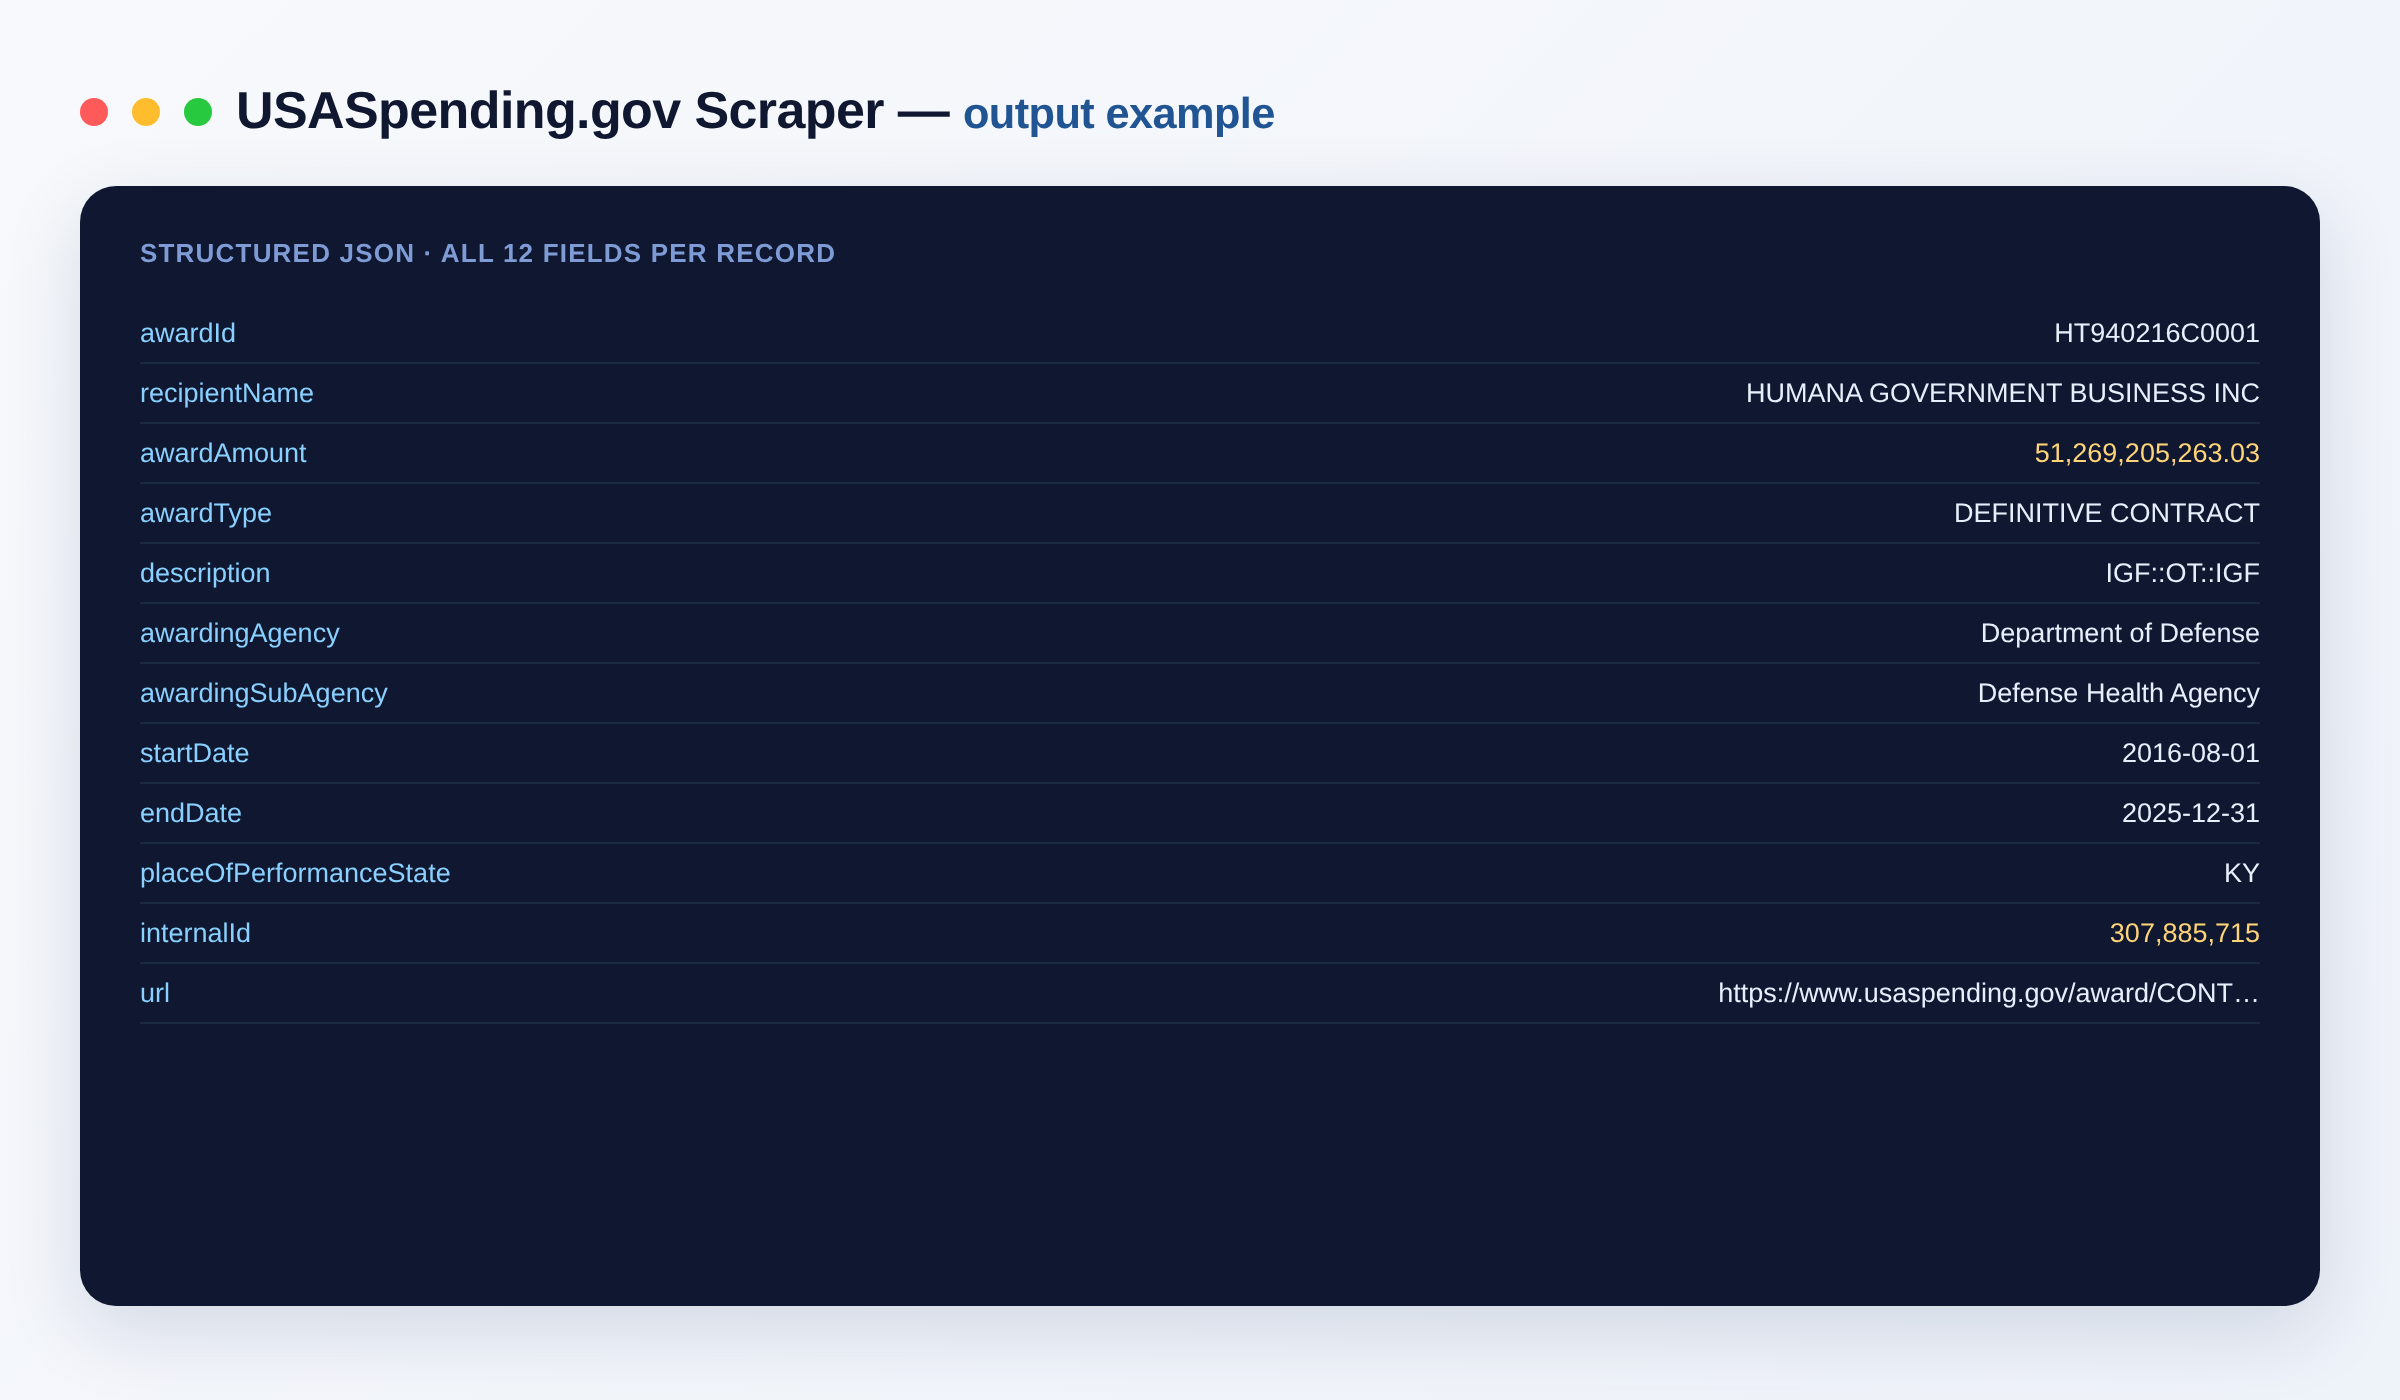
One flat JSON record per award:
{
  "awardId": "W52P1J-23-C-0001",
  "recipientName": "EXAMPLE DEFENSE SYSTEMS INC.",
  "awardAmount": 48250000,
  "awardType": "DEFINITIVE CONTRACT",
  "description": "CYBERSECURITY SOFTWARE AND SUPPORT SERVICES",
  "awardingAgency": "Department of Defense",
  "awardingSubAgency": "Department of the Army",
  "startDate": "2023-03-15",
  "endDate": "2026-03-14",
  "placeOfPerformanceState": "VA",
  "internalId": 123456789,
  "url": "https://www.usaspending.gov/award/CONT_AWD_W52P1J23C0001"
}
Output schema
| Field | Type | Description |
|---|---|---|
awardId |
string | The federal award identifier (PIID or FAIN). |
recipientName |
string | Name of the award recipient. |
awardAmount |
number | Total award amount in USD. |
awardType |
string | Type of award (e.g. DEFINITIVE CONTRACT, grant). |
description |
string | Description of the award. |
awardingAgency |
string | Top-tier awarding agency. |
awardingSubAgency |
string | Awarding sub-agency. |
startDate |
string | Award period start date. |
endDate |
string | Award period end date. |
placeOfPerformanceState |
string | US state where the work is performed. |
internalId |
integer | USASpending internal record ID. |
url |
string (URL) | Link to the award page on USASpending.gov. |
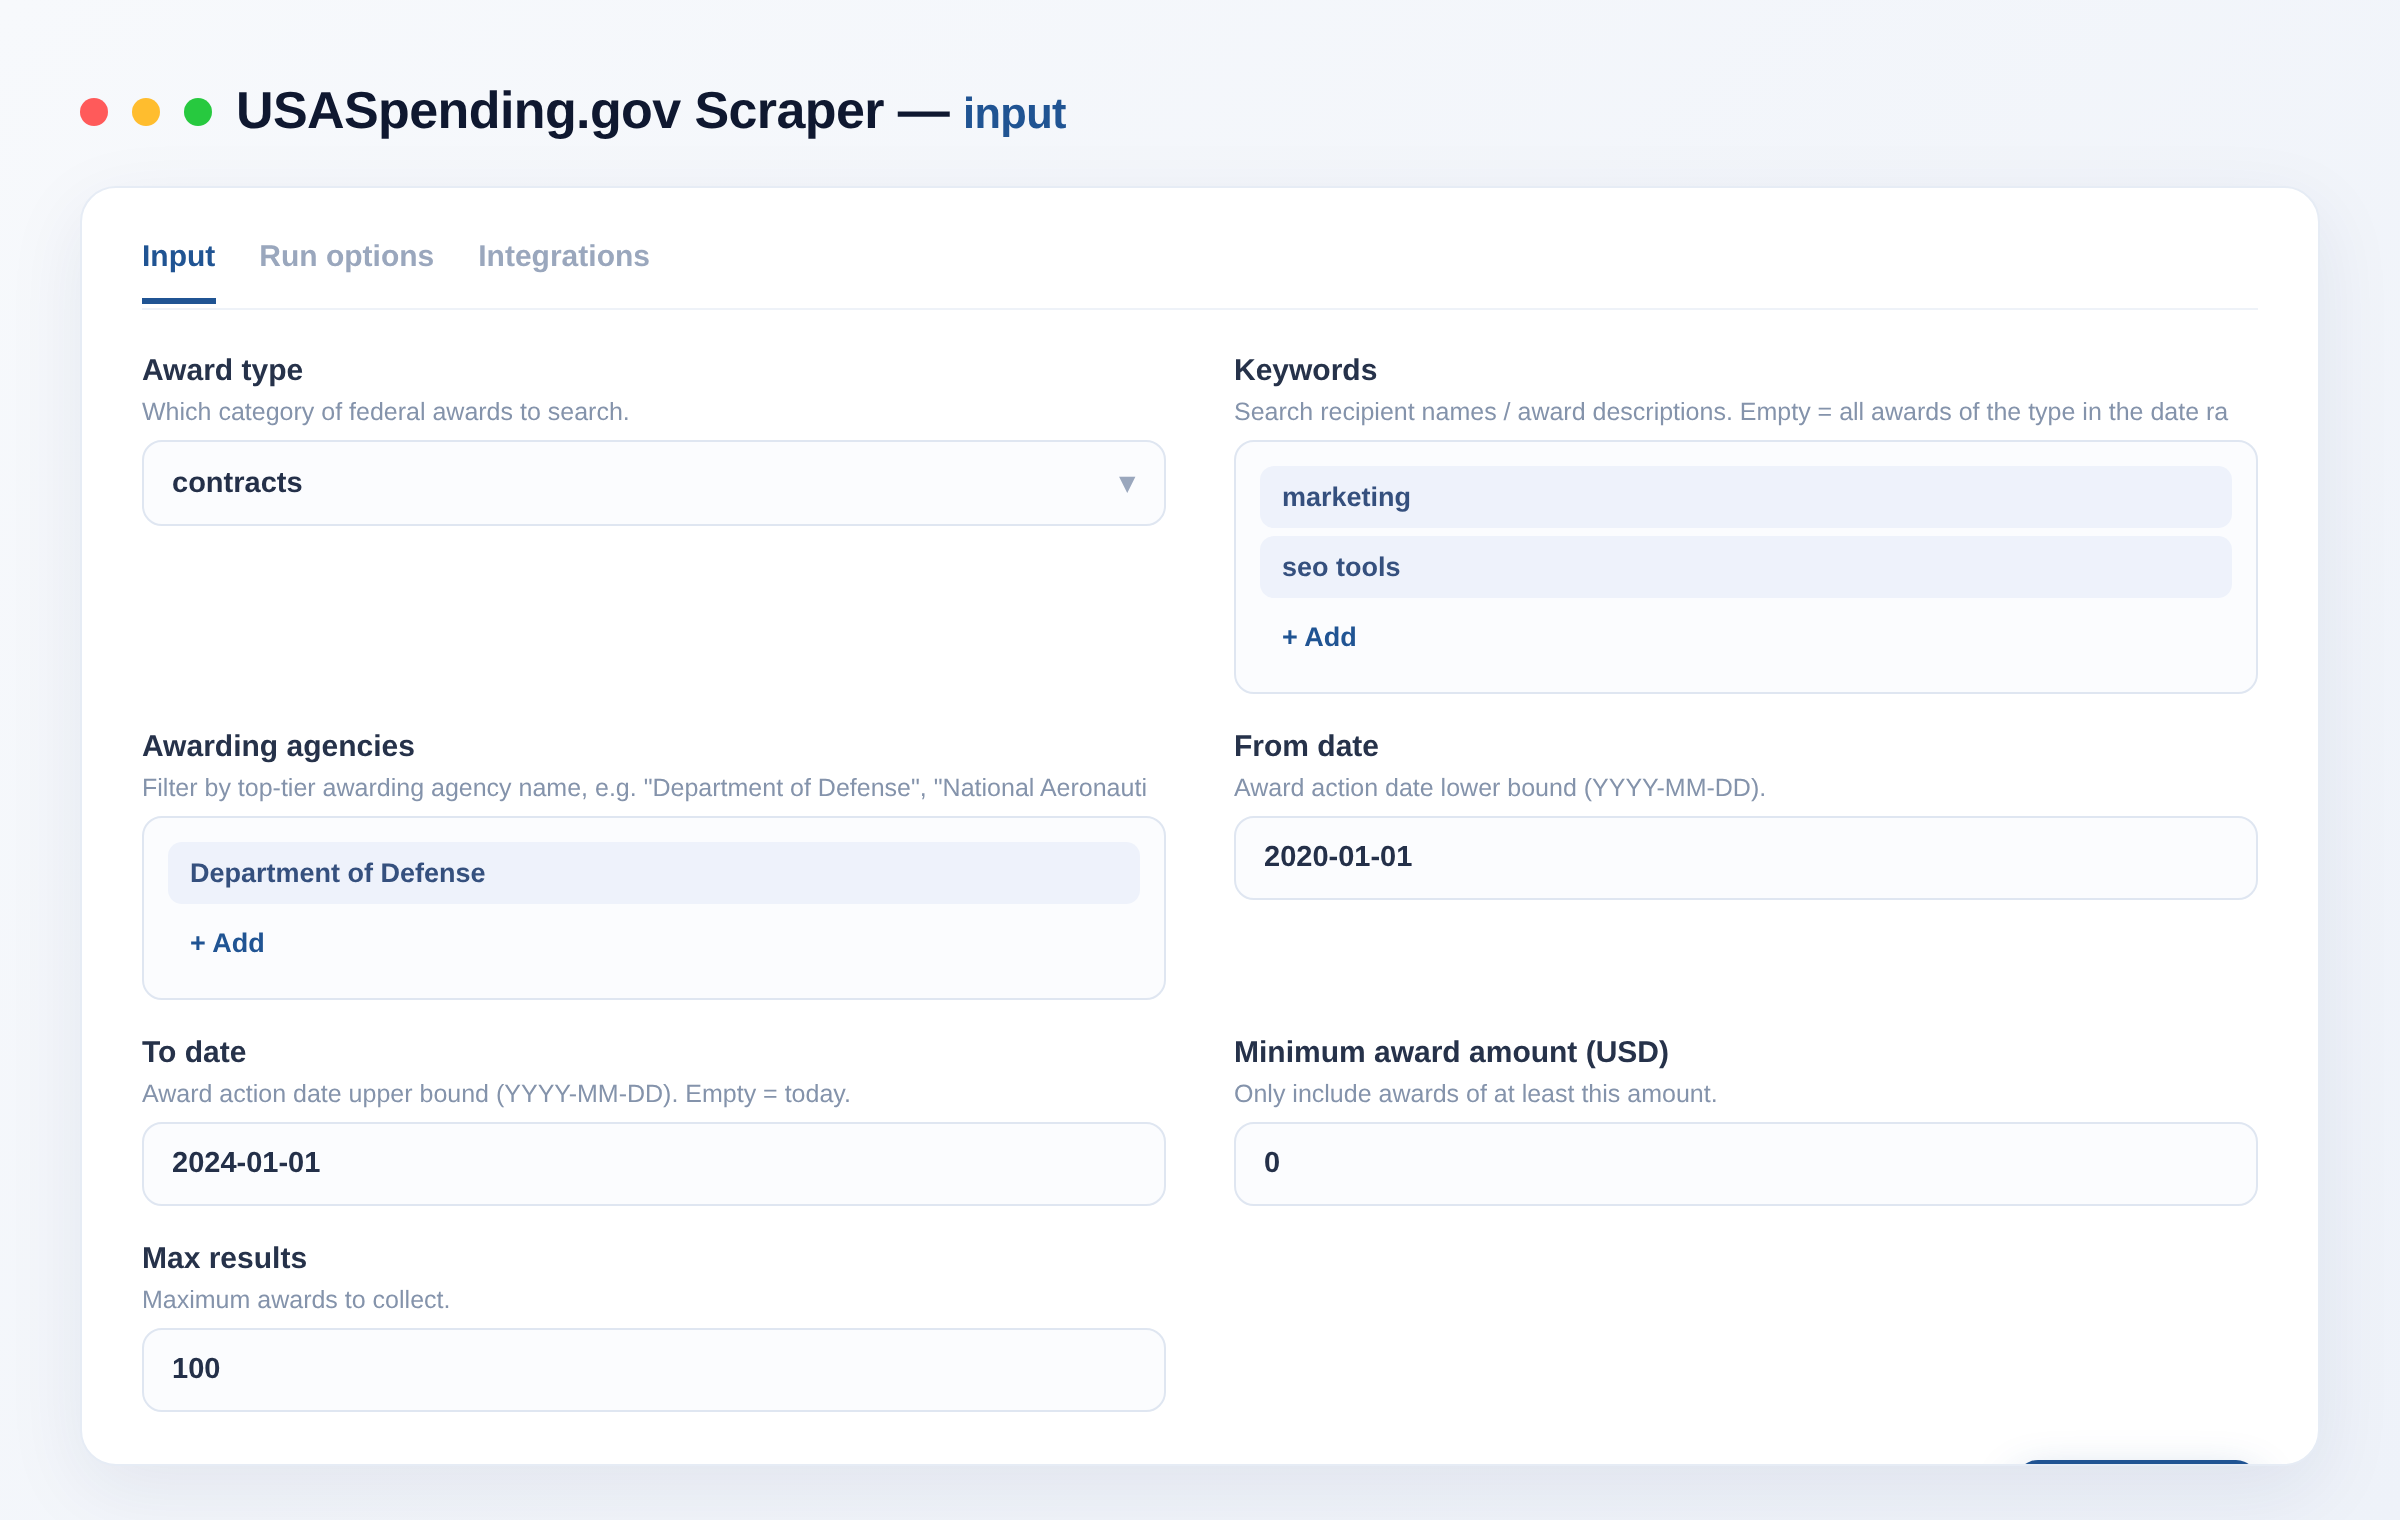
Input
{
  "awardType": "contracts",
  "keywords": ["cybersecurity"],
  "agencies": ["Department of Defense"],
  "fromDate": "2022-01-01",
  "toDate": "",
  "minAmount": 1000000,
  "maxResults": 500
}
| Field | Description |
|---|---|
awardType |
Category of federal awards: contracts, grants, loans, direct_payments or other. |
keywords |
Search recipient names / award descriptions. Empty = all awards of the type in range. |
agencies |
Filter by top-tier awarding agency name. |
fromDate |
Award action date lower bound (YYYY-MM-DD). |
toDate |
Award action date upper bound (YYYY-MM-DD). Empty = today. |
minAmount |
Only include awards of at least this amount (USD). |
maxResults |
Maximum awards to collect (1–10000). |
Use cases
- Track federal contracts in your sector to find prime and subcontract opportunities.
- Monitor grants and financial assistance for a target agency or program.
- Build competitor intelligence on which recipients win large government awards.
- Feed award data into market-sizing, forecasting or lobbying research.
Pricing
Pay-per-event: you're billed a small amount per run and per item scraped — you only pay for what you get. See the Pricing tab for current rates.
FAQ
Do I need an API key or account? No. The Actor reads the official public USASpending.gov data, which is free and open — no login, no key.
How many awards can I get per run?
Set maxResults anywhere from 1 to 10,000. Awards are returned largest-first by amount, so a cap always keeps the biggest, most material awards.
How fresh is the data? It reflects USASpending.gov's official database at run time. Federal spending records are updated by the government on their own schedule, so recency depends on when agencies report each award.
Is the data official? Yes — it comes directly from USASpending.gov, the US government's official federal spending source. This Actor is an independent tool and is not affiliated with or endorsed by USASpending.gov or the US federal government.
What's the output format?
Flat JSON, one record per award, with recipient, amount, agency, description, dates, place of performance and a direct url to the award page. Export as JSON, CSV or Excel.
Can I integrate this with other tools? The USASpending.gov Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
More government and regulatory data scrapers from the same publisher:
- SEC EDGAR Filings Scraper — 10-K, 10-Q and 8-K filings by ticker or CIK.
- openFDA Scraper — FDA drug, device and food recalls, labels and adverse events.
- Brazil CNPJ Scraper — official Brazilian company records from Receita Federal.
- ClinicalTrials Scraper — clinical study records from ClinicalTrials.gov.
Notes
This Actor reads the official public USASpending.gov data. It is an independent tool and is not affiliated with or endorsed by USASpending.gov or the US federal government; all trademarks belong to their respective owners.
Input
| Field | Type | Description |
|---|---|---|
awardTypeAward type | string · contracts, grants, loans, direct_payments, other | Which category of federal awards to search. Default: "contracts" |
keywordsKeywords | array | Search recipient names / award descriptions. Empty = all awards of the type in the date range. |
agenciesAwarding agencies | array | Filter by top-tier awarding agency name, e.g. "Department of Defense", "National Aeronautics and Space Administration". |
fromDateFrom date | string | Award action date lower bound (YYYY-MM-DD). Default: "2020-01-01" |
toDateTo date | string | Award action date upper bound (YYYY-MM-DD). Empty = today. |
minAmountMinimum award amount (USD) | integer | Only include awards of at least this amount. Default: 0 |
maxResultsMax results | integer | Maximum awards to collect. Default: 100 |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~usaspending-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "keywords": [
    "software",
    "cybersecurity"
  ],
  "agencies": [
    "Department of Defense"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/usaspending-scraper").call(run_input={
"keywords": [
"software",
"cybersecurity"
],
"agencies": [
"Department of Defense"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/usaspending-scraper').call({
"keywords": [
"software",
"cybersecurity"
],
"agencies": [
"Department of Defense"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Award scraped One federal award with recipient, amount, type, agency, description, dates and location | $0.002 | $0.001 |
| API request One USASpending results page (up to 100 awards) | $0.0005 | $0.0005 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Europe PMC Scraper
Bulk-scrape life-science and biomedical literature from Europe PMC (40M+ records: PubMed, PMC, preprints, patents): title, abstract, authors, journal, year, DOI, PMID/PMCID, citation count, MeSH terms, open-access flag and full-text/PDF links. Thousands per run. No setup.
325 runs · 5 users · $0.001 / article scraped
arXiv Papers Scraper
Search and extract arXiv papers: title, abstract, authors, categories, published/updated dates, DOI, journal reference, and direct PDF links. Filter by category and sort by newest, recently updated or relevance. Fetch by arXiv ID too. For research, lit reviews and AI/ML monitoring. No setup.
140 runs · 2 users · $0.0025 / paper scraped
Letterboxd Scraper
Scrape Letterboxd films with ratings, rating counts, genres, director, cast, runtime and synopsis. Feed it film pages, a user's films/watchlist/diary, any list URL, or browse pages. For film data, recommendations and research.
139 runs · 7 users · $0.0042 / film scraped
OpenLibrary Book Scraper
Search millions of books on OpenLibrary by keyword, author, subject or ISBN and get title, authors, publisher, year, subjects, ISBNs, edition count, ratings, page count and cover. Clean, no setup.
124 runs · 5 users · $0.002 / book scraped
Semantic Scholar Scraper
Bulk-scrape academic papers from Semantic Scholar's 200M+ corpus: title, abstract, AI TLDR summary, authors, venue, year, citation & influential-citation counts, fields of study, DOI/PubMed/arXiv IDs and open-access PDF links. Filter by year, field and citations. Thousands per run. No setup.
123 runs · 7 users · $0.001 / paper scraped
Wikipedia Scraper
Search Wikipedia or look up exact articles and get the full plain-text content, summary, categories, image, Wikidata ID and monthly pageview trends. Any language. Great for research, RAG and AI datasets. No setup.
121 runs · 1 users · $0.001 / article scrapedSend the site and the fields. We build it and you get it first.