Scrapers / Developer & File Tools
Sitemap URL Extractor & Monitor
hipersoft/sitemap-extractor
Extract every URL from any website's sitemaps: loc, lastmod, changefreq and priority. Follows sitemap indexes recursively, discovers sitemaps from robots.txt, handles gzipped sitemaps, and can return only URLs changed since a date. No setup.
Total users
1Monthly users
1Total runs
90Per url extracted
$0.0002Last rebuilt
Oct 28, 2026Overview
Extract every URL from any website's sitemaps — with lastmod, changefreq and priority — into clean JSON, CSV or Excel. Follows sitemap indexes recursively, discovers sitemaps from robots.txt, handles gzipped sitemaps, and can return only URLs changed since a date so you can monitor a site for new and updated pages. No key, no login. Fast and reliable.
Great for site audits, crawl seeding, SEO monitoring, content-change alerts and migrations.
What does Sitemap URL Extractor do?
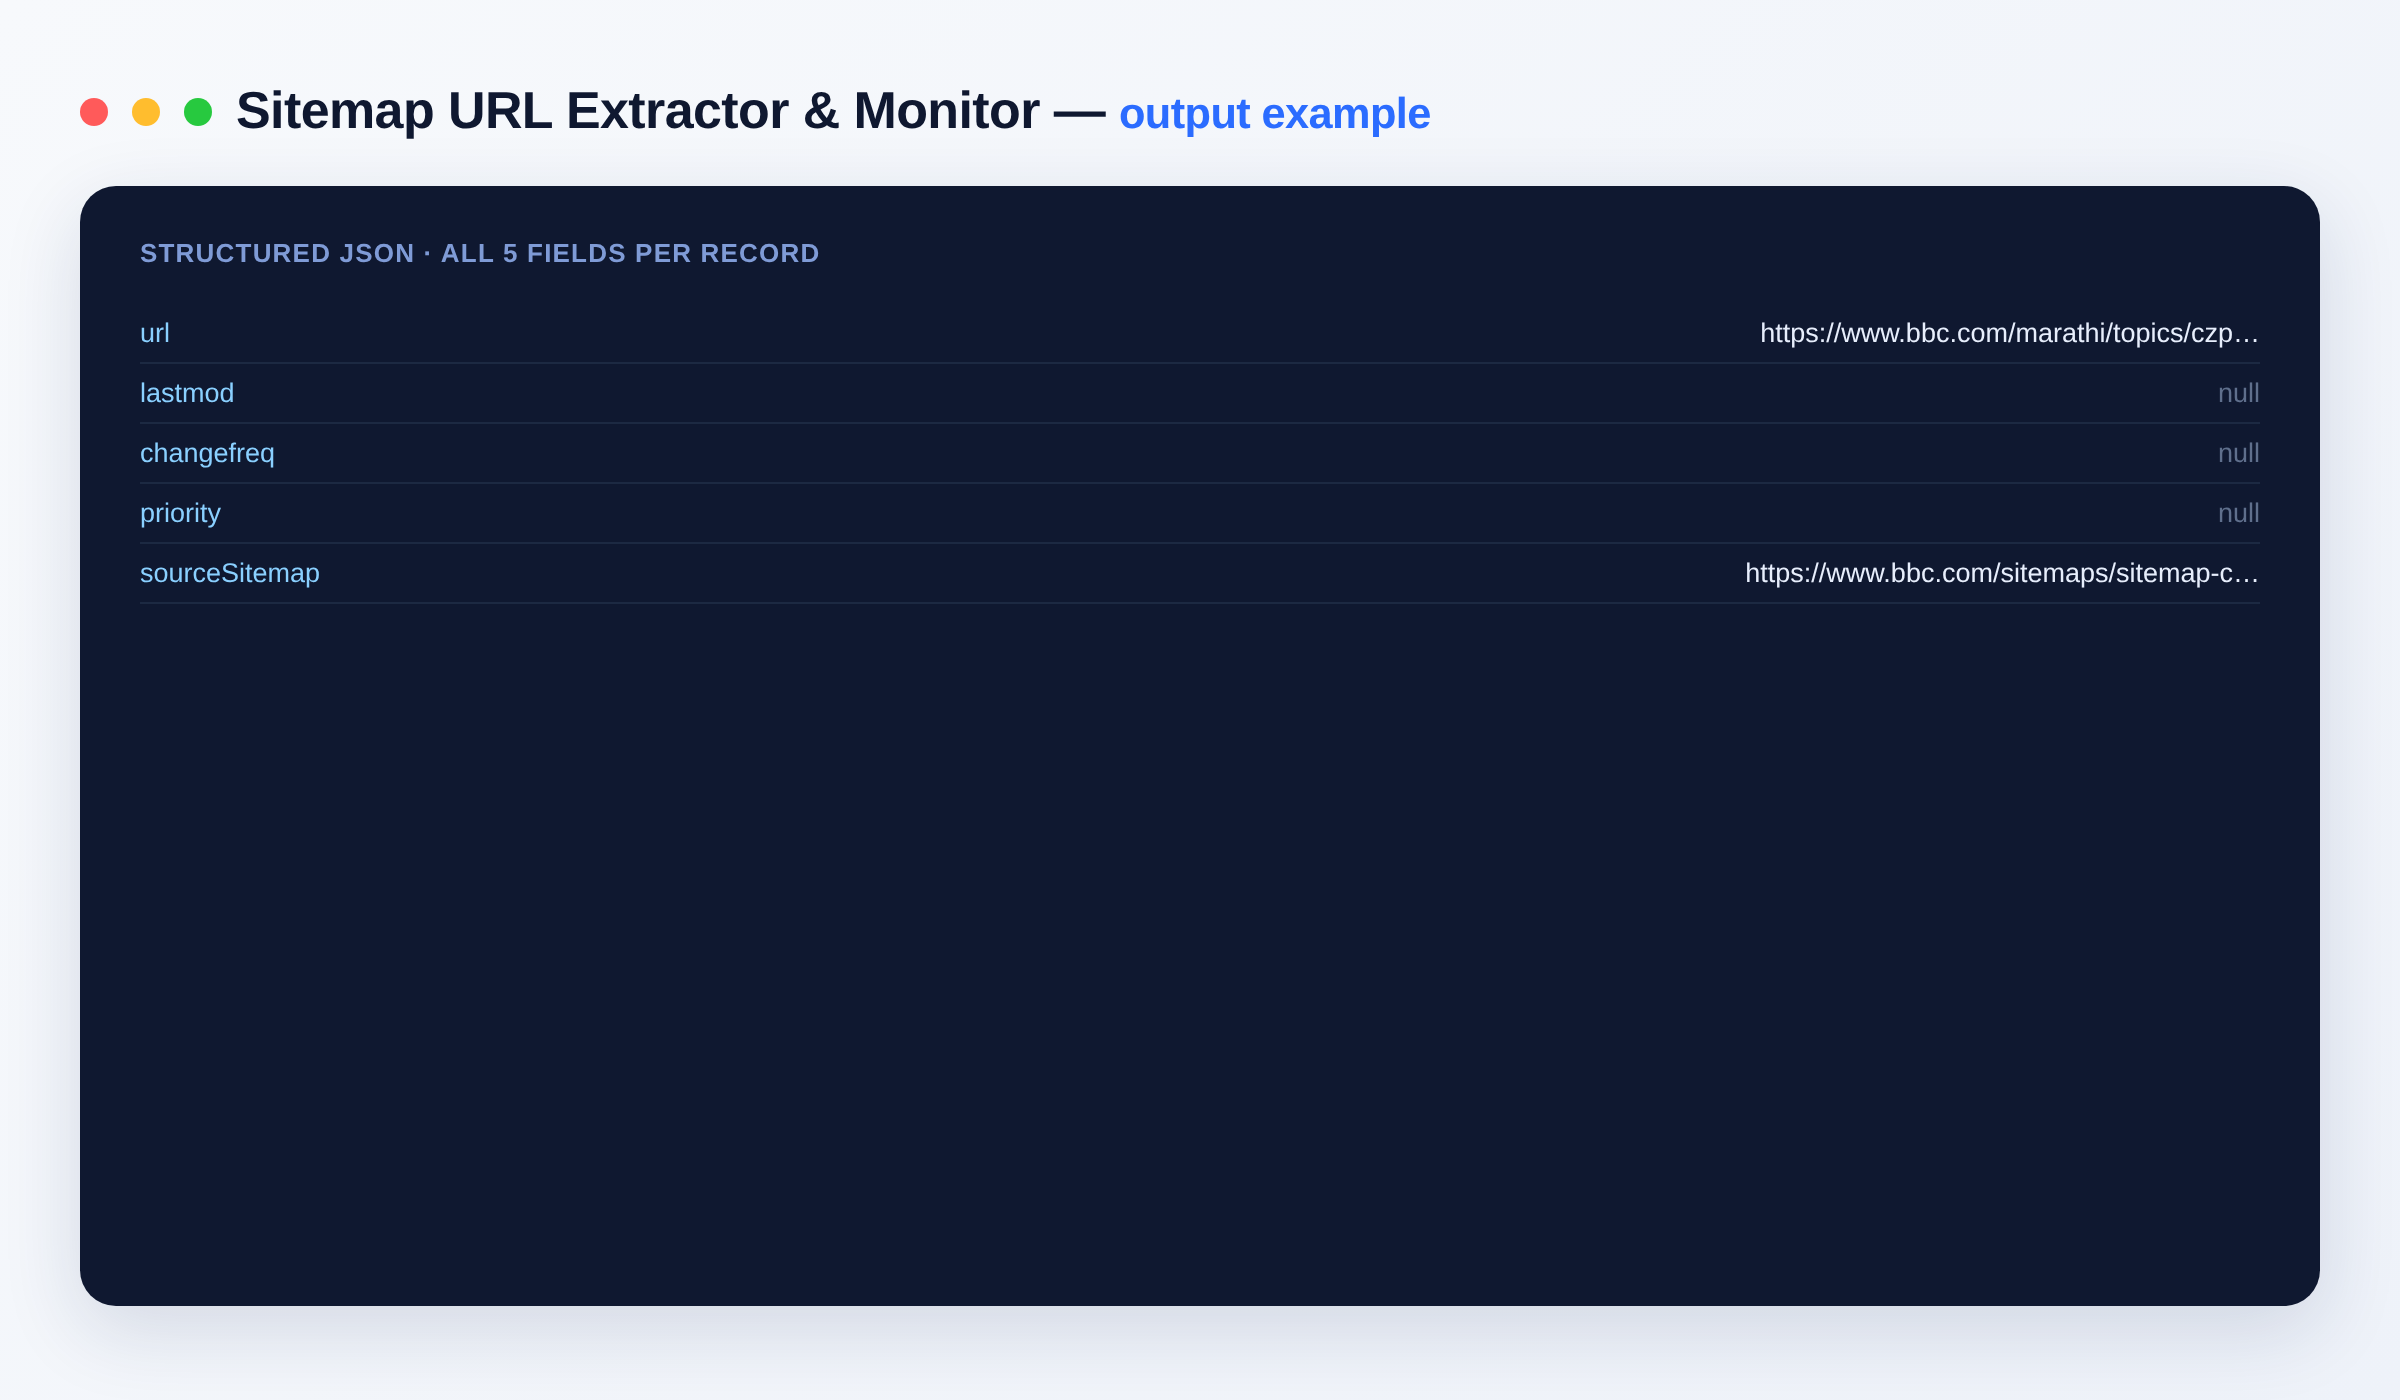
It reads a site's sitemaps and returns one clean record per URL — the page location plus its lastmod, changefreq, priority and the source sitemap it came from. It follows sitemap-index files recursively, discovers sitemaps from robots.txt, reads gzipped sitemaps, and can filter to only URLs changed since a date.
What you get
- 🔗 All URLs — every
<loc>withlastmod,changefreq,priorityand its source sitemap - 🌲 Recursive — automatically follows sitemap-index → child sitemaps
- 🤖 Auto-discovery — finds sitemaps from
robots.txt; falls back to/sitemap.xml - 🗜️ Gzip — reads
.xml.gzsitemaps - 🕒 Monitor mode —
changedSincereturns only URLs modified on/after a date - 📥 Scales — walk indexes with millions of URLs, capped by your limits
Output schema
| Field | Type | Description |
|---|---|---|
url |
string (URL) | The page URL from the sitemap <loc>. |
lastmod |
string | Last-modified date reported for the URL. |
changefreq |
string | Suggested crawl frequency (e.g. weekly, daily). |
priority |
string | Relative priority of the URL (0.0–1.0). |
sourceSitemap |
string (URL) | The sitemap file the URL was found in. |
Use cases
- Site audits — get a full inventory of a site's indexable URLs.
- Crawl seeding — feed the URL list into a crawler or scraper.
- SEO monitoring — track which pages change and how often.
- Content-change alerts — use
changedSinceto catch new or updated pages. - Migrations — compare URL sets before and after a site move.
- Coverage checks — verify every important page is in the sitemap.
How to extract sitemap URLs
- Add the Sitemap URL Extractor & Monitor to your Apify account.
- Add a site URL (sitemaps discovered automatically) or a direct sitemap URL to
startUrls. - Set
maxUrls,maxSitemapsand, optionally,changedSince. - Click Run.
- Export the results as JSON, CSV or Excel, or pull them via the Apify API.
Input
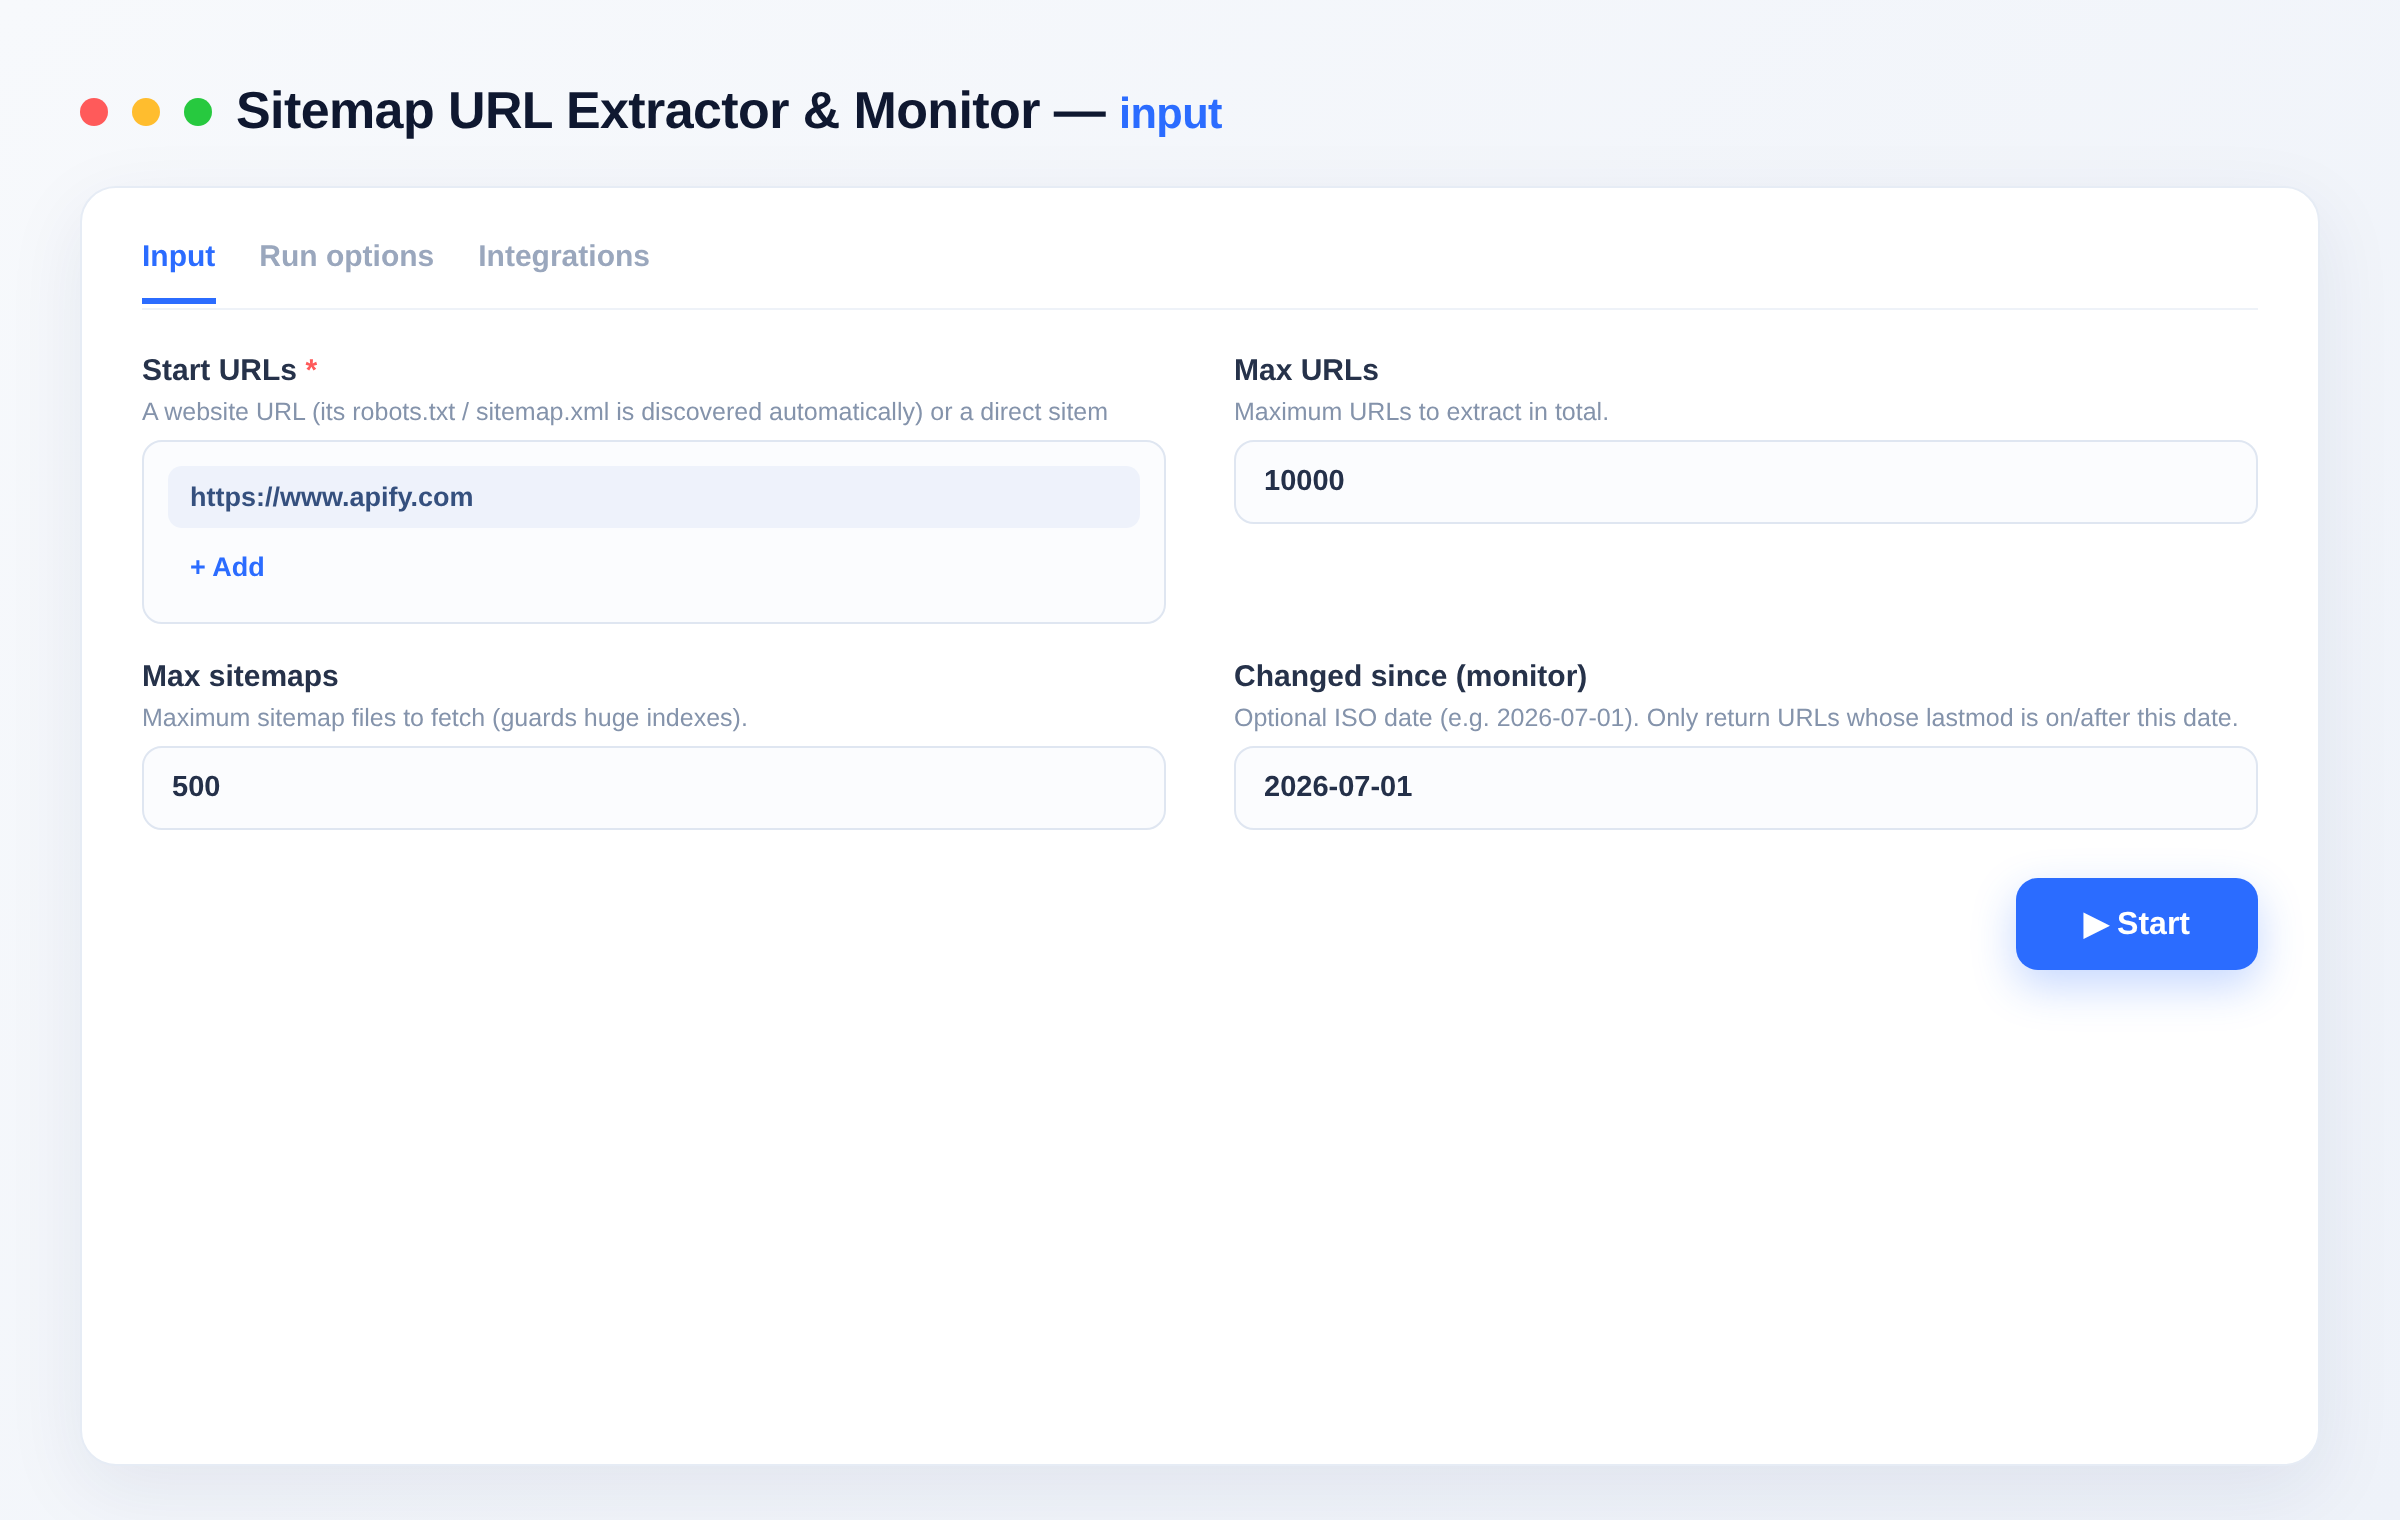
{
  "startUrls": ["https://www.apify.com"],
  "maxUrls": 20000,
  "changedSince": "2026-07-01"
}
Pass a site URL (sitemaps discovered automatically) or a direct sitemap URL (.xml or .xml.gz).
| Field | Description |
|---|---|
startUrls |
Site URLs or direct sitemap URLs. |
maxUrls |
Max URLs to extract. |
maxSitemaps |
Max sitemap files to fetch. |
changedSince |
Only return URLs with lastmod on/after this date. |
Output
{
  "url": "https://www.apify.com/pricing",
  "lastmod": "2026-07-18",
  "changefreq": "weekly",
  "priority": 0.8,
  "sourceSitemap": "https://www.apify.com/sitemap.xml"
}
Need more site data?
- Website Content Crawler Pro — turn pages into clean text
- Domain Inspector — DNS & domain intelligence
- URL Checker — status codes & redirects
FAQ
Do I need to know the sitemap URL?
No — pass the site's homepage and the Actor finds sitemaps via robots.txt and /sitemap.xml.
How many URLs can I extract?
As many as the site publishes; set maxUrls and maxSitemaps to cap the run.
Does it follow sitemap index files?
Yes, recursively, up to your maxSitemaps limit.
Can I monitor a site for changes?
Yes — set changedSince to only get URLs modified since that date.
What export formats are supported? JSON, CSV, Excel and XML, plus the Apify API.
Can I integrate it with other tools? The Sitemap URL Extractor & Monitor can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
How does billing work? You pay only per URL extracted — cheap per item, cheapest in its class.
Notes
Original clean-room implementation. Reads public sitemaps and robots.txt only. You are responsible for how you use the data.
Input
| Field | Type | Description |
|---|---|---|
startUrls requiredStart URLs | array | A website URL (its robots.txt / sitemap.xml is discovered automatically) or a direct sitemap .xml / .xml.gz URL. |
maxUrlsMax URLs | integer | Maximum URLs to extract in total. Default: 10000 |
maxSitemapsMax sitemaps | integer | Maximum sitemap files to fetch (guards huge indexes). Default: 500 |
changedSinceChanged since (monitor) | string | Optional ISO date (e.g. 2026-07-01). Only return URLs whose lastmod is on/after this date. |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~sitemap-extractor/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "startUrls": [
    "https://www.apify.com"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/sitemap-extractor").call(run_input={
"startUrls": [
"https://www.apify.com"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/sitemap-extractor').call({
"startUrls": [
"https://www.apify.com"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| URL extracted One URL extracted from a sitemap. | $0.0002 | $0.0002 |
| Sitemap fetched One sitemap file fetched and parsed. | $0.0005 | $0.0005 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Bulk Image Downloader
Download thousands of images from a list of URLs and store each in the key-value store with a public link. Returns content type, size, dimensions and SHA-256 per image. Bulk-ready. Great for datasets, backups and media pipelines.
8,102 runs · 103 users · $0.056 / url processed
Text to Speech
Convert any text to natural-sounding speech as an MP3 download. 300+ premium neural voices across 70+ languages, adjustable rate, pitch and volume. Great for voiceovers, videos, accessibility and audio content. No setup.
278 runs · 22 users · $0.01 / audio generated
Google Maps Email Extractor
Search Google Maps for businesses, then crawl each business website to extract emails, social profiles and extra phone numbers. Turns any Maps search into a ready lead list. No setup.
159 runs · 8 users · $0.006 / business lead scraped
Website Screenshot
Capture full-page or viewport screenshots of any URL as PNG or JPEG, at any device size. For monitoring, previews, thumbnails and automation workflows.
156 runs · 3 users · $0.004 / screenshot captured
Bulk URL Status Checker
Check thousands of URLs over plain HTTP: status codes, broken links (404/410/5xx), full redirect chains, response time, content type, page title and SSL certificate expiry.
154 runs · 13 users · $0.002 / url checked
Google Search Scraper
Scrape Google Search results (organic listings) for any query: title, URL, displayed URL, snippet and position. Multi-query, per-country/language, pagination. Uses Google SERP proxy — reliable, no captcha, no setup.
121 runs · 8 users · $0.001 / result scrapedSend the site and the fields. We build it and you get it first.