Website Content Crawler Pro
hipersoft/web-content-crawler-pro
Crawl any website into clean Markdown or text for LLMs, RAG and AI. HTTP + JS-browser modes, main-content (readability) extraction, sitemaps, URL glob filters, cookie-banner removal and CSS selectors. No setup.
Total users
15Monthly users
6Total runs
178Per page crawled
$0.004Last rebuilt
Oct 26, 2026Overview
Turn any website into clean, LLM-ready Markdown (or text) in one run. Built for feeding documentation, blogs and knowledge bases into RAG pipelines, vector databases and AI agents. Crawls with a fast HTTP engine or a full JavaScript browser, extracts just the main content (no nav, ads or cookie banners), and follows internal links with precise glob and sitemap control. No account, no API key.
Features
- 📝 Markdown output — clean, structured Markdown per page, ideal for LLMs, RAG and vector DBs (plus plain text and optional HTML)
- 🌐 HTTP or Browser mode — fast HTTP crawling for static sites, or full Chromium rendering for JavaScript/SPA sites
- 🧹 Main-content extraction — Readability strips navigation, ads, footers and cookie banners, keeping the real article
- 🗺️ Sitemap + glob crawling — seed from
sitemap.xml, and include/exclude URLs with glob patterns - 🔗 Smart link following — configurable depth, same-domain-only, and total page cap
- 🎯 CSS control — keep-only or remove specific elements; wait for selectors and dynamic content in browser mode
- ⚡ Fast & parallel — tunable concurrency, retries and proxy support
What you get
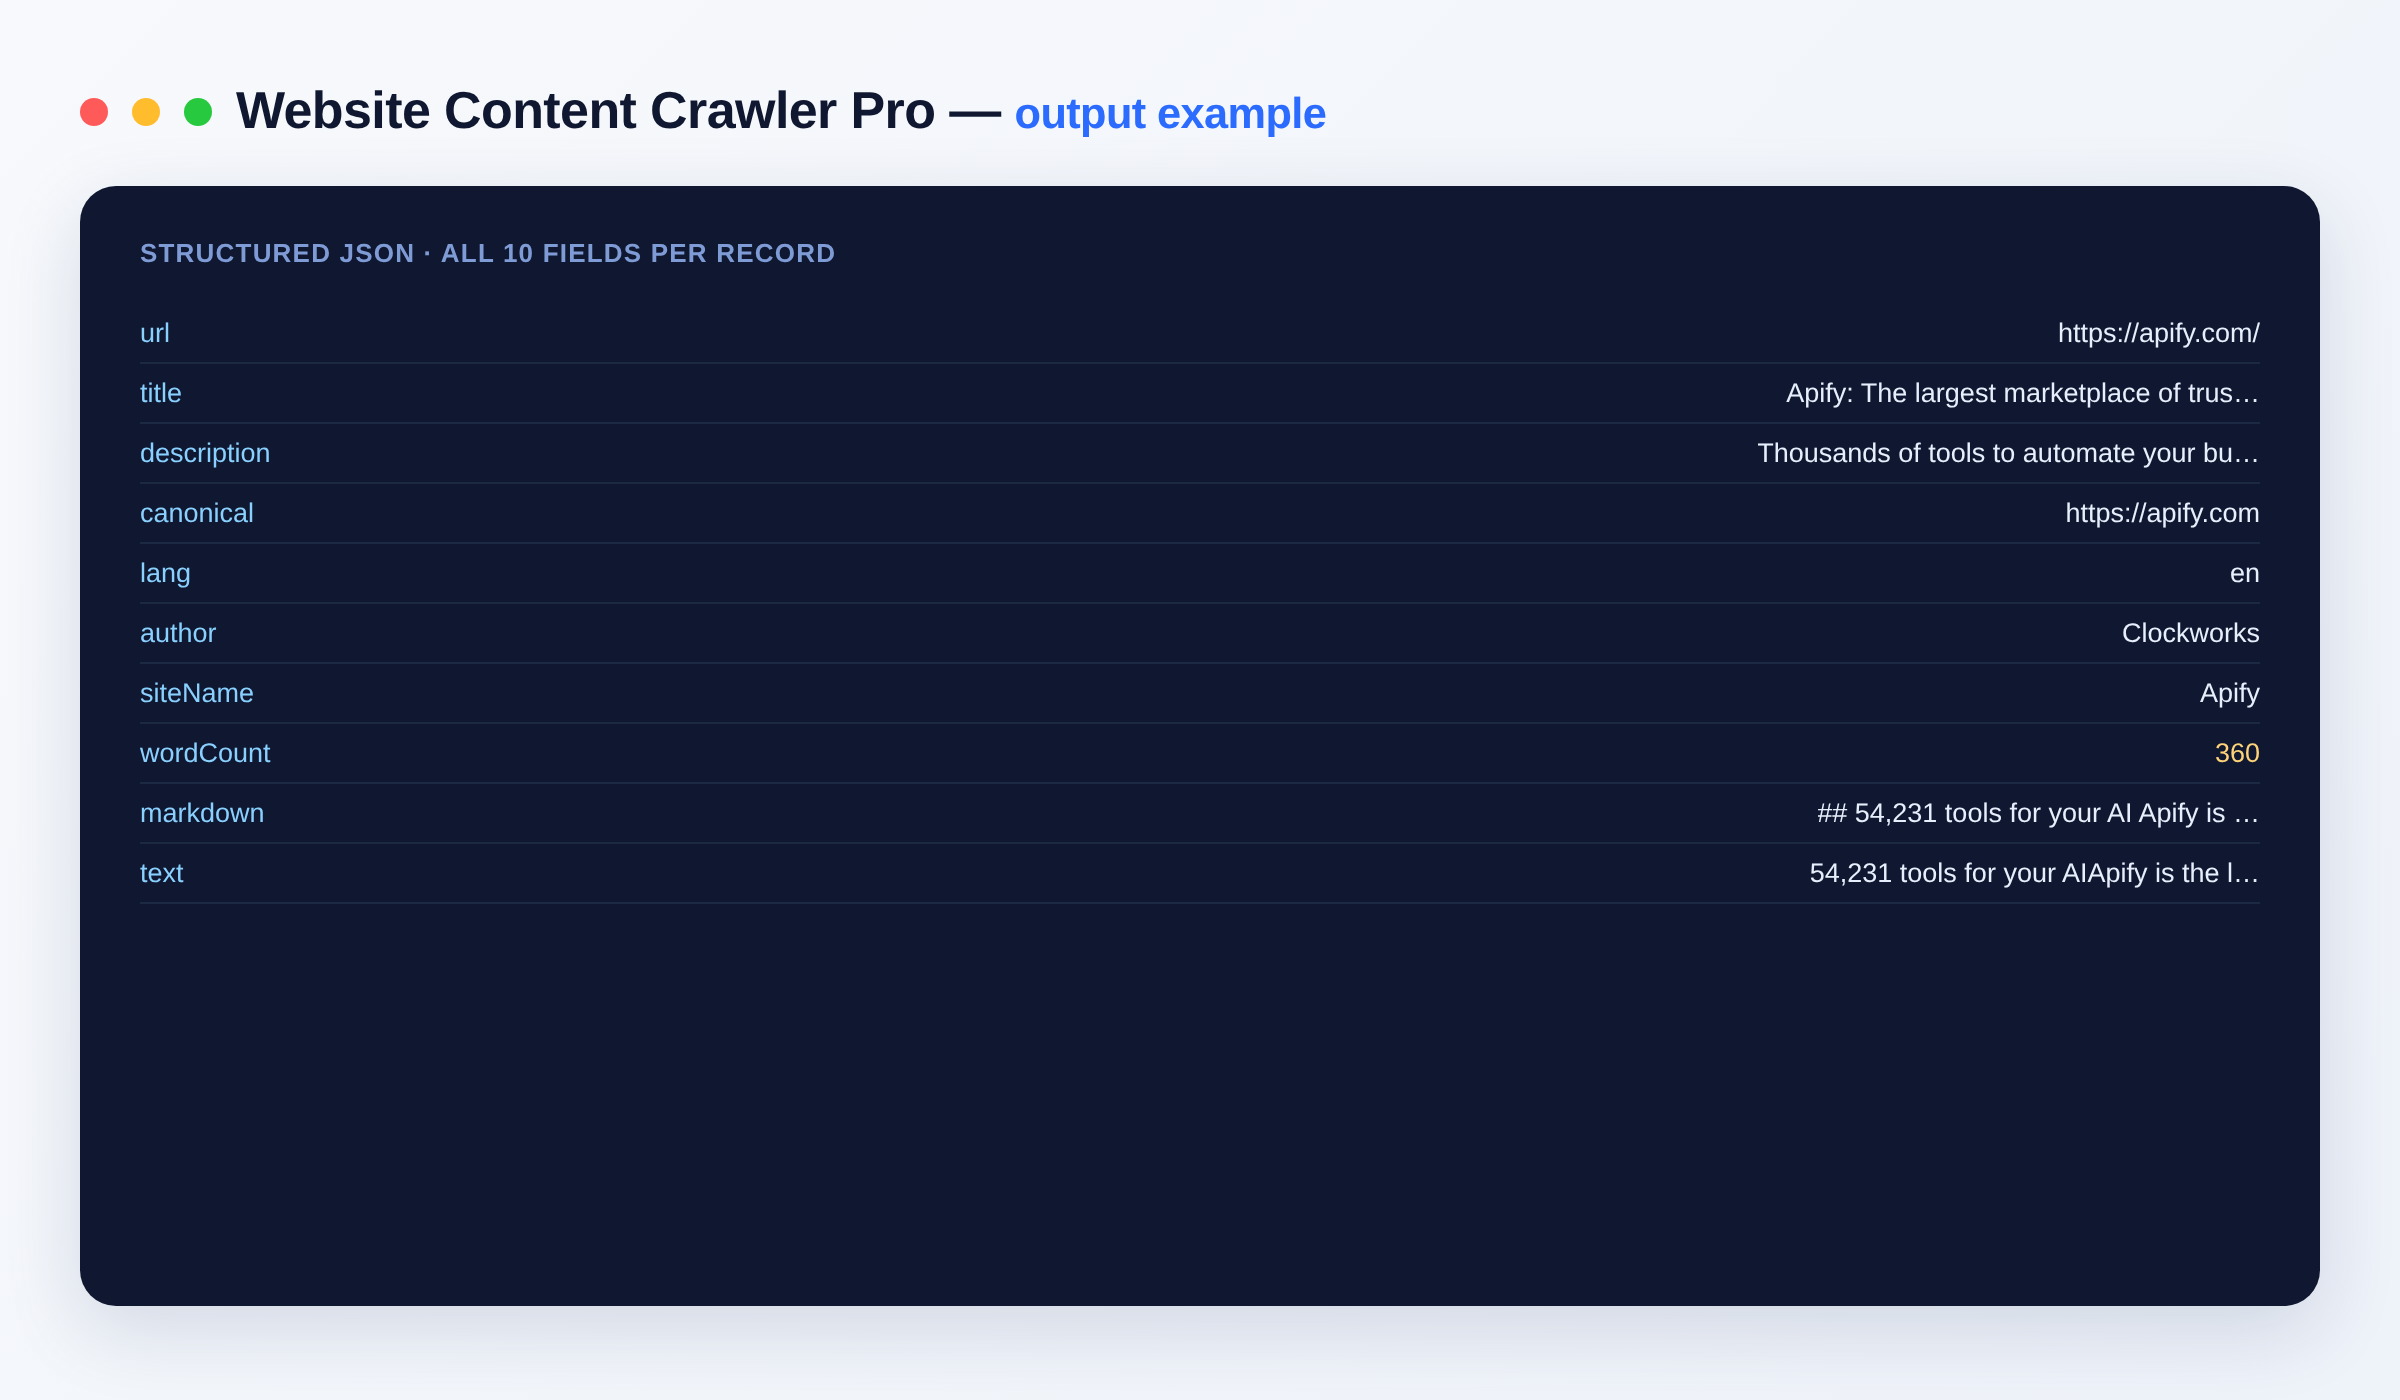
One record per page:
{
  "url": "https://docs.example.com/guide",
  "title": "Getting Started",
  "description": "A short guide to …",
  "author": null,
  "siteName": "Example Docs",
  "lang": "en",
  "wordCount": 812,
  "markdown": "# Getting Started\n\nThis guide walks you through …",
  "text": "Getting Started This guide walks you through …"
}
Output schema
| Field | Type | Description |
|---|---|---|
url |
string (URL) | Page URL that was crawled. |
title |
string | Page title. |
description |
string | Meta description of the page. |
canonical |
string (URL) | Canonical URL declared by the page. |
lang |
string | Detected page language code (e.g. en). |
author |
string | Article author, if the page declares one. |
siteName |
string | Name of the site the page belongs to. |
wordCount |
integer | Number of words in the extracted content. |
markdown |
string | Main page content as clean Markdown. |
text |
string | Main page content as plain text. |
Input
{
  "urls": ["https://docs.apify.com/academy"],
  "crawlerType": "http",
  "crawl": true,
  "maxCrawlPages": 200,
  "includeUrlGlobs": ["https://docs.apify.com/academy/**"],
  "saveMarkdown": true
}
| Field | Description |
|---|---|
urls |
Start URLs to crawl. |
crawlerType |
http (fast) or browser (JS rendering). |
crawl |
Follow internal links from the start URLs. |
maxCrawlPages / maxCrawlDepth |
Total page cap and link-hop depth. |
includeUrlGlobs / excludeUrlGlobs |
Glob filters for which URLs to crawl. |
useSitemaps |
Seed from each site's sitemap.xml. |
saveMarkdown / saveText / saveHtml |
Output formats. |
htmlTransformer |
readability (main content) or none (full body). |
Use cases
- RAG & AI knowledge bases — turn docs sites into Markdown for retrieval-augmented generation
- LLM fine-tuning datasets — collect clean article text at scale
- Docs & blog migration — export a site's content to Markdown
- Competitive/content research — pull structured page content across a domain
Pricing
Pay-per-event: a small amount per page crawled. See the Pricing tab for current rates.
FAQ
What's the difference from a basic content scraper? This Pro version outputs clean Markdown (not just text), renders JavaScript sites with a real browser, extracts the main content with Readability, and supports sitemaps + glob filters — everything a RAG/LLM pipeline needs.
Do I need an API key? No. Just give it URLs and run — no account or key required.
Can it handle JavaScript / single-page apps?
Yes. Set crawlerType to browser and, if needed, waitForSelector or dynamicContentWaitSecs so client-rendered content loads before extraction.
What output format is best for AI/RAG? Markdown. It preserves headings, lists and links in a compact form that LLMs and chunkers handle well. Plain text and HTML are also available.
How many pages can it crawl?
Up to tens of thousands per run via maxCrawlPages, with sitemap seeding and glob filters to target exactly the pages you want.
Can I connect this to other apps and services? The Website Content Crawler Pro can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Notes
Original clean-room implementation using open-source libraries (Crawlee, Mozilla Readability, Turndown). Respects the target site's content; use responsibly and within each site's terms. This is an independent tool, not affiliated with any site it crawls.
Input
| Field | Type | Description |
|---|---|---|
urlsStart URLs | array | URLs to crawl. One per line. |
startUrlsStart URLs (request objects) | array | Advanced: start URLs as request objects. |
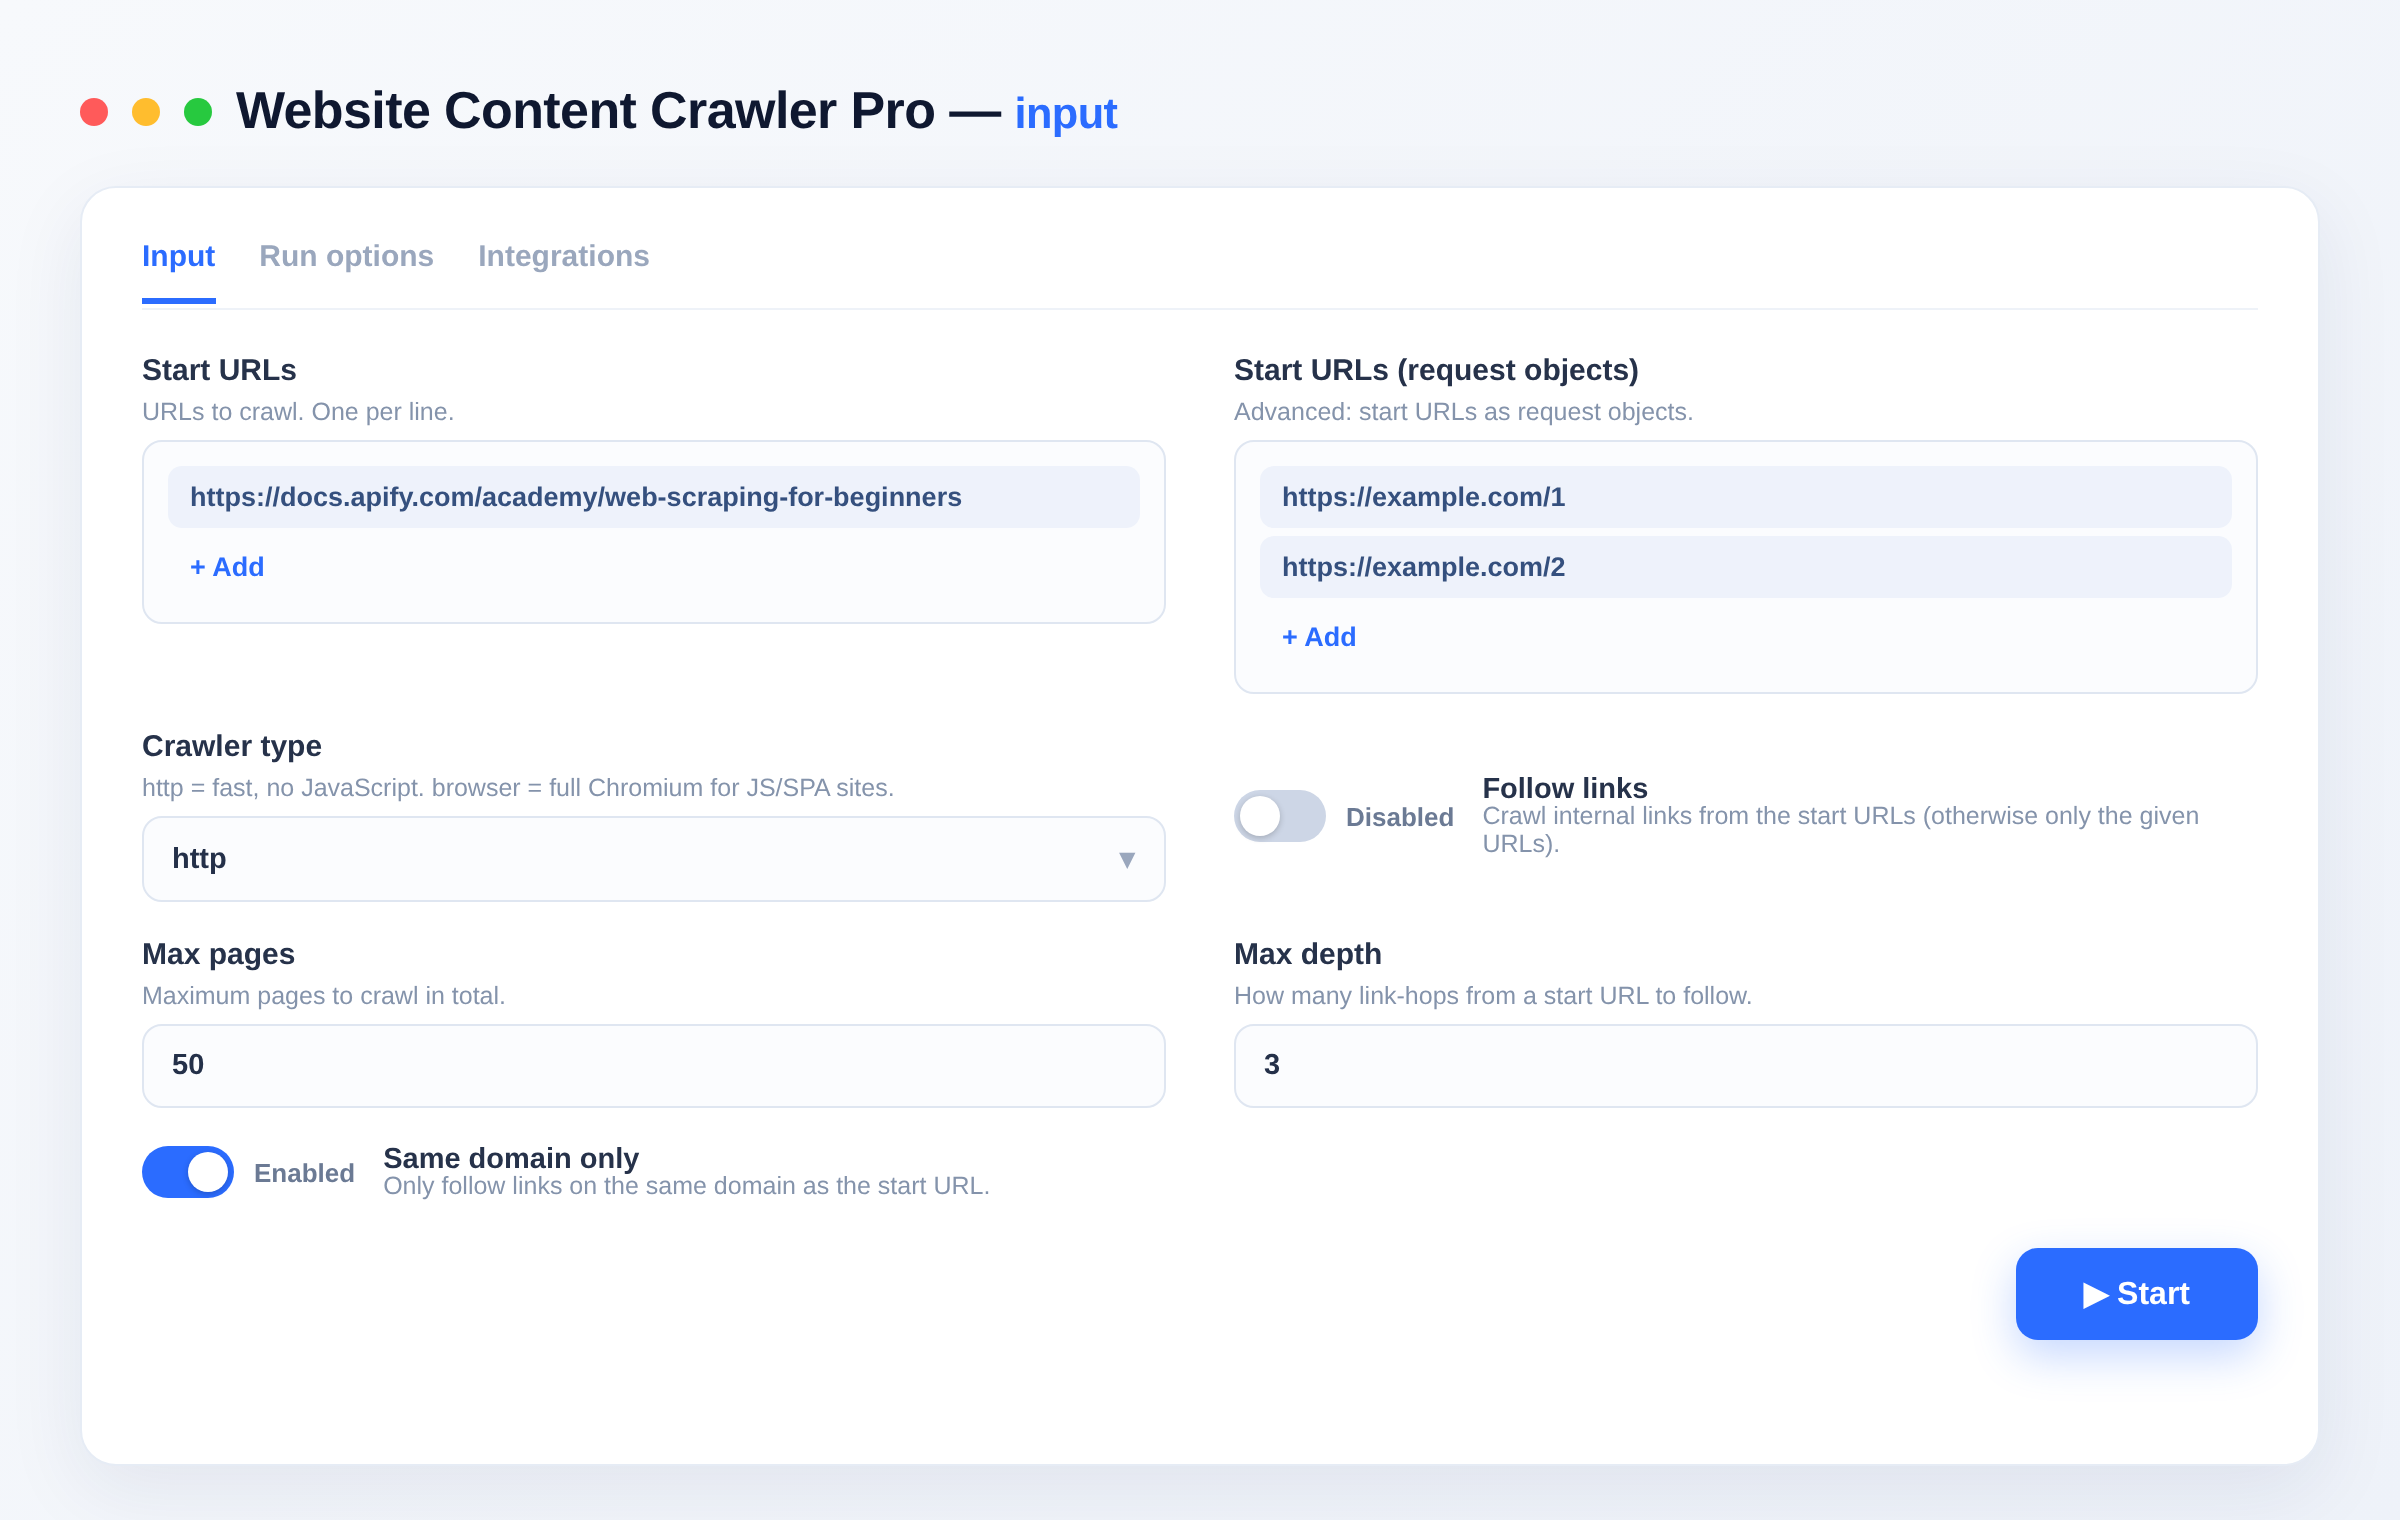
crawlerTypeCrawler type | string · http, browser | http = fast, no JavaScript. browser = full Chromium for JS/SPA sites. Default: "http" |
crawlFollow links | boolean | Crawl internal links from the start URLs (otherwise only the given URLs). Default: false |
maxCrawlPagesMax pages | integer | Maximum pages to crawl in total. Default: 50 |
maxCrawlDepthMax depth | integer | How many link-hops from a start URL to follow. Default: 3 |
sameDomainOnlySame domain only | boolean | Only follow links on the same domain as the start URL. Default: true |
includeUrlGlobsInclude URL globs | array | Only crawl URLs matching these glob patterns, e.g. https://site.com/docs/**. |
excludeUrlGlobsExclude URL globs | array | Skip URLs matching these glob patterns. |
useSitemapsUse sitemaps | boolean | Seed the crawl from each site's sitemap.xml. Default: false |
saveMarkdownSave Markdown | boolean | Output clean Markdown (ideal for LLMs/RAG). Default: true |
saveTextSave plain text | boolean | Output plain text. Default: true |
saveHtmlSave HTML | boolean | Include the cleaned content HTML. Default: false |
saveLinksSave links | boolean | Include the list of links found on each page. Default: false |
htmlTransformerContent extraction | string · readability, none | readability = extract the main article (strip nav/ads). none = keep the whole page body. Default: "readability" |
removeElementsCssSelectorRemove elements (CSS) | string | CSS selector of elements to strip before extraction (e.g. nav, footer, .ads). |
keepElementsCssSelectorKeep only (CSS) | string | If set, keep only content inside this CSS selector. |
removeCookieWarningsRemove cookie banners | boolean | Strip common cookie/consent banners. Default: true |
dynamicContentWaitSecsDynamic content wait (s) | integer | Browser mode: wait this many seconds for JS content to load. Default: 0 |
waitForSelectorWait for selector | string | Browser mode: wait until this CSS selector appears. |
textMaxCharsMax chars per page | integer | Truncate each page's text/markdown to this many characters (0 = no limit). Default: 0 |
maxConcurrencyConcurrency | integer | Max pages crawled in parallel. Default: 10 |
proxyConfigurationProxy | object | Proxy used only to fetch each page's main HTML. Scripts, styles and other page resources load directly. Default: {"useApifyProxy": true} |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~web-content-crawler-pro/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "urls": [
    "https://docs.apify.com/academy/web-scraping-for-beginners"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/web-content-crawler-pro").call(run_input={
"urls": [
"https://docs.apify.com/academy/web-scraping-for-beginners"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/web-content-crawler-pro').call({
"urls": [
"https://docs.apify.com/academy/web-scraping-for-beginners"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Page crawled One page crawled and converted to Markdown | $0.004 | $0.002 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
openFDA Scraper
Search FDA open data: drug/device/food recalls, drug labels and adverse-event reports by drug, manufacturer or keyword. Get classification, reason, firm, dates and details. For pharma, regulatory and safety research. No setup.
122 runs · 4 users · $0.0016 / record scraped
Weather Forecast Scraper
Fetch global weather forecasts and recent history for any place name or coordinates. Get hourly and daily temperature, precipitation, wind and more as structured JSON, CSV or Excel — for apps, dashboards, research and n8n.
64 runs · 1 users · $0.001 / forecast scraped
US Weather Alerts Scraper
Get active US weather alerts from the National Weather Service: event type, severity, urgency, affected areas, headline, full description, instructions and effective/expiry times. Filter by state and severity. Great for safety, logistics and monitoring. One row per alert as JSON, CSV or Excel.
36 runs · 2 users · $0.0004 / alert scraped
Earthquake Scraper
Collect global earthquakes with magnitude, place, time, depth, coordinates, tsunami and alert level. Filter by time window, magnitude, depth, bounding box or radius — export as JSON, CSV or Excel for alerts, maps, dashboards and research.
35 runs · 2 users · $0.0002 / earthquake scraped
Historical Weather Scraper
Download historical weather for any place or coordinates: daily or hourly temperature, precipitation, wind and more, back to 1940. One tidy row per day or hour, exported as JSON, CSV or Excel for research, energy, agriculture and analytics.
34 runs · 2 users · $0.0002 / row scraped
VesselFinder Scraper
Scrape ship data from VesselFinder by vessel name or IMO/MMSI: IMO, MMSI, callsign, type, flag, year built, length, beam, gross tonnage, deadweight, draught, course, speed, destination, ETA, last port, departure time and last position report.
13 runs · 2 users · $0.003 / vesselSend the site and the fields. We build it and you get it first.