Singapore Air Quality, PSI, UV & Dengue Alerts
hipersoft/sg-environment-scraper
Live Singapore environmental data in one Actor (official NEA feeds): PSI & PM2.5 by region with health bands, UV index, and active dengue clusters with case counts and location. Schedule it for alerts. No setup.
Total users
1Monthly users
1Total runs
97Per reading returned
$0.001Last rebuilt
Oct 28, 2026Overview
Live Singapore environmental data in one Actor — pulled from the official NEA real-time feeds on data.gov.sg. Get PSI and PM2.5 by region (with health bands), the national UV index, and every active dengue cluster (case counts + location) — as clean JSON, CSV or Excel. Schedule it to power alerts, dashboards and monitoring. No key, no login.
Great for facilities & construction, outdoor/events, health analytics, travel and smart-city apps.
What you get
- 🌫️ PSI — 24h PSI per region (west/east/central/south/north/national) + health band, and the pollutant sub-indices (PM2.5, PM10, O₃, NO₂, SO₂, CO)
- 😷 PM2.5 — 1-hour PM2.5 per region
- ☀️ UV index — latest national UV reading + band
- 🦟 Dengue clusters — active clusters with locality, total case size, breakdown (homes / public places / construction sites) and centroid coordinates
- 🧾 Provenance —
feed,timestamp,sourceUrl,collectedAton every row - ⏱️ Monitor-friendly — schedule it and each run appends a timestamped snapshot
Example input
{ "feeds": ["psi", "pm25", "uv", "dengue"] }
Pick any subset of feeds.
Output
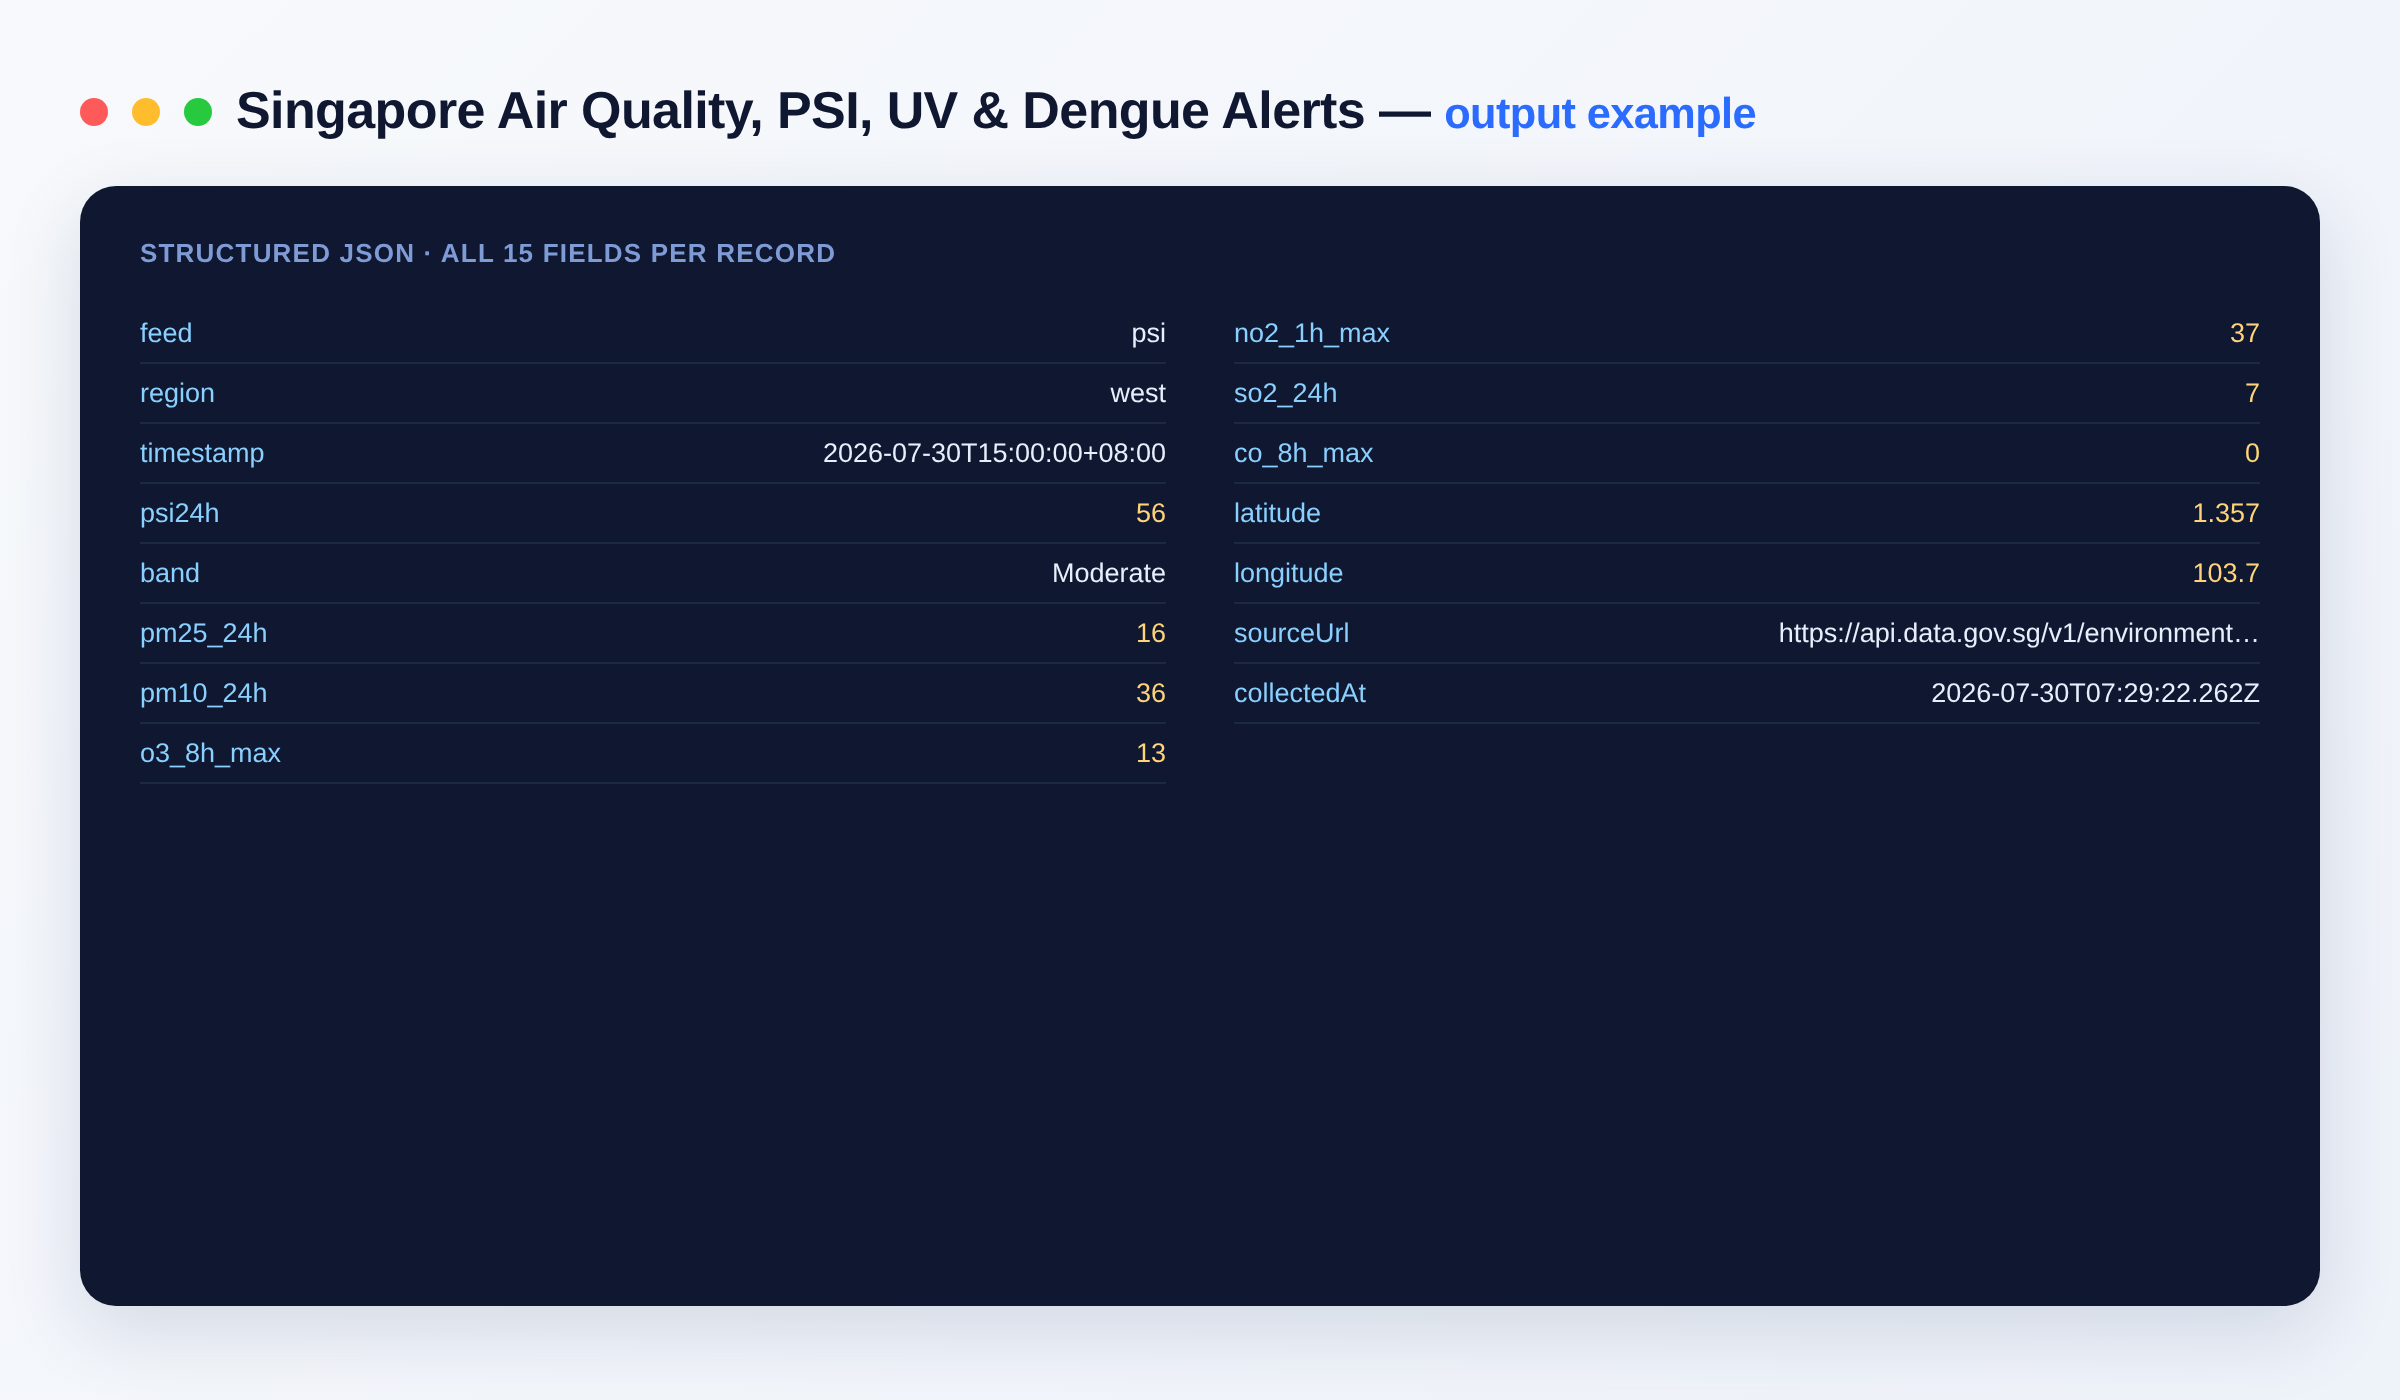
{ "feed": "psi", "region": "west", "timestamp": "2026-07-30T15:00:00+08:00",
  "psi24h": 56, "band": "Moderate", "pm25_24h": 14, "pm10_24h": 30,
  "latitude": 1.35735, "longitude": 103.7, "sourceUrl": "https://api.data.gov.sg/v1/environment/psi",
  "collectedAt": "2026-07-30T07:25:00.000Z" }
{ "feed": "dengue", "locality": "TAMPINES STREET 21", "caseSize": 12,
  "casesInHomes": 10, "casesInPublicPlaces": 2, "casesInConstructionSites": 0,
  "latitude": 1.3521, "longitude": 103.9445, "collectedAt": "2026-07-30T07:25:00.000Z" }
Output schema
Each row carries a feed field; the other fields depend on which feed produced the row.
| Field | Type | Description |
|---|---|---|
feed |
string | Which feed the row came from: psi, pm25, uv, or dengue. |
region |
string | Region the reading covers (west/east/central/south/north/national). |
timestamp |
string (ISO date) | Reading time reported by the source feed. |
psi24h |
integer | 24-hour PSI value (psi feed). |
band |
string | Health band label for the reading (psi and uv feeds). |
pm25_24h |
integer | 24-hour PM2.5 concentration (psi feed). |
pm10_24h |
integer | 24-hour PM10 concentration (psi feed). |
o3_8h_max |
integer | 8-hour maximum ozone sub-index (psi feed). |
no2_1h_max |
integer | 1-hour maximum nitrogen dioxide sub-index (psi feed). |
so2_24h |
integer | 24-hour sulphur dioxide sub-index (psi feed). |
co_8h_max |
integer | 8-hour maximum carbon monoxide sub-index (psi feed). |
pm25_1h |
integer | 1-hour PM2.5 concentration (pm25 feed). |
uvIndex |
number | Latest national UV index value (uv feed). |
id |
string | Cluster identifier (dengue feed). |
locality |
string | Cluster locality name (dengue feed). |
caseSize |
integer | Total cases in the cluster (dengue feed). |
casesInHomes |
integer | Cases at residential premises (dengue feed). |
casesInPublicPlaces |
integer | Cases at public places (dengue feed). |
casesInConstructionSites |
integer | Cases at construction sites (dengue feed). |
latitude |
number | Latitude for the region or dengue cluster centroid. |
longitude |
number | Longitude for the region or dengue cluster centroid. |
sourceUrl |
string (URL) | Official data.gov.sg feed the row was pulled from. |
collectedAt |
string (ISO date) | When this Actor collected the reading. |
Input fields
| Field | Description |
|---|---|
feeds |
Any of psi, pm25, uv, dengue (default all). |
FAQ
How current is it?
The NEA feeds update in near real time; timestamp is the reading time and collectedAt is your pull time.
What are the PSI bands? Good (0–50), Moderate (51–100), Unhealthy (101–200), Very Unhealthy (201–300), Hazardous (300+).
Can I get alerts? Schedule the Actor and compare each snapshot — e.g. notify when PSI enters "Unhealthy" or a new dengue cluster appears.
How does billing work? A tiny per-feed fetch charge plus pay per reading returned.
Can I integrate this with other tools? The Singapore Environment Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Notes
Original clean-room implementation using Singapore's official NEA open data (data.gov.sg), reused under the Singapore Open Data Licence. Not affiliated with or endorsed by NEA or the Singapore Government.
Input
| Field | Type | Description |
|---|---|---|
feedsFeeds | array | Which live feeds to pull. Default: ["psi", "pm25", "uv", "dengue"] |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~sg-environment-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/sg-environment-scraper").call(run_input={})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/sg-environment-scraper').call({});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Reading returned One environmental reading/cluster returned. | $0.001 | $0.0005 |
| Feed fetched One environmental feed fetched. | $0.003 | $0.003 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Europe PMC Scraper
Bulk-scrape life-science and biomedical literature from Europe PMC (40M+ records: PubMed, PMC, preprints, patents): title, abstract, authors, journal, year, DOI, PMID/PMCID, citation count, MeSH terms, open-access flag and full-text/PDF links. Thousands per run. No setup.
325 runs · 5 users · $0.001 / article scraped
arXiv Papers Scraper
Search and extract arXiv papers: title, abstract, authors, categories, published/updated dates, DOI, journal reference, and direct PDF links. Filter by category and sort by newest, recently updated or relevance. Fetch by arXiv ID too. For research, lit reviews and AI/ML monitoring. No setup.
140 runs · 2 users · $0.0025 / paper scraped
Letterboxd Scraper
Scrape Letterboxd films with ratings, rating counts, genres, director, cast, runtime and synopsis. Feed it film pages, a user's films/watchlist/diary, any list URL, or browse pages. For film data, recommendations and research.
139 runs · 7 users · $0.0042 / film scraped
OpenLibrary Book Scraper
Search millions of books on OpenLibrary by keyword, author, subject or ISBN and get title, authors, publisher, year, subjects, ISBNs, edition count, ratings, page count and cover. Clean, no setup.
124 runs · 5 users · $0.002 / book scraped
Semantic Scholar Scraper
Bulk-scrape academic papers from Semantic Scholar's 200M+ corpus: title, abstract, AI TLDR summary, authors, venue, year, citation & influential-citation counts, fields of study, DOI/PubMed/arXiv IDs and open-access PDF links. Filter by year, field and citations. Thousands per run. No setup.
123 runs · 7 users · $0.001 / paper scraped
Wikipedia Scraper
Search Wikipedia or look up exact articles and get the full plain-text content, summary, categories, image, Wikidata ID and monthly pageview trends. Any language. Great for research, RAG and AI datasets. No setup.
121 runs · 1 users · $0.001 / article scrapedSend the site and the fields. We build it and you get it first.