Hugging Face Scraper
hipersoft/huggingface-scraper
Scrape the Hugging Face Hub: search models, datasets and spaces by keyword, task, library or author. Get downloads, likes, tags, pipeline task, files and dates. No setup. For ML research, model discovery and monitoring.
Total users
1Monthly users
1Total runs
104Per item scraped
$0.0025Last rebuilt
Oct 28, 2026Overview
Search and export the Hugging Face Hub at scale. Pull models, datasets and Spaces by keyword, task, library, language or author — with downloads, likes, tags, task, files and dates — into clean JSON, CSV or Excel. No API key needed for public repos.
Perfect for model discovery, competitive/landscape research, tracking trending models, building ML dashboards, dataset sourcing and market monitoring.
What you can do
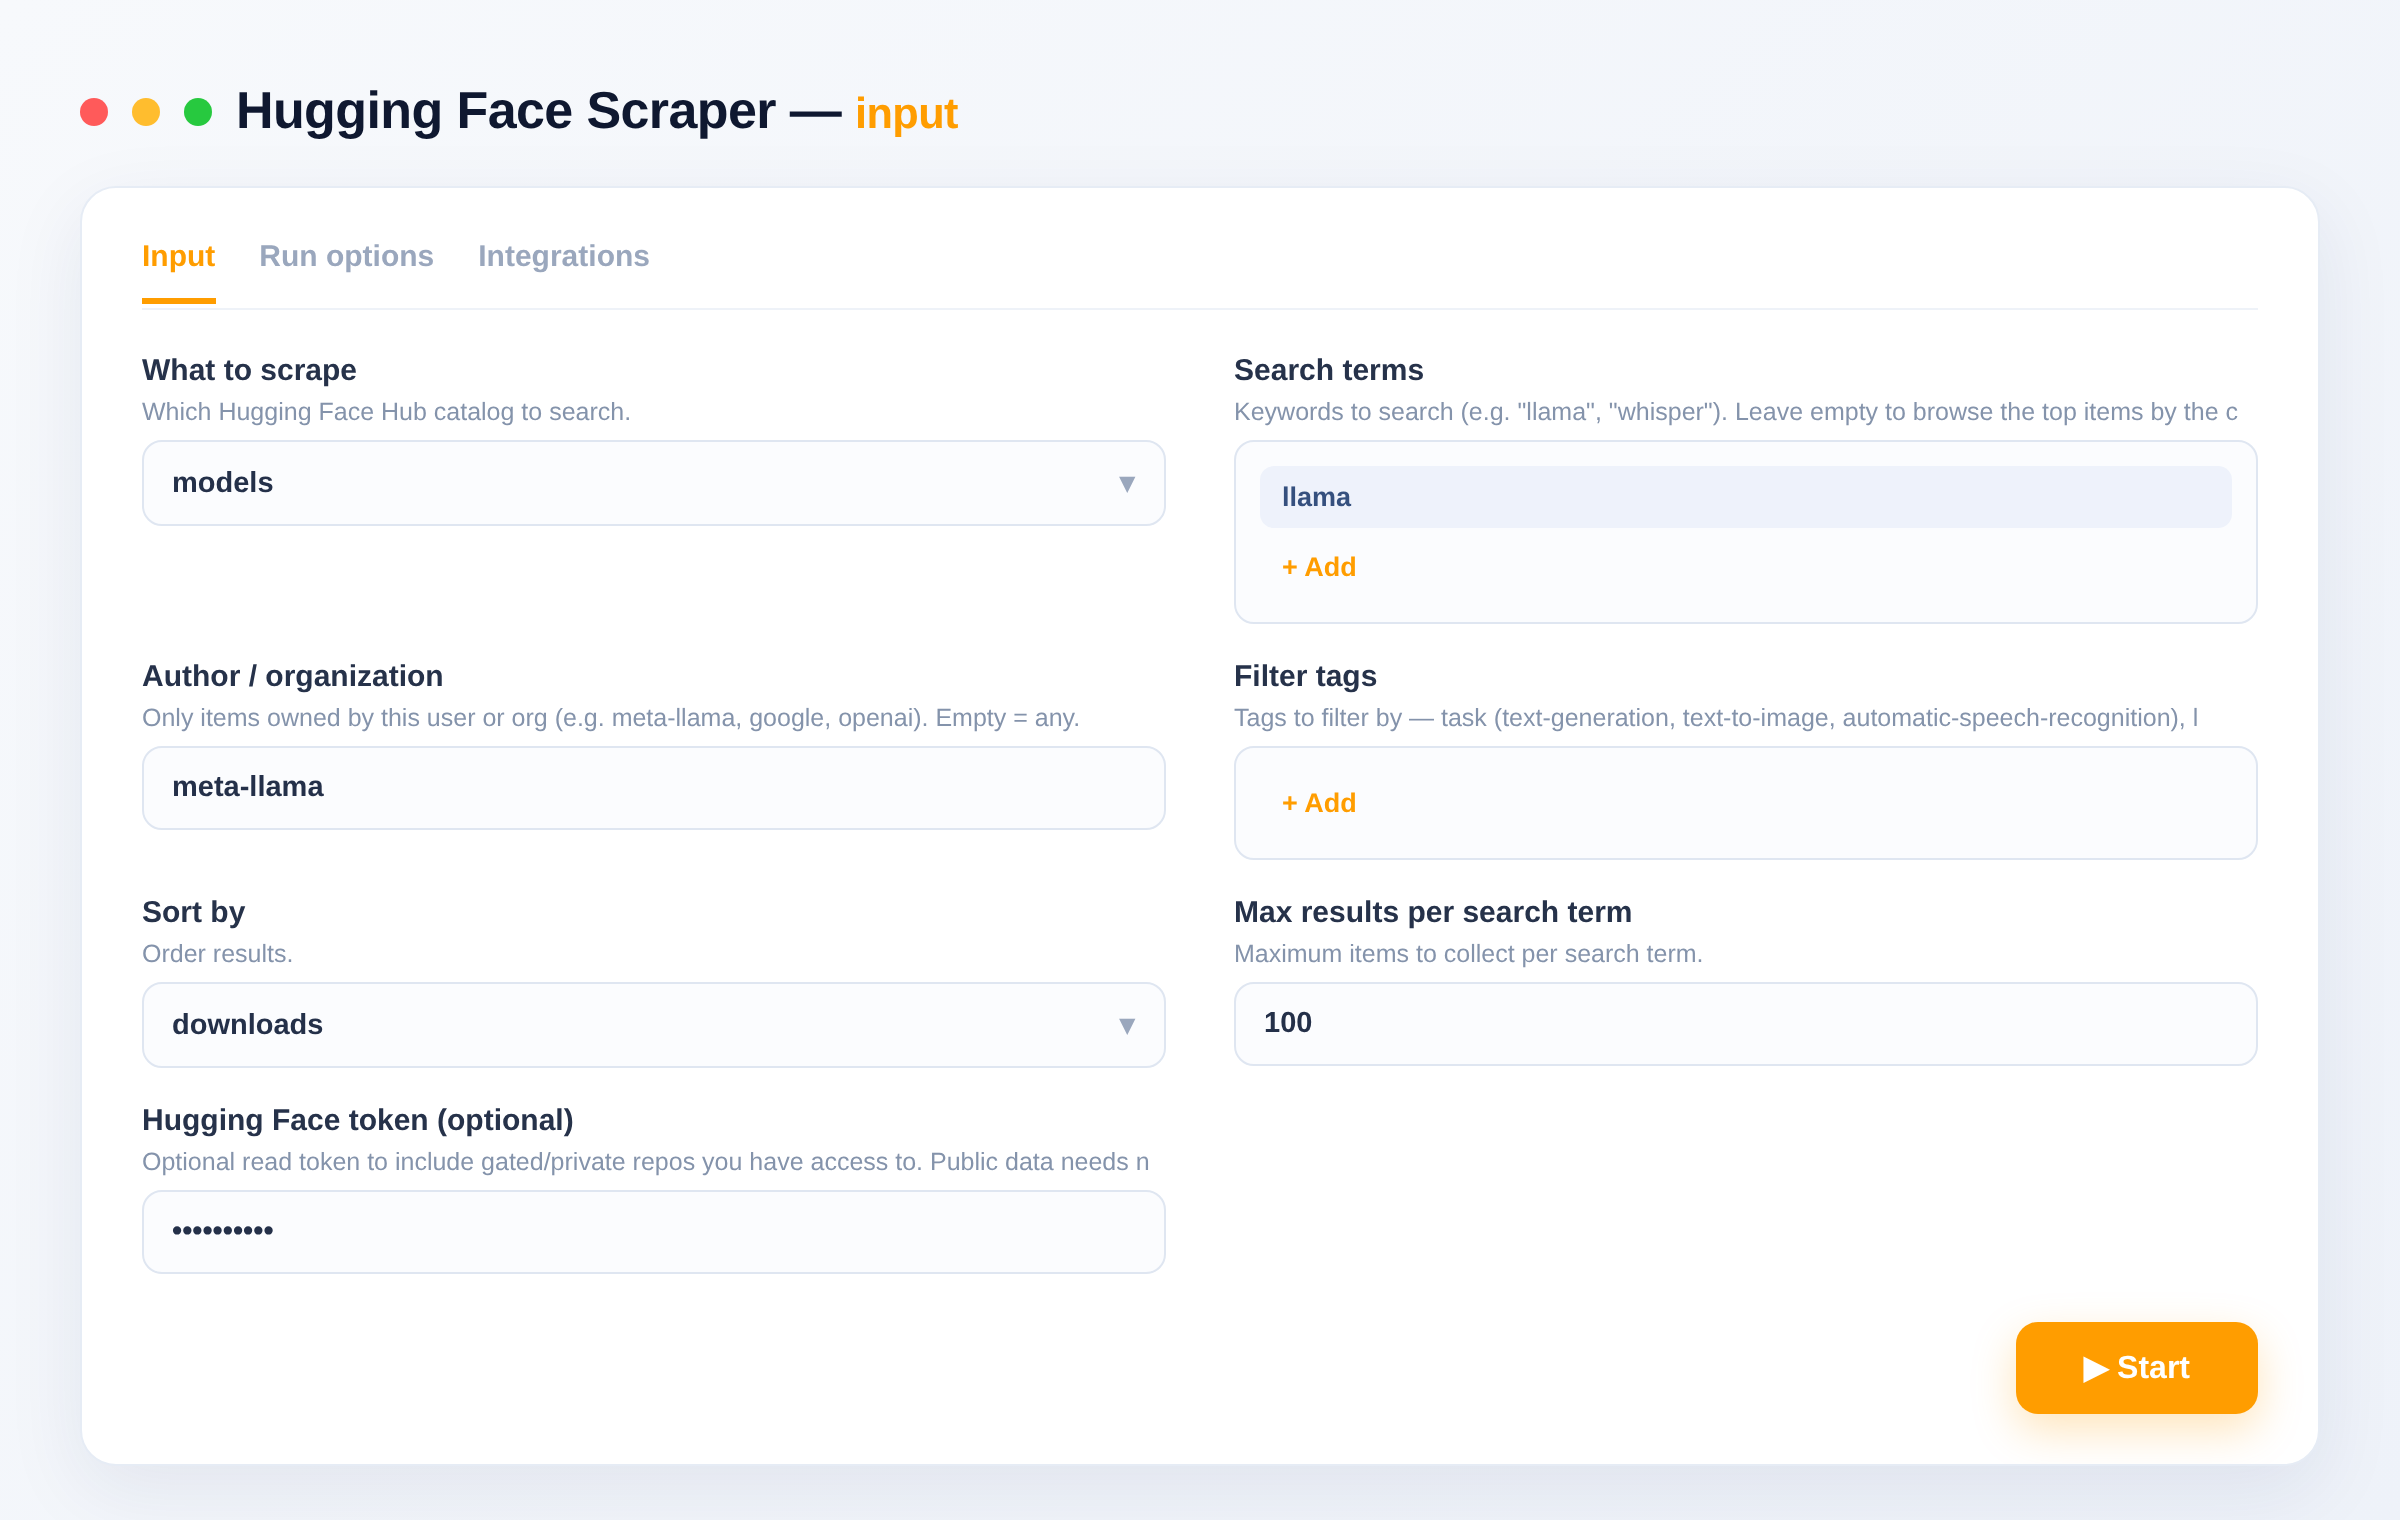
- 🔎 Search models, datasets or Spaces by keyword (
llama,whisper,stable diffusion) - 🏷️ Filter by tag — task (
text-generation,text-to-image,automatic-speech-recognition), library (transformers,pytorch), language (en,fr) or license - 👤 Filter by author/org —
meta-llama,google,openai,mistralai… - 📊 Sort by downloads, likes, trending, recently updated or recently created
- 📥 Bulk export — thousands of rows per run via automatic pagination
- 🔓 No key required for public data (add an optional read token for gated repos you can access)
Example input
{
  "contentType": "models",
  "searches": ["llama"],
  "filters": ["text-generation", "pytorch"],
  "author": "",
  "sort": "downloads",
  "maxResultsPerSearch": 500
}
Leave searches empty to browse the top items by your chosen sort (e.g. the 1,000 most-downloaded text-to-image models).
Output
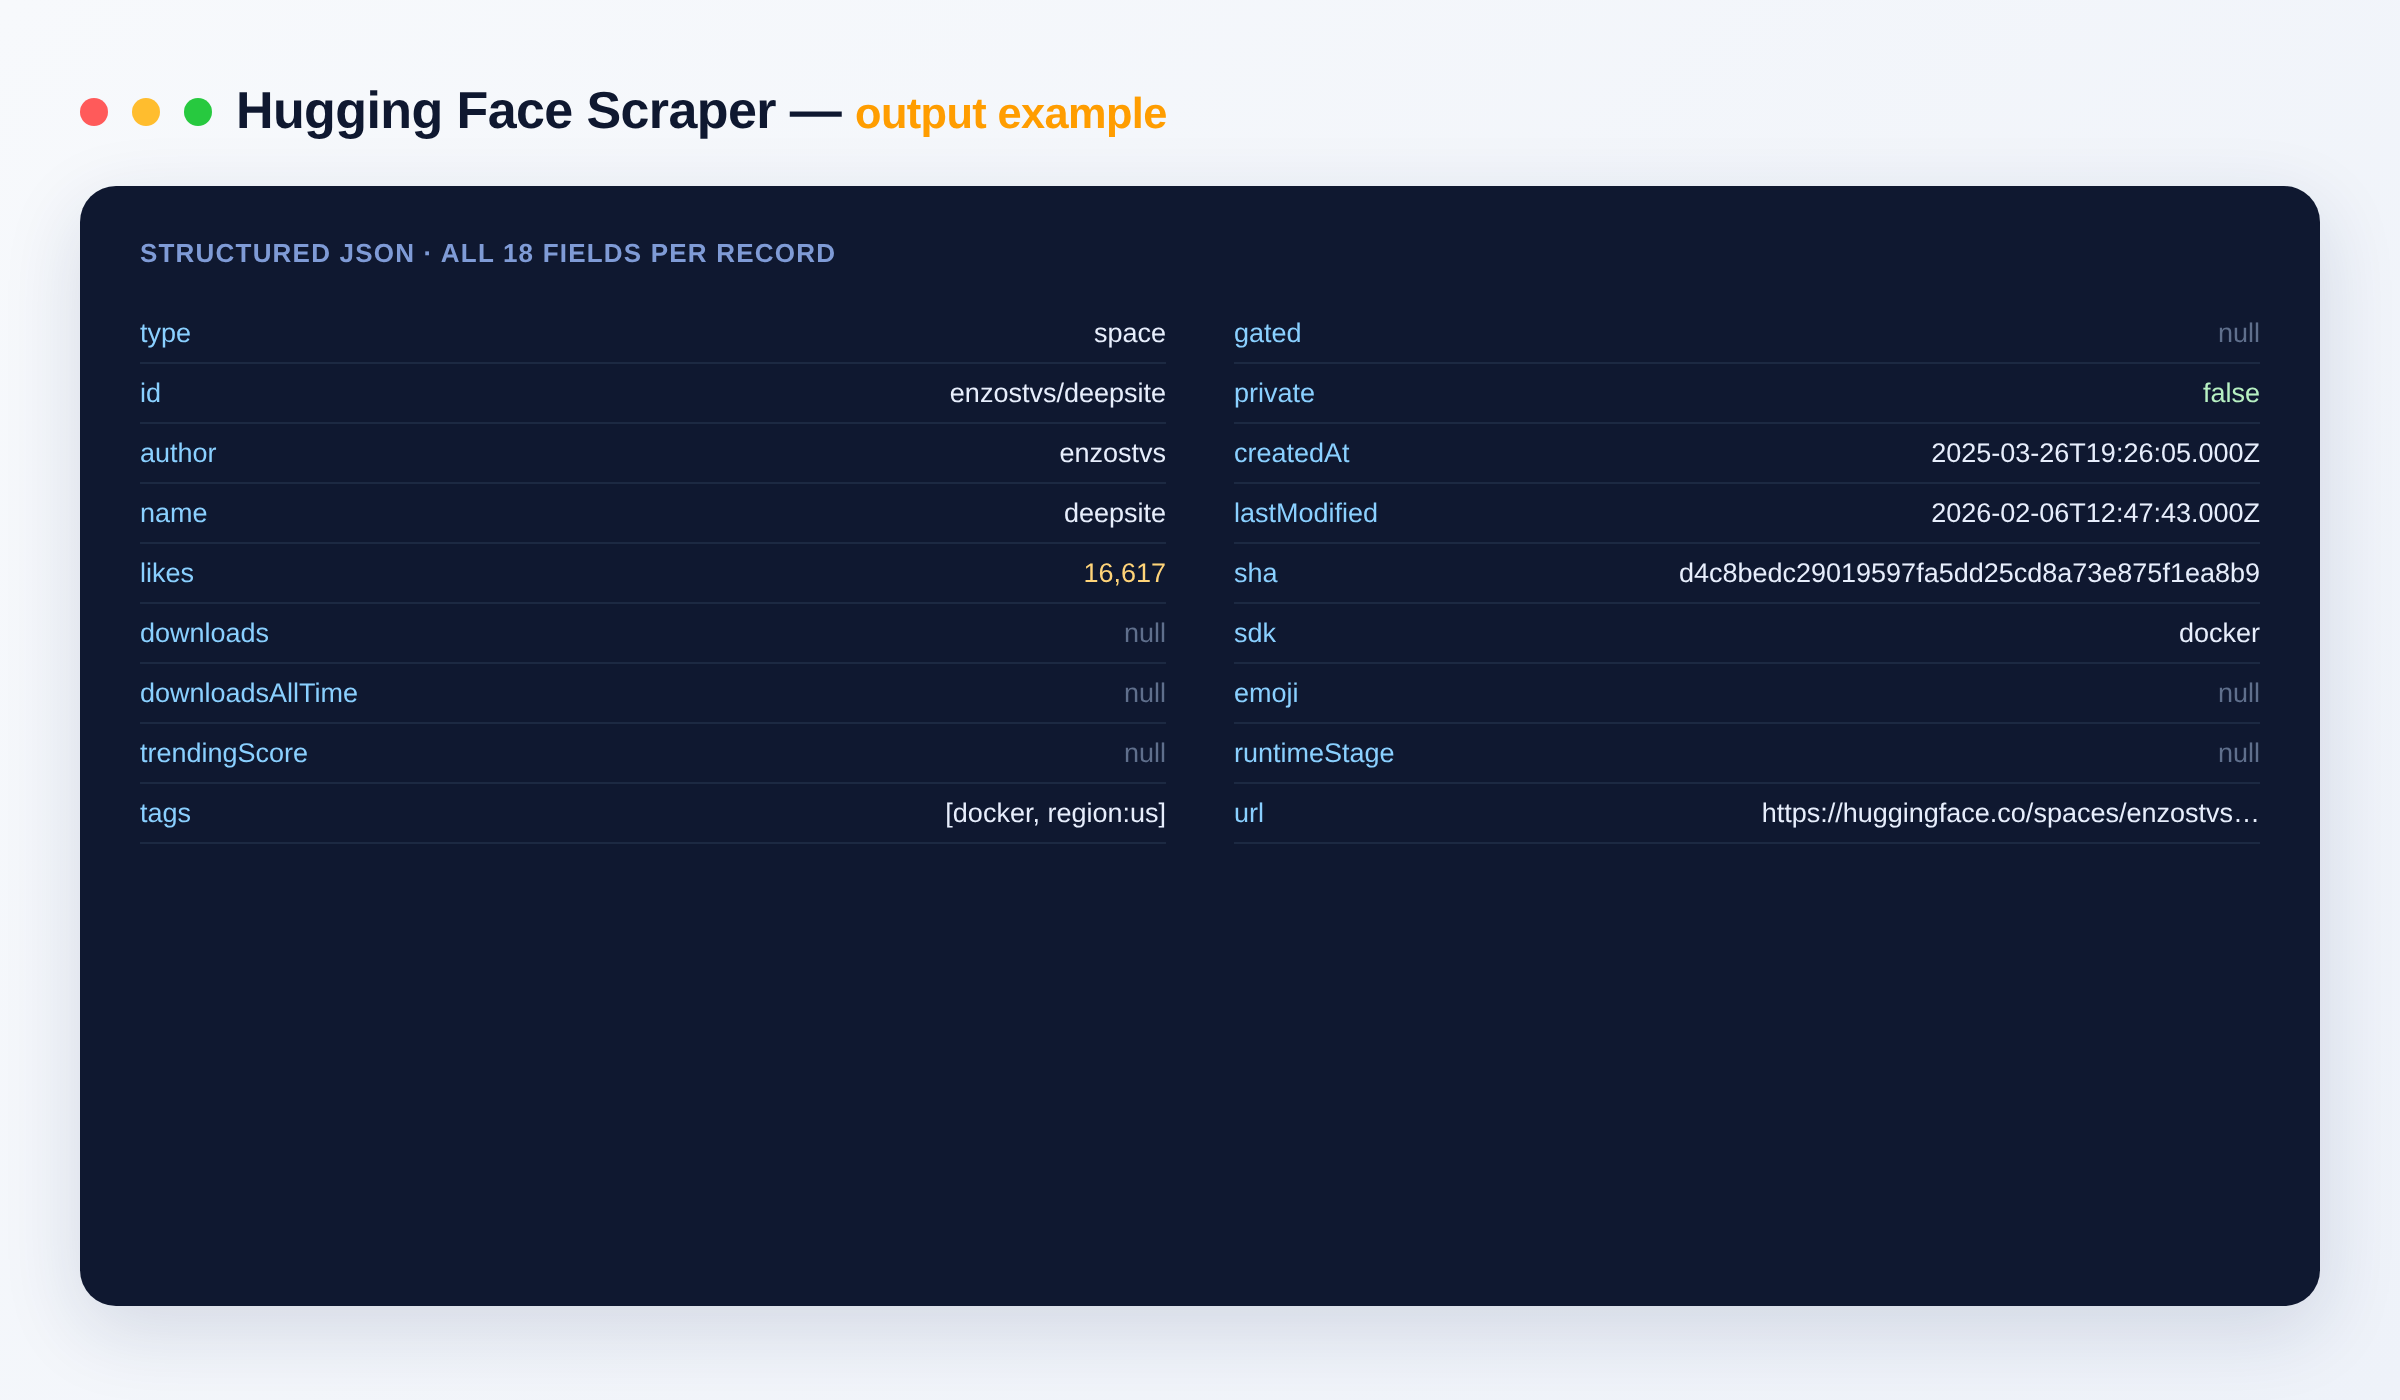
Each row is one repo.
{
  "type": "model",
  "id": "meta-llama/Llama-3.2-1B-Instruct",
  "author": "meta-llama",
  "name": "Llama-3.2-1B-Instruct",
  "downloads": 10449365,
  "likes": 1548,
  "pipelineTag": "text-generation",
  "library": "transformers",
  "tags": ["transformers", "safetensors", "llama", "conversational", "en", "…"],
  "filesCount": 14,
  "gated": true,
  "createdAt": "2024-09-18T…",
  "lastModified": "2024-10-24T…",
  "url": "https://huggingface.co/meta-llama/Llama-3.2-1B-Instruct"
}
Datasets add description; Spaces add sdk, emoji and runtimeStage. The url always links straight to the repo page.
Output schema
| Field | Type | Description |
|---|---|---|
type |
string | Repo type: model, dataset or space. |
id |
string | Full repo ID in author/name form. |
author |
string | User or organization that owns the repo. |
name |
string | Repo name without the author prefix. |
likes |
integer | Number of likes on the Hub. |
downloads |
string | Recent download count. |
downloadsAllTime |
string | All-time download count. |
trendingScore |
string | Hub trending score. |
tags |
array | Tags including task, library, language and license. |
gated |
string | Gating status for access-restricted repos. |
private |
boolean | Whether the repo is private. |
createdAt |
string (ISO date) | When the repo was created. |
lastModified |
string (ISO date) | When the repo was last updated. |
sha |
string | Latest commit hash. |
sdk |
string | Space SDK (Spaces only), e.g. gradio or streamlit. |
emoji |
string | Space thumbnail emoji (Spaces only). |
runtimeStage |
string | Space runtime status (Spaces only). |
url |
string (URL) | Public Hugging Face page for the repo. |
Input fields
| Field | Description |
|---|---|
contentType |
models, datasets or spaces. |
searches |
Keywords to search. Empty = browse top items by sort. |
author |
Restrict to one user/org (e.g. google). |
filters |
Tags to AND together — task, library, language, license. |
sort |
downloads, likes, lastModified, createdAt or trendingScore. |
maxResultsPerSearch |
Max rows per search term (up to 50,000). |
hfToken |
Optional read token for gated/private repos you can access. |
Use cases
- Model discovery & benchmarking — find the top models for a task, ranked by real downloads/likes
- Trend monitoring — track what's trending on the Hub over time
- Dataset sourcing — surface the best datasets for a domain (
medical,finance,code) - Competitive research — audit an org's full catalog of models/datasets/Spaces
- ML dashboards & alerts — feed clean Hub metadata into your own tooling
FAQ
Do I need a Hugging Face API key? No. All public models, datasets and Spaces are scraped without a key. Add a read token only if you want gated/private repos you already have access to.
How many results can I get?
Up to 50,000 per search term. Results are paginated automatically — leave searches empty and set a high limit to pull the entire top-of-catalog for a task.
Which tasks/filters are supported?
Any Hub tag — tasks like text-generation, text-to-image, image-classification, automatic-speech-recognition; libraries like transformers, diffusers, pytorch; languages; and licenses. Combine several to narrow results.
How does billing work? Pay per item scraped plus a small per-request charge — you only pay for what you pull.
Can I connect this Actor to other apps? The Hugging Face Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Notes
Original clean-room implementation using Hugging Face's public Hub API. You are responsible for how you use the scraped data and for complying with the Hub's terms and each repo's license. This is an independent tool and is not affiliated with or endorsed by Hugging Face.
Input
| Field | Type | Description |
|---|---|---|
contentTypeWhat to scrape | string · models, datasets, spaces | Which Hugging Face Hub catalog to search. Default: "models" |
searchesSearch terms | array | Keywords to search (e.g. "llama", "whisper"). Leave empty to browse the top items by the chosen sort. |
authorAuthor / organization | string | Only items owned by this user or org (e.g. meta-llama, google, openai). Empty = any. |
filtersFilter tags | array | Tags to filter by — task (text-generation, text-to-image, automatic-speech-recognition), library (pytorch, transformers), language (en, fr) or license. Multiple = AND. |
sortSort by | string · downloads, likes, lastModified, createdAt, trendingScore | Order results. Default: "downloads" |
maxResultsPerSearchMax results per search term | integer | Maximum items to collect per search term. Default: 100 |
hfTokenHugging Face token (optional) | string | Optional read token to include gated/private repos you have access to. Public data needs no token. |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~huggingface-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "searches": [
    "llama"
  ],
  "filters": [
    "text-generation",
    "pytorch"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/huggingface-scraper").call(run_input={
"searches": [
"llama"
],
"filters": [
"text-generation",
"pytorch"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/huggingface-scraper').call({
"searches": [
"llama"
],
"filters": [
"text-generation",
"pytorch"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Item scraped One model, dataset or Space record scraped. | $0.0025 | $0.0013 |
| API request One Hugging Face Hub page request (up to 100 items). | $0.0005 | $0.0005 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Europe PMC Scraper
Bulk-scrape life-science and biomedical literature from Europe PMC (40M+ records: PubMed, PMC, preprints, patents): title, abstract, authors, journal, year, DOI, PMID/PMCID, citation count, MeSH terms, open-access flag and full-text/PDF links. Thousands per run. No setup.
325 runs · 5 users · $0.001 / article scraped
arXiv Papers Scraper
Search and extract arXiv papers: title, abstract, authors, categories, published/updated dates, DOI, journal reference, and direct PDF links. Filter by category and sort by newest, recently updated or relevance. Fetch by arXiv ID too. For research, lit reviews and AI/ML monitoring. No setup.
140 runs · 2 users · $0.0025 / paper scraped
Letterboxd Scraper
Scrape Letterboxd films with ratings, rating counts, genres, director, cast, runtime and synopsis. Feed it film pages, a user's films/watchlist/diary, any list URL, or browse pages. For film data, recommendations and research.
139 runs · 7 users · $0.0042 / film scraped
OpenLibrary Book Scraper
Search millions of books on OpenLibrary by keyword, author, subject or ISBN and get title, authors, publisher, year, subjects, ISBNs, edition count, ratings, page count and cover. Clean, no setup.
124 runs · 5 users · $0.002 / book scraped
Semantic Scholar Scraper
Bulk-scrape academic papers from Semantic Scholar's 200M+ corpus: title, abstract, AI TLDR summary, authors, venue, year, citation & influential-citation counts, fields of study, DOI/PubMed/arXiv IDs and open-access PDF links. Filter by year, field and citations. Thousands per run. No setup.
123 runs · 7 users · $0.001 / paper scraped
Wikipedia Scraper
Search Wikipedia or look up exact articles and get the full plain-text content, summary, categories, image, Wikidata ID and monthly pageview trends. Any language. Great for research, RAG and AI datasets. No setup.
121 runs · 1 users · $0.001 / article scrapedSend the site and the fields. We build it and you get it first.