SoundCloud Scraper
hipersoft/soundcloud-scraper
Search SoundCloud and scrape tracks (plays, likes, reposts, genre, duration), artists (followers, track count, location) and playlists. Resolve any SoundCloud URL. Fast clean HTTP. For music analytics, A&R and marketing.
Total users
2Monthly users
2Total runs
116Per item scraped
$0.0025Last rebuilt
Oct 28, 2026Overview
Search SoundCloud and pull clean, structured JSON for tracks, artists (users) and playlists — including play counts, likes, reposts, followers and genres. You can also drop in any SoundCloud URL and resolve it directly. No login and no account needed. Fast and reliable.
Features
- 🎧 Tracks, users & playlists — set
searchTypetoall,track,userorplaylist. - 📊 Engagement metrics — tracks come with
playbackCount,likesCount,repostsCountandcommentCount. - 👤 Artist intelligence — user records include
followersCount,trackCount,city,countryCodeandverified. - 🔗 Resolve any URL — paste track/user/playlist links into
urlsto scrape them directly, no search needed. - 🎚️ Volume control —
maxItemsPerSearch(1–2000) with automatic pagination per search term. - 🧱 Clean text fields — descriptions and tags are stripped of HTML and decoded, ready to use.
Use cases
- Find rising tracks in a genre by sorting on
playbackCountandlikesCount. - Build A&R shortlists of artists by
followersCountand location. - Monitor a track or artist's engagement over time.
- Enrich a music dataset with genres, durations and artwork.
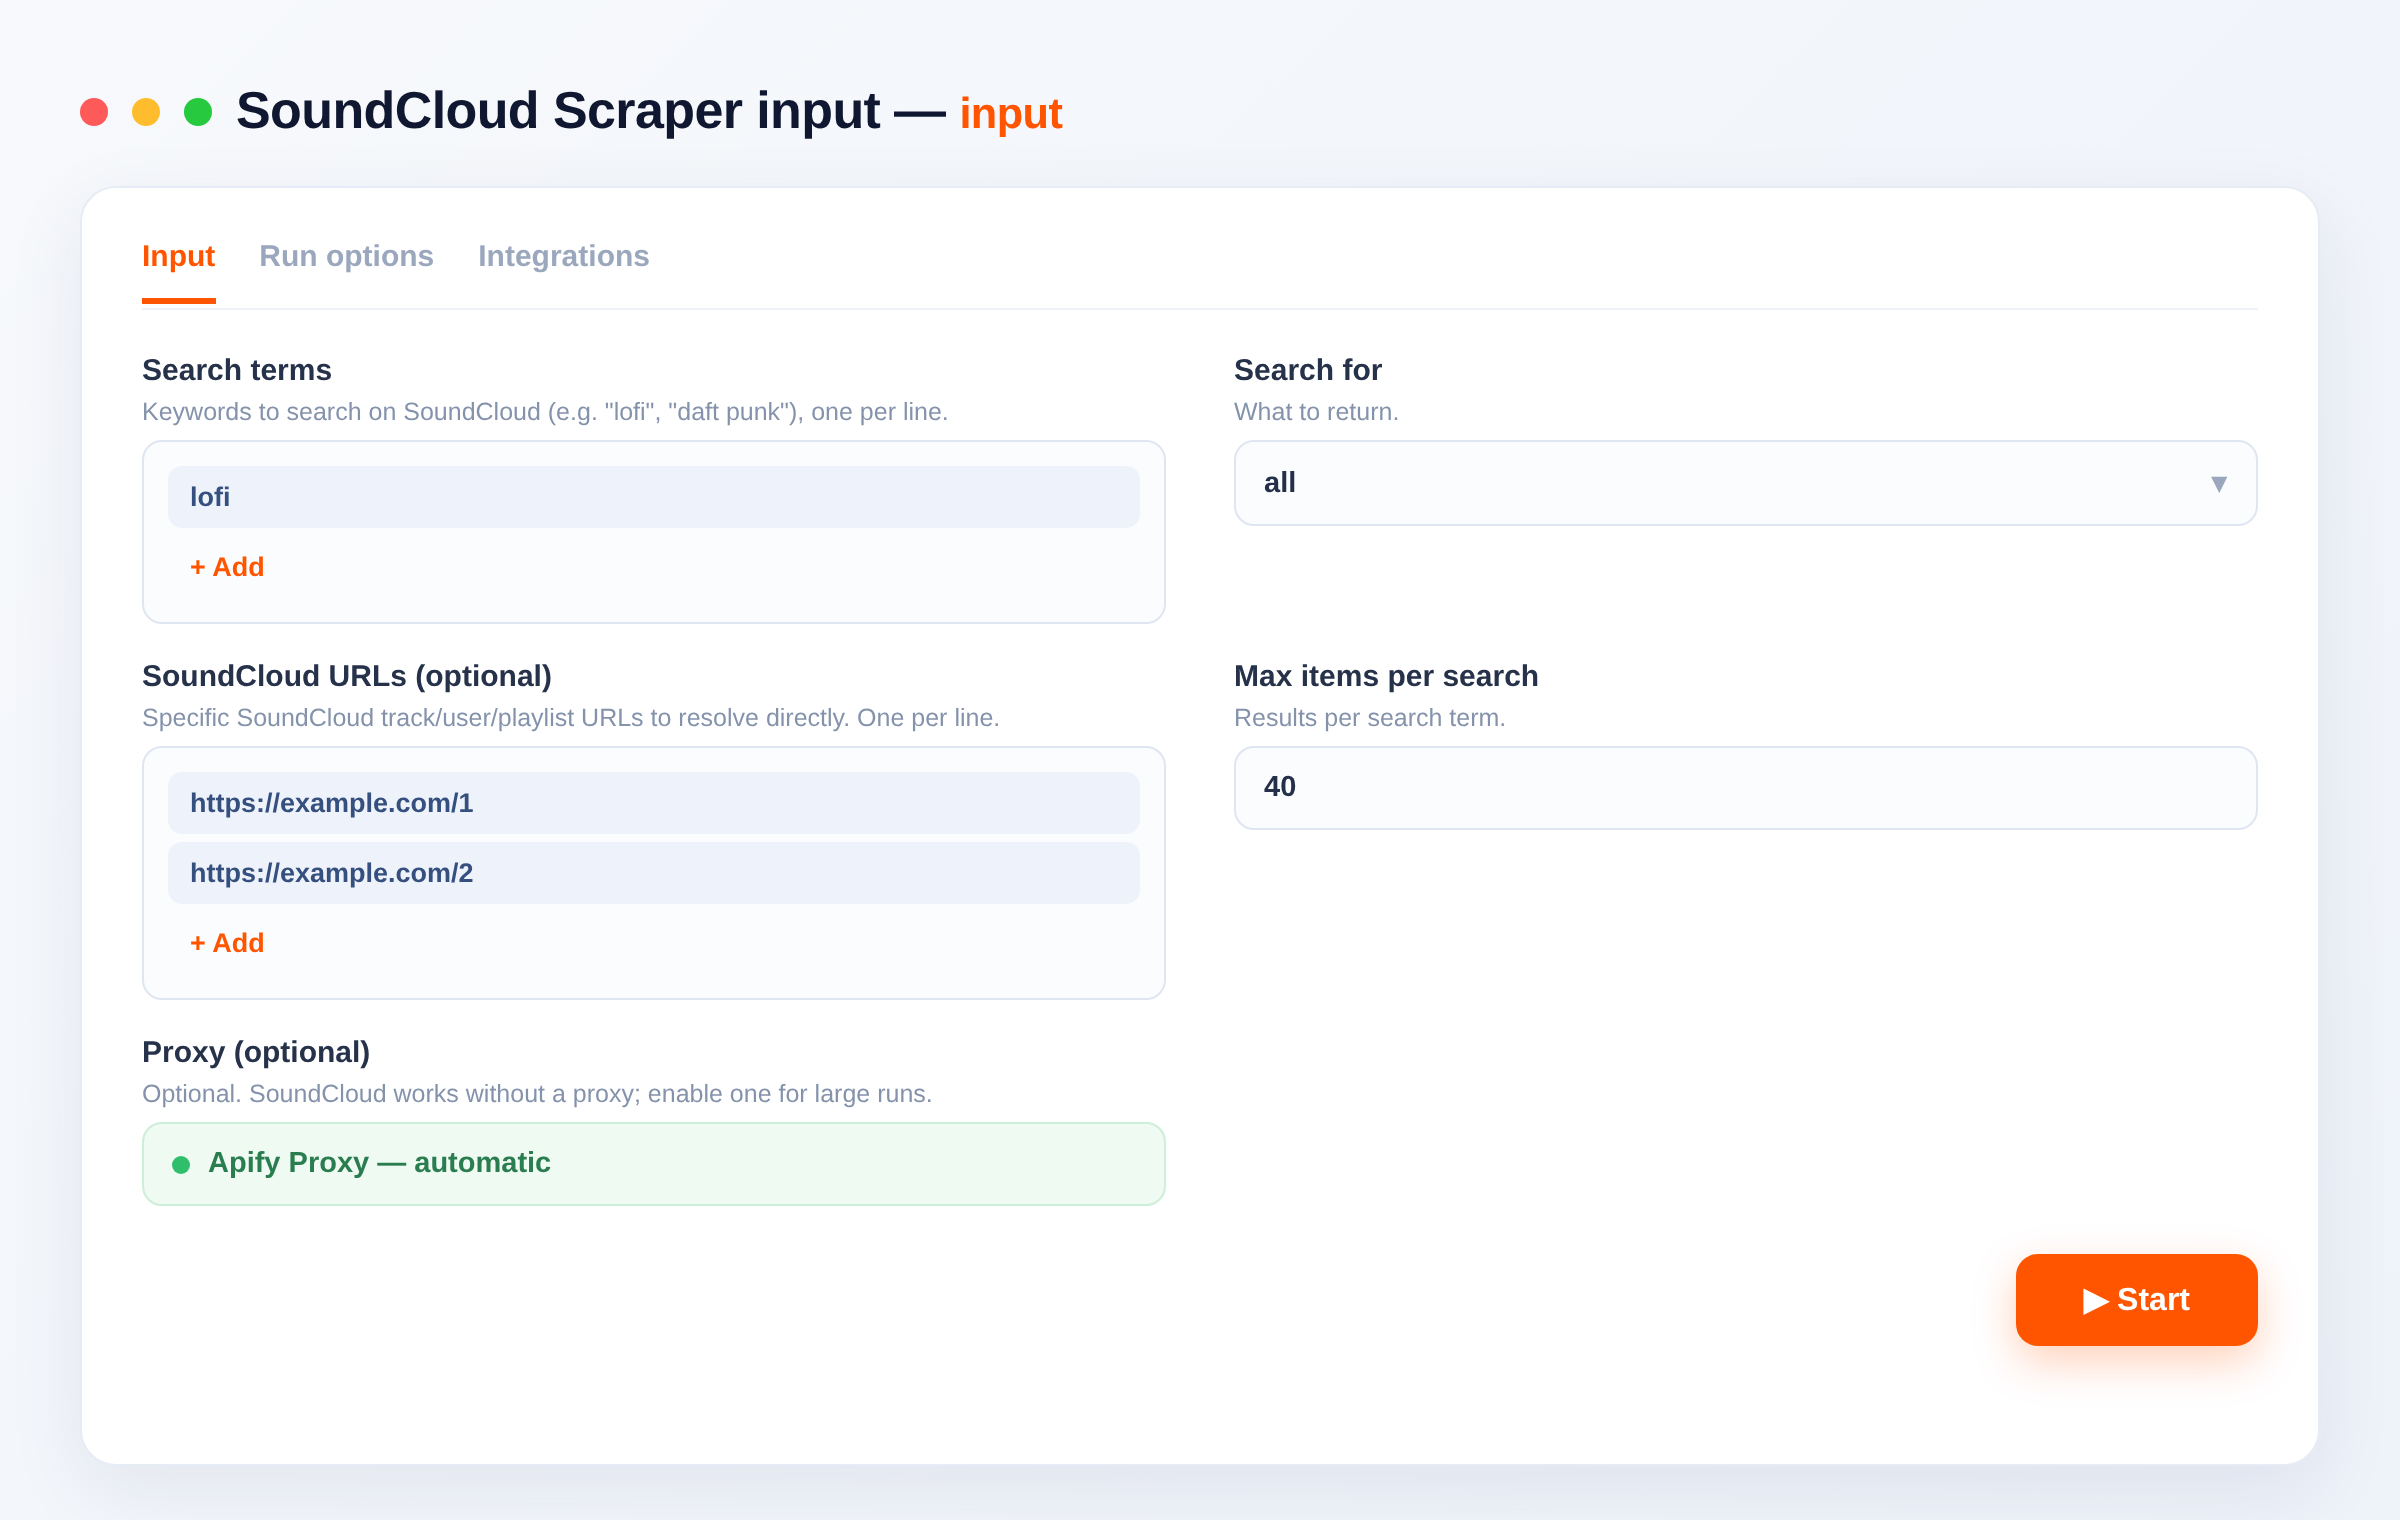
Input
{
  "searches": ["lofi", "deep house"],
  "searchType": "track",
  "urls": [],
  "maxItemsPerSearch": 40
}
| Field | Description |
|---|---|
searches |
Keywords to search on SoundCloud, one per line. |
searchType |
What to return: all, track, user or playlist. |
urls |
Specific SoundCloud track/user/playlist URLs to resolve directly. |
maxItemsPerSearch |
Results per search term (1–2000). |
What you get
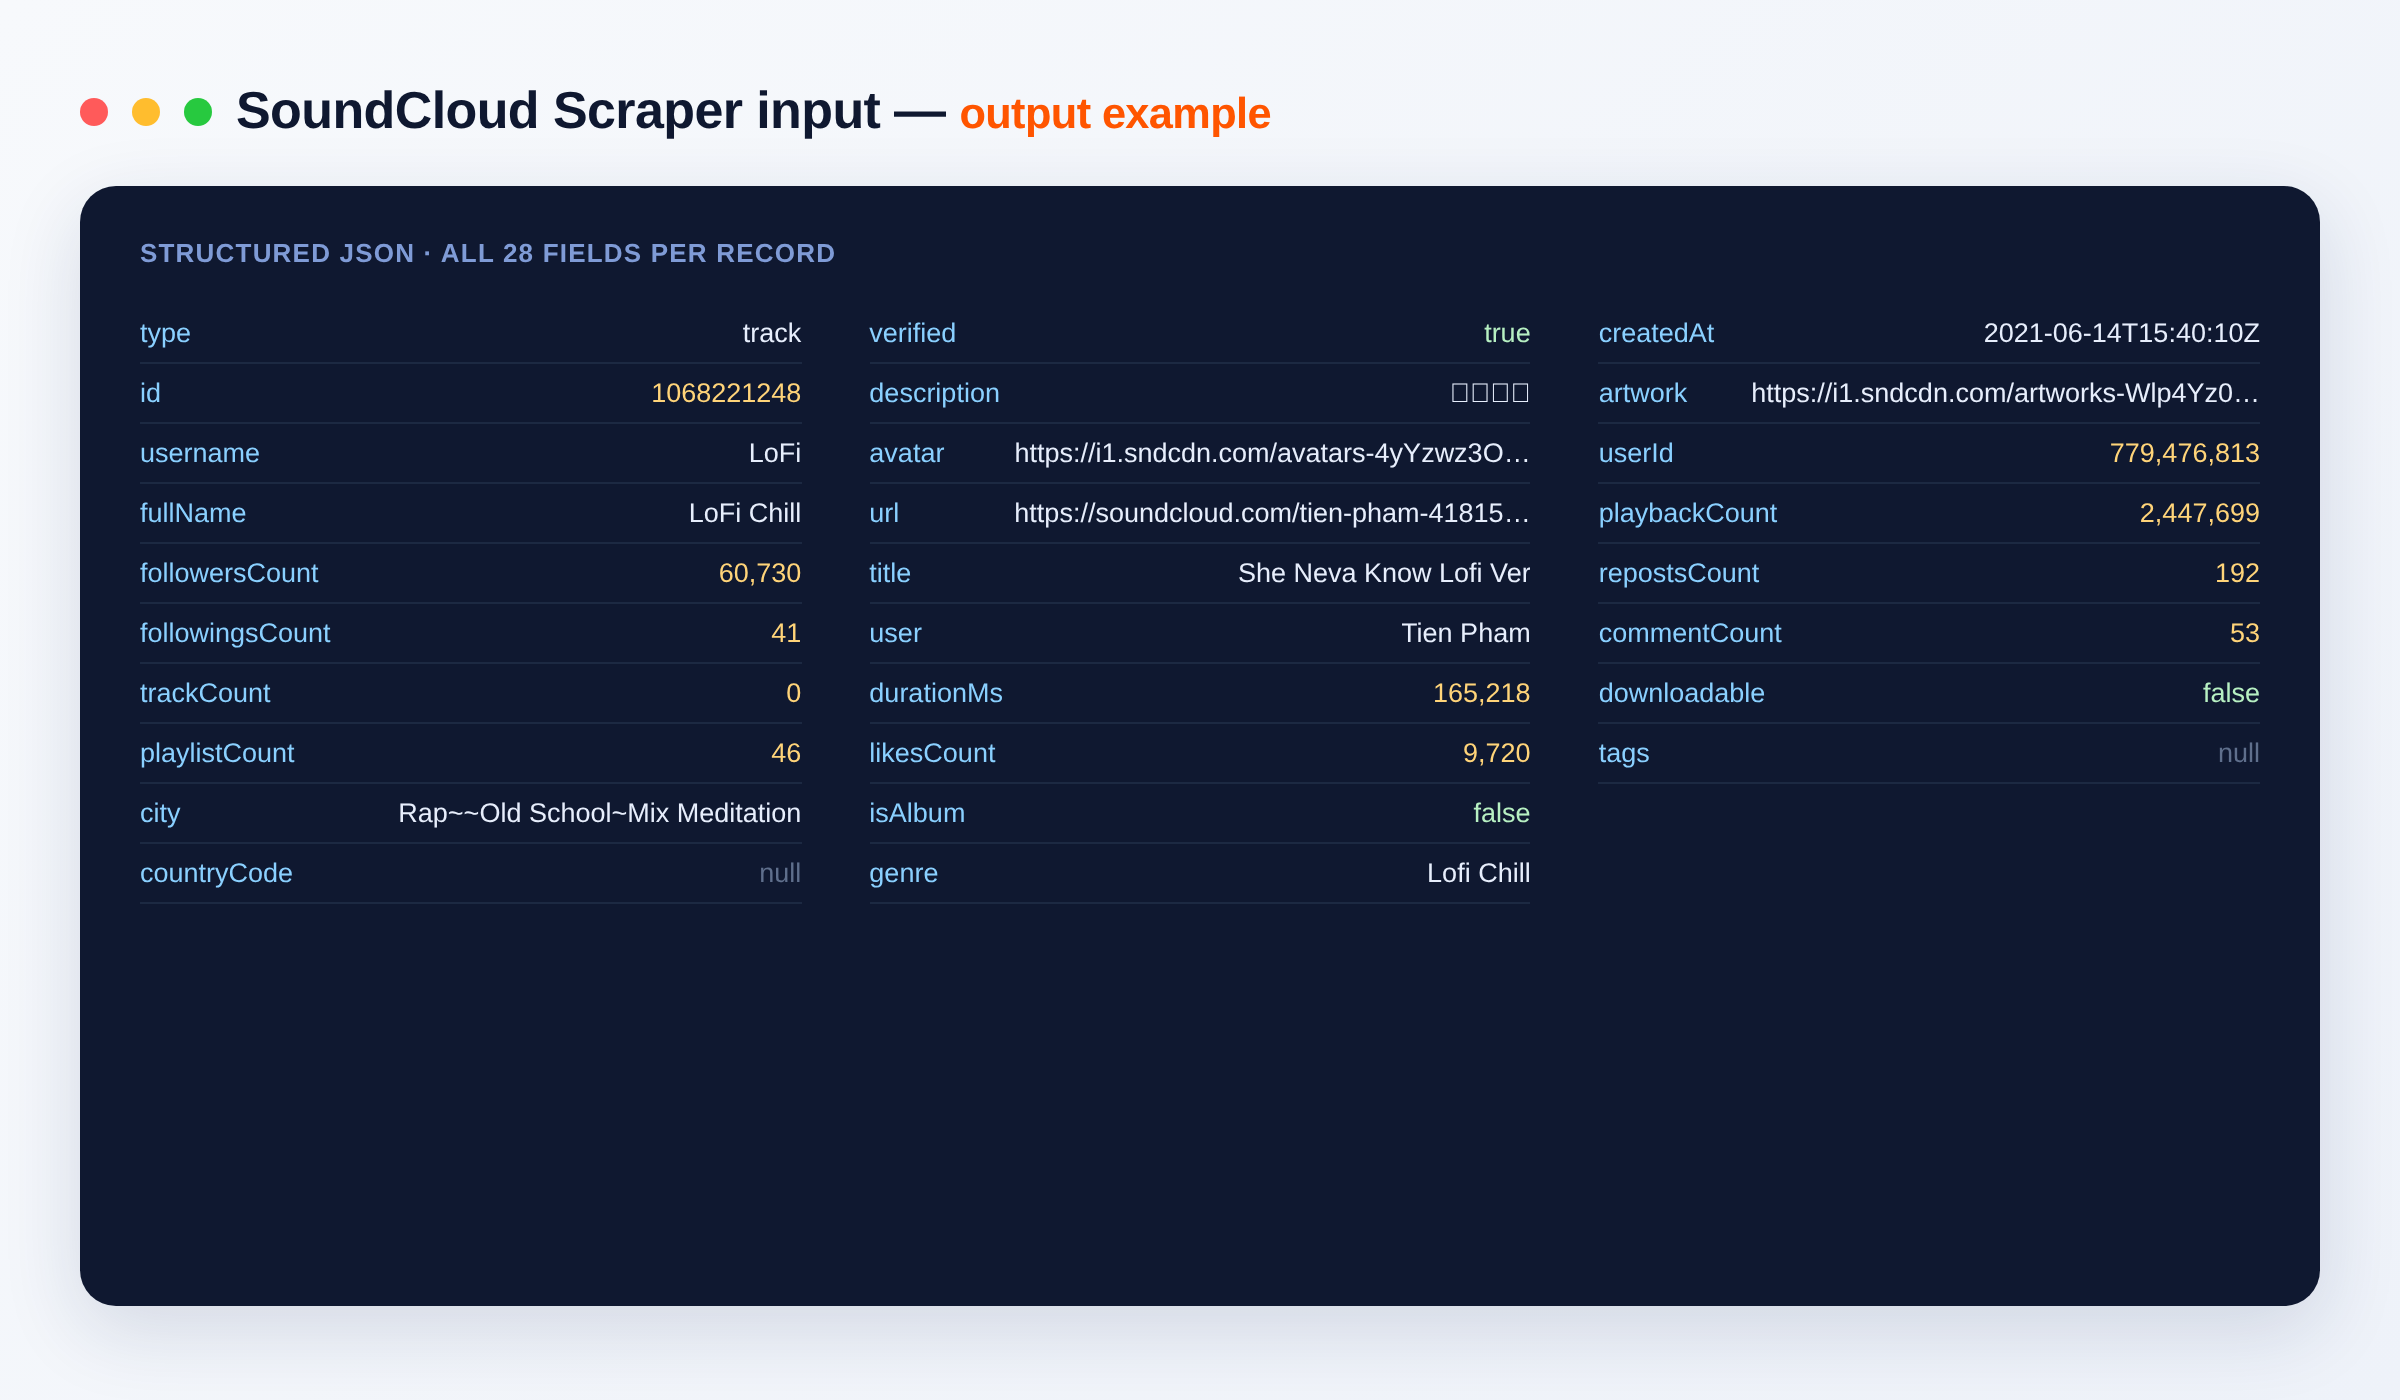
One flat JSON record per item. Example track:
{
  "type": "track",
  "id": 123456789,
  "title": "Late Night Lofi",
  "user": "chillbeats",
  "userId": 987654,
  "durationMs": 184000,
  "genre": "Lo-fi",
  "playbackCount": 254800,
  "likesCount": 9800,
  "repostsCount": 1200,
  "commentCount": 340,
  "downloadable": false,
  "createdAt": "2023-04-12T10:20:30Z",
  "tags": "lofi chill study",
  "description": "A mellow beat for late nights.",
  "artwork": "https://i1.sndcdn.com/artworks-....-t500x500.jpg",
  "url": "https://soundcloud.com/chillbeats/late-night-lofi"
}
Output schema
Fields returned per artist/user record (track and playlist records carry their own metrics such as playbackCount, likesCount, repostsCount, commentCount, genre and durationMs):
| Field | Type | Description |
|---|---|---|
type |
string | Item type: track, user or playlist. |
id |
integer | SoundCloud's numeric identifier for the item. |
username |
string | Artist's SoundCloud handle. |
fullName |
string | Artist's display name. |
followersCount |
integer | Number of followers. |
followingsCount |
integer | Number of accounts the artist follows. |
trackCount |
integer | Number of tracks the artist has uploaded. |
playlistCount |
integer | Number of playlists the artist has created. |
city |
string | City listed on the profile. |
countryCode |
string | Country code listed on the profile. |
verified |
boolean | Whether the account is verified. |
description |
string | Profile or item description text. |
avatar |
string (URL) | Avatar / artwork image URL. |
url |
string (URL) | Link to the item on SoundCloud. |
Building a music dataset? Pair this with our other music and media scrapers:
- Spotify Scraper — tracks, artists, albums and playlists.
- Deezer Scraper — tracks, artists, albums, playlists and global top charts with ISRCs.
- Discogs Scraper — vinyl, CD and digital releases with marketplace prices and community stats.
- Apple Podcasts Scraper — podcast shows and episodes with RSS feeds and artwork.
FAQ
Do I need a SoundCloud account or login? No. Just add your search terms or URLs and run — no account, login or setup required.
How many tracks can I get per run?
Set maxItemsPerSearch up to 2,000 per search term, with pagination handled automatically. Add more keywords in searches to scale the run further.
Can I download tracks or audio? No. This Actor returns public metadata only — titles, engagement metrics, genres, artwork URLs and descriptions. It does not download audio streams or files.
What's the output format? One flat JSON record per item, with clean, decoded text fields. Export as JSON, CSV or Excel from the dataset.
Can I scrape a specific track, artist or playlist URL?
Yes. Paste any SoundCloud track, user or playlist link into urls to resolve it directly, no search required.
Can I connect it to other tools? The SoundCloud Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Notes
Returns public metadata only — no audio streams or downloads. Not affiliated with, endorsed by, or connected to SoundCloud; all trademarks belong to their respective owners.
Input
| Field | Type | Description |
|---|---|---|
searchesSearch terms | array | Keywords to search on SoundCloud (e.g. "lofi", "daft punk"), one per line. |
searchTypeSearch for | string · all, track, user, playlist | What to return. Default: "all" |
urlsSoundCloud URLs (optional) | array | Specific SoundCloud track/user/playlist URLs to resolve directly. One per line. |
maxItemsPerSearchMax items per search | integer | Results per search term. Default: 40 |
proxyConfigurationProxy (optional) | object | Optional. SoundCloud works without a proxy; enable one for large runs. Default: {"useApifyProxy": false} |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~soundcloud-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "searches": [
    "lofi"
  ],
  "urls": []
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/soundcloud-scraper").call(run_input={
"searches": [
"lofi"
],
"urls": []
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/soundcloud-scraper').call({
"searches": [
"lofi"
],
"urls": []
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Item scraped One track, artist or playlist with full metadata (plays, likes, followers) | $0.0025 | $0.0013 |
| API request One SoundCloud api-v2 request (a search page or a resolve) | $0.001 | $0.001 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Carousell Scraper
Scrape Carousell search listings: title, price, condition, location, seller, photo and URL. Requires your own Carousell app token.
242 runs · 2 users · $0.003 / listing scraped
Google Flights Scraper
Scrape flight options from Google Flights by route and date: airline, flight number, departure and arrival times, duration, stops, layovers and price. One-way or round-trip, any cabin and currency. For travel and price monitoring.
216 runs · 4 users · $0.004 / flight scraped
Pinterest Scraper
Search Pinterest and scrape pins (title, description, destination link, image, pinner, board, saves), boards and users. Fast. For visual research, e-commerce, trend and marketing analysis.
151 runs · 2 users · $0.0034 / item scraped
Google Trends Scraper
Scrape Google Trends for any keyword: interest over time, related and rising queries, and interest by region. Per country and timeframe. For SEO, market and trend research. No setup.
139 runs · 6 users · $0.001 / keyword scraped
AliExpress Product Search Scraper
Search AliExpress by keyword and export one clean row per product — title, sale price, original price, image and product URL. Export to JSON, CSV or Excel.
135 runs · 3 users · $0.003 / product scraped
Google Maps Scraper
Search Google Maps and scrape places: name, category, full address, city, coordinates, rating, phone, website, Place ID and map link. Fast browser-free via Google's internal endpoint, no setup. For local lead generation and market research.
130 runs · 2 users · $0.005 / place scrapedSend the site and the fields. We build it and you get it first.