GoodFirms Scraper
hipersoft/goodfirms-scraper
Scrape GoodFirms B2B agencies and software companies: name, rating, reviews, hourly rate, employees, founded year, location, services, website and profile URL. By category or GoodFirms URL. No setup.
Total users
3Monthly users
3Total runs
97Per firm scraped
$0.0043Last rebuilt
Oct 26, 2026Overview
Scrape GoodFirms — a leading B2B research and review directory of agencies and software companies — into clean JSON, CSV, Excel or XML. Extract company name, rating, review count, hourly rate, employee band, founding year, location, services, website and profile URL from any GoodFirms category or city listing. Fast and reliable.
What does GoodFirms Scraper do?
The GoodFirms Scraper crawls GoodFirms directory pages and extracts every listed firm as a structured record. Point it at a category and city (or paste exact listing URLs) and it exports a clean dataset of agencies with their ratings, pricing, firmographics and services — a faster, cheaper way to build B2B lead and vendor lists than copying pages by hand.
What data can you scrape from GoodFirms?
| Data | Fields |
|---|---|
| 🏢 Firm | name, GoodFirms profile URL, website, sponsored flag |
| ⭐ Reputation | rating, review count |
| 💵 Pricing | hourly rate band |
| 👥 Firmographics | employee band, founding year, location |
| 🧰 Services | listed service focus areas |
| 📝 Profile | description, source listing URL, collected timestamp |
Use cases
- B2B lead generation — build targeted outreach lists of agencies and software vendors by category and city.
- Agency & vendor research — shortlist partners filtered by rating, reviews, price and size.
- Competitive analysis — track how competitors are positioned, priced and reviewed on GoodFirms.
- Market research — measure agency density, pricing bands and service trends across regions.
- CRM & dataset enrichment — append firmographics (size, founding year, location) to existing company records.
- Recruitment & partnerships — find firms by service focus for hiring, referrals or co-marketing.
How to scrape GoodFirms data
- Add the GoodFirms Scraper to your Apify account.
- Enter a category and city, or paste exact GoodFirms listing URLs into startUrls.
- Set maxItems to cap how many firms you collect.
- Click Run and watch results stream into the dataset.
- Export to JSON, CSV, Excel or XML, or pull them through the Apify API.
Input
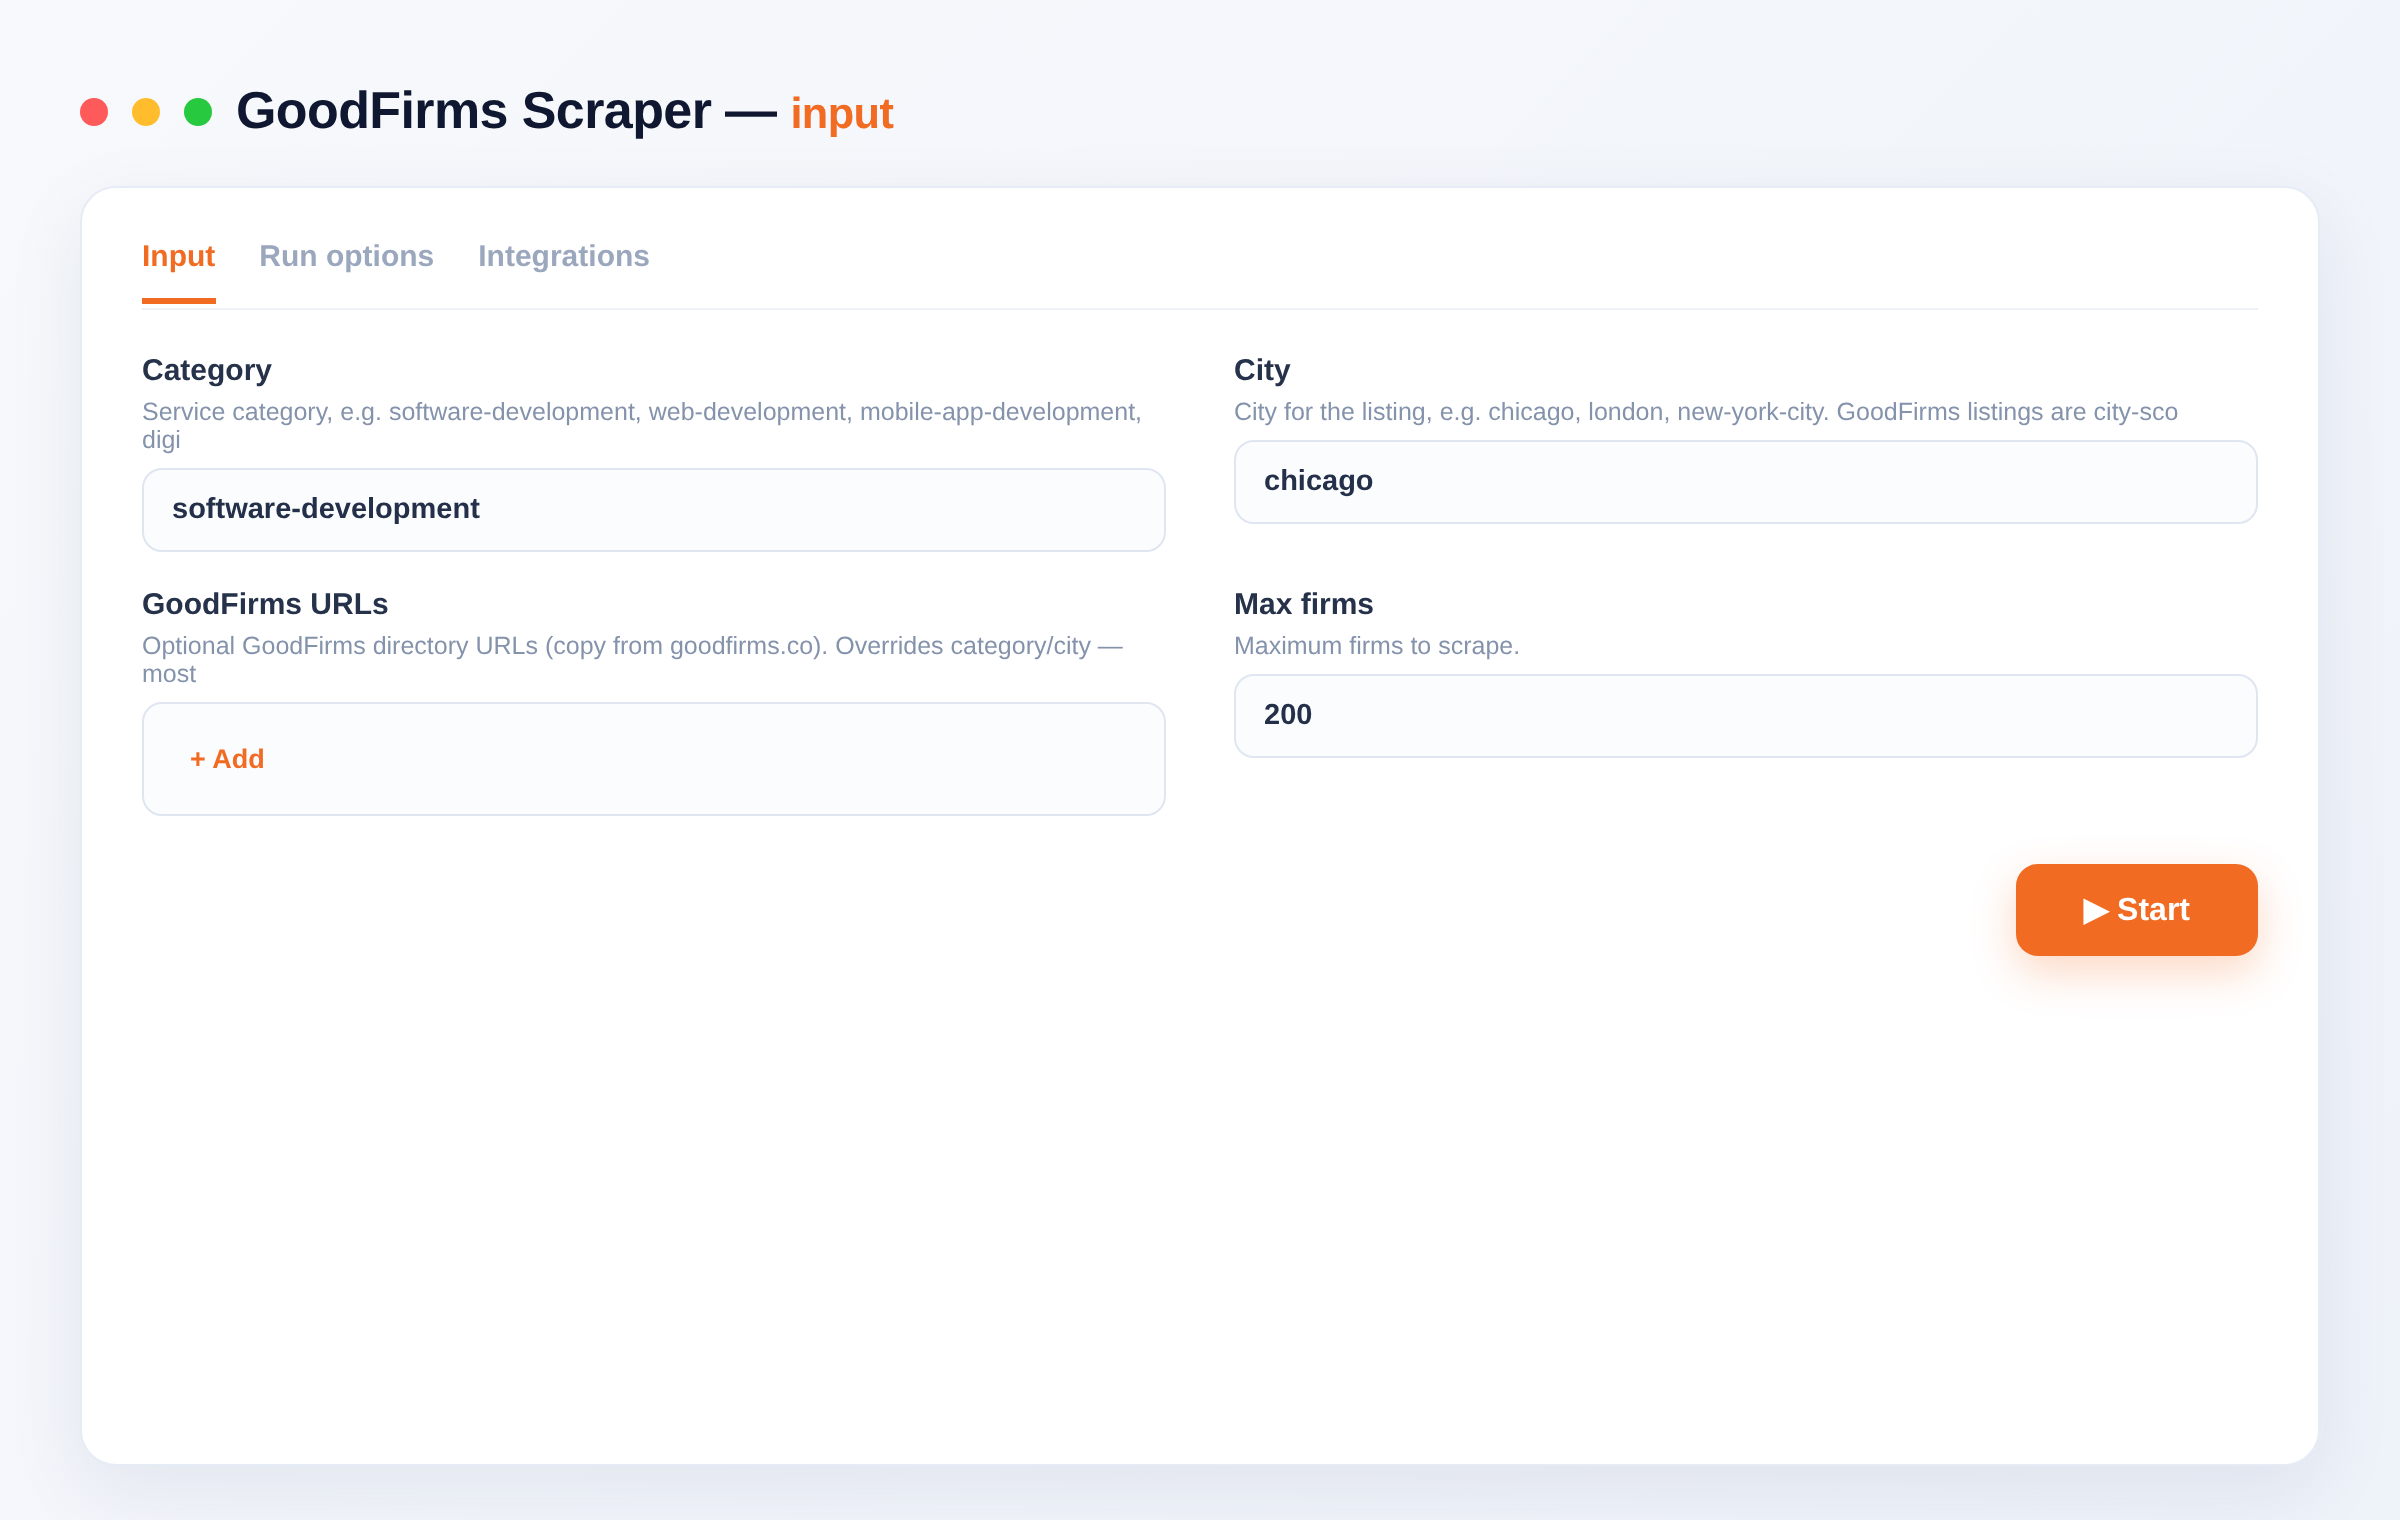
Enter a category + city, or paste GoodFirms directory URLs. Cap the run with maxItems.
Example input
{ "startUrls": ["https://www.goodfirms.co/directory/city/top-web-development-companies/chicago"], "maxItems": 300 }
| Field | Description |
|---|---|
category |
GoodFirms category slug, e.g. software-development, digital-marketing. Combine with city. |
city |
City slug, e.g. chicago. Combine with category. |
startUrls |
GoodFirms directory URLs copied from goodfirms.co. Most reliable — paste the exact city-scoped page URL. |
maxItems |
Maximum number of firms to return. |
Output
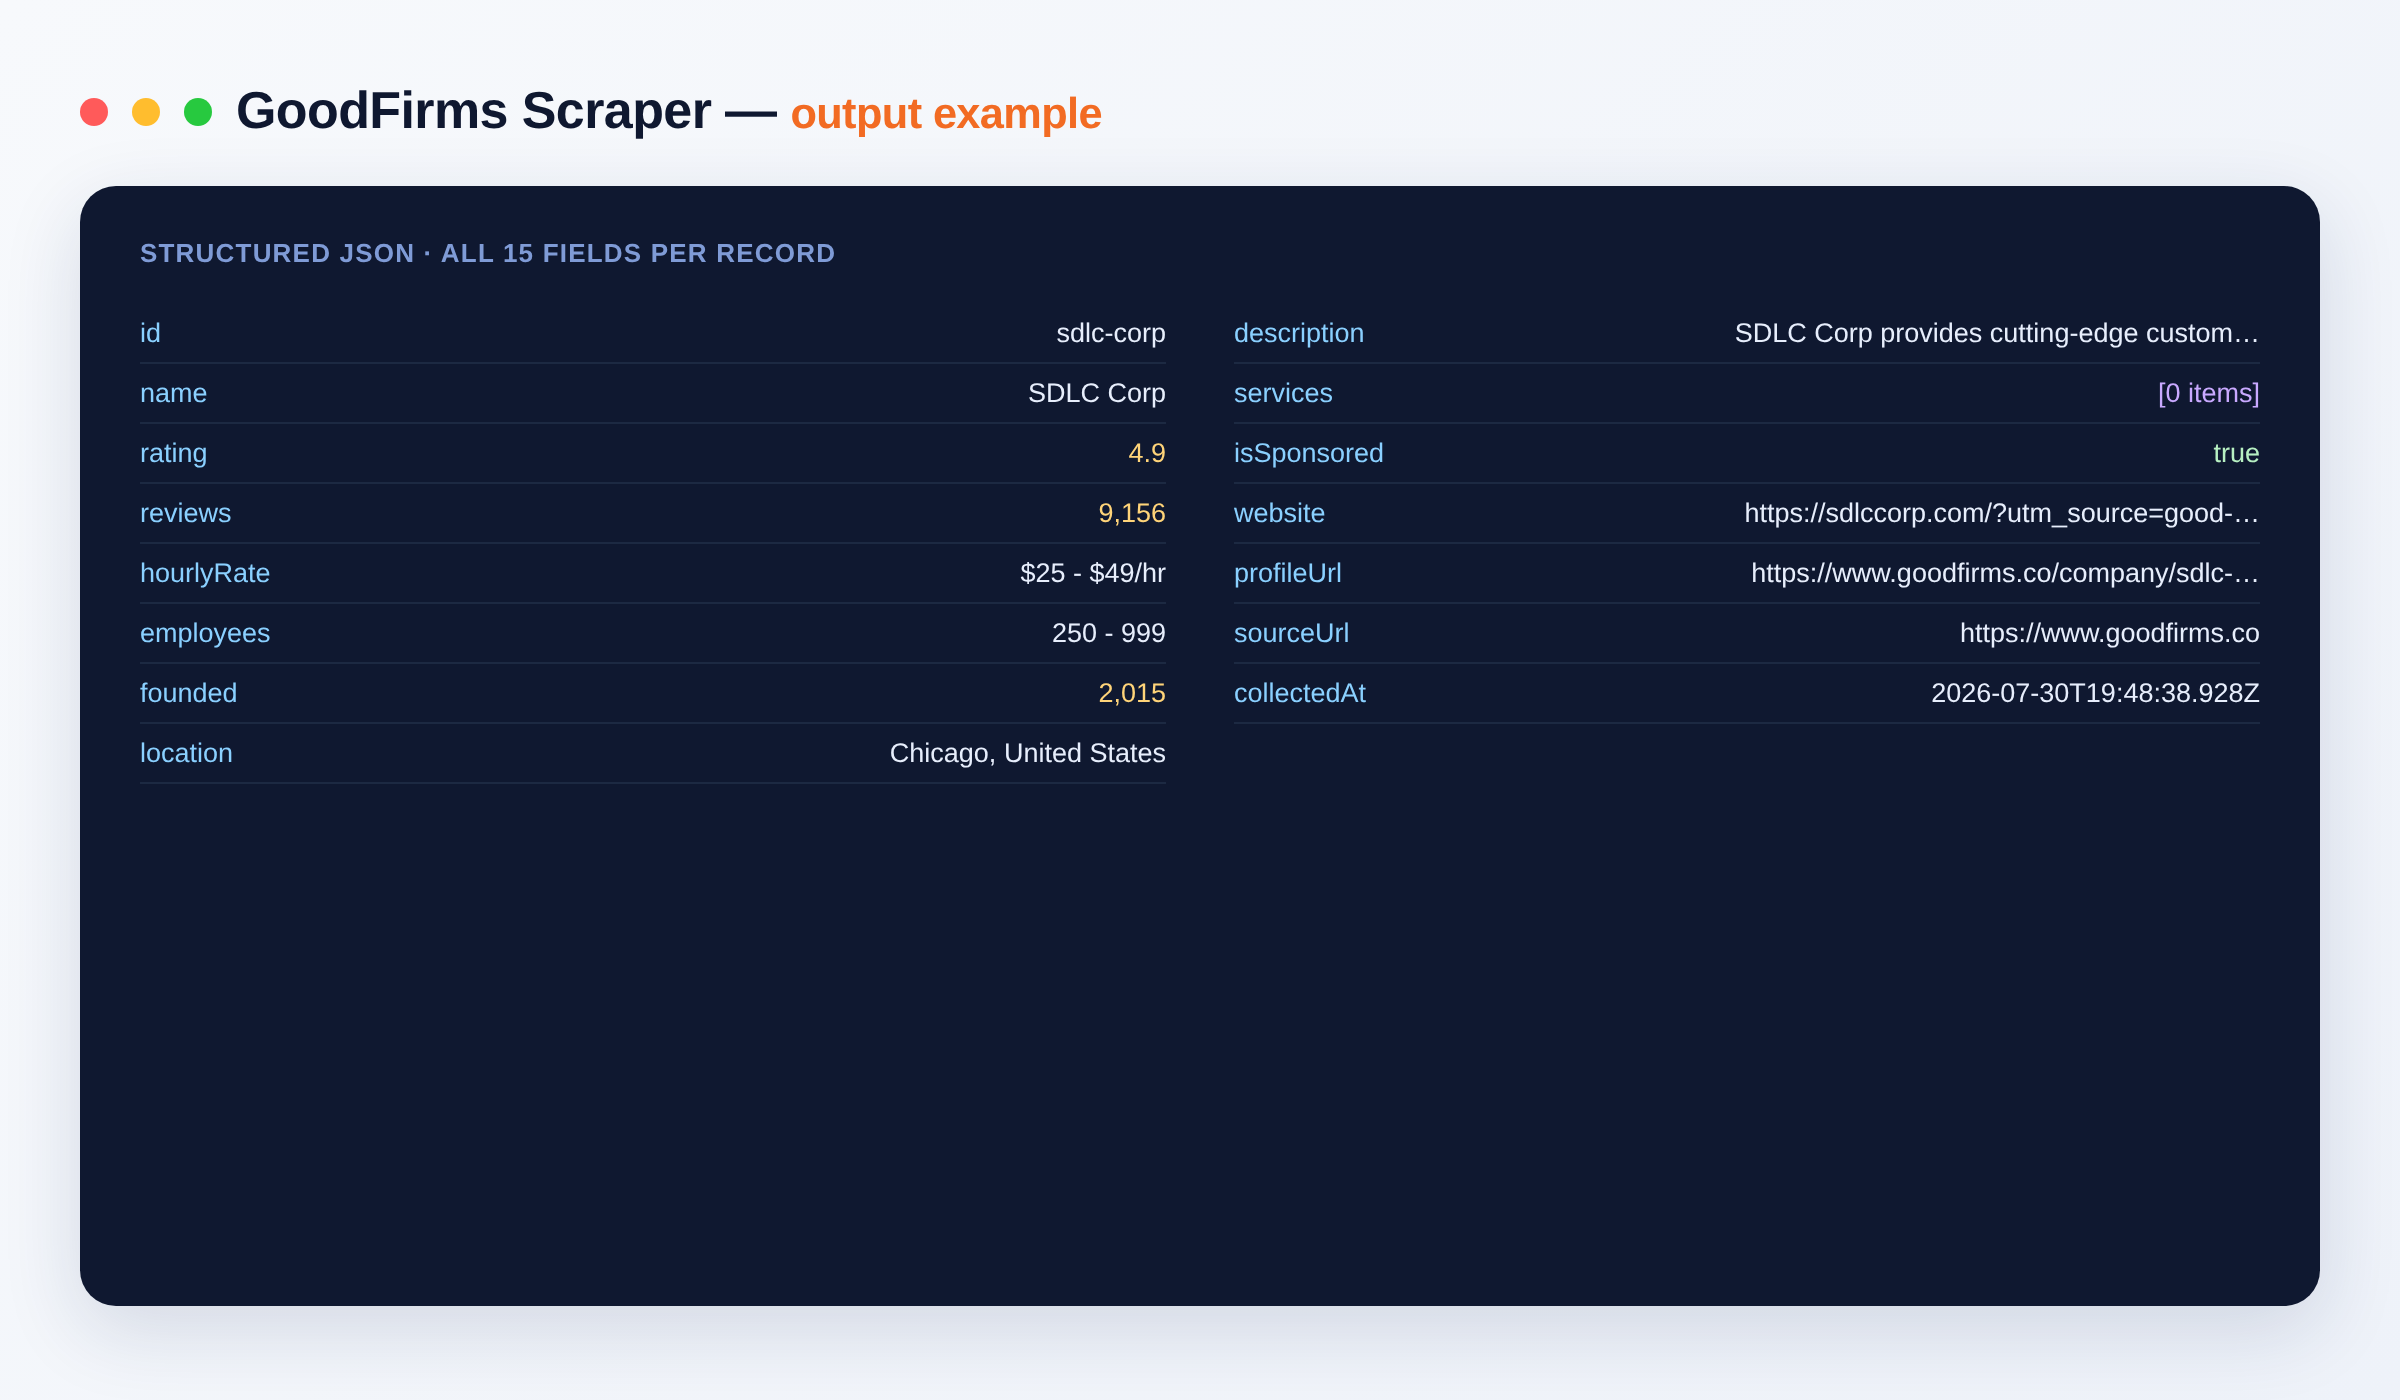
Each firm is one clean record:
{
  "id": "webfx",
  "name": "WebFX",
  "rating": 4.8,
  "reviews": 825,
  "hourlyRate": "$100 - $149/hr",
  "employees": "250 - 999",
  "founded": 1995,
  "location": "Chicago, United States",
  "description": "Full-service digital marketing agency.",
  "services": ["Digital Marketing", "SEO", "PPC"],
  "isSponsored": false,
  "website": "https://www.webfx.com/",
  "profileUrl": "https://www.goodfirms.co/company/webfx",
  "sourceUrl": "https://www.goodfirms.co/directory/city/top-web-development-companies/chicago",
  "collectedAt": "2026-07-30T12:00:00.000Z"
}
Output schema
| Field | Type | Description |
|---|---|---|
id |
string | Unique GoodFirms company identifier (profile slug). |
name |
string | Company or agency name. |
rating |
number | Average GoodFirms review rating, 0–5. |
reviews |
integer | Number of client reviews on the profile. |
hourlyRate |
string | Advertised hourly rate band, e.g. $100 - $149/hr. |
employees |
string | Employee count band, e.g. 250 - 999. |
founded |
integer | Year the company was founded. |
location |
string | Headquarters location (city, country). |
description |
string | Company profile summary. |
services |
array | List of the firm's service focus areas. |
isSponsored |
boolean | Whether the listing is a sponsored placement. |
website |
string (URL) | The company's own website URL. |
profileUrl |
string (URL) | GoodFirms profile page URL. |
sourceUrl |
string (URL) | Directory listing page the record was collected from. |
collectedAt |
string (ISO date) | Timestamp when the record was scraped. |
Need more B2B leads data?
- Houzz Scraper — home-design pros, reviews and contact details.
- Europages Scraper — European B2B suppliers and manufacturers.
- BBB Scraper — Better Business Bureau company profiles and ratings.
- Google Maps Scraper — local businesses, ratings and contact info.
FAQ
How many firms can I scrape?
As many as the listings contain — set maxItems to cap the run, or leave it open to collect an entire category or city.
Do I need any setup or a login? No setup and no login. Just add the actor, enter a category and city (or listing URLs), and run.
How does billing work? You pay only per firm you get — no subscription. Our per-item price floors 20% below the cheapest comparable scraper.
What export formats are supported? JSON, CSV, Excel and XML, plus the Apify API for programmatic access.
Can I filter by rating, price or size? Every record includes rating, reviews, hourly rate and employee band, so you can filter and sort in your dataset or downstream tools.
How fresh is the data?
Each run fetches live listings, so results reflect GoodFirms at the moment you run the actor. The collectedAt field timestamps every record.
Is it legal? The actor returns only publicly available data. You are responsible for complying with GoodFirms' terms and applicable data and marketing laws.
Can I connect it to my other tools? The GoodFirms Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Notes
Original clean-room implementation. Returns only public data; you are responsible for compliance with GoodFirms' terms. Not affiliated with GoodFirms.
Input
| Field | Type | Description |
|---|---|---|
categoryCategory | string | Service category, e.g. software-development, web-development, mobile-app-development, digital-marketing, seo. Pair with a city. Default: "software-development" |
cityCity | string | City for the listing, e.g. chicago, london, new-york-city. GoodFirms listings are city-scoped. Default: "chicago" |
startUrlsGoodFirms URLs | array | Optional GoodFirms directory URLs (copy from goodfirms.co). Overrides category/city — most reliable. |
maxItemsMax firms | integer | Maximum firms to scrape. Default: 200 |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~goodfirms-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/goodfirms-scraper").call(run_input={})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/goodfirms-scraper').call({});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Firm scraped One agency/company record scraped. | $0.0043 | $0.0021 |
| Page loaded One GoodFirms results page fetched. | $0.0008 | $0.0008 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
North Data Scraper
Look up European companies on North Data: legal name, former names, register number, address, founding date, LEI, business purpose, managing directors and officers, and recent register publications. Germany, UK, France, Austria and 20+ countries. Bulk lookups.
2,467 runs · 5 users · $0.004 / company
Website Content Crawler
Extract clean, readable content from any list of websites: page title, meta description, headings, main body text, word count and link/image counts. Optional same-domain crawl. Bulk-ready. Great for LLM/RAG ingestion, content audits and research.
206 runs · 20 users · $0.0024 / page scraped
SpyFu Domain Scraper
Bulk SEO and PPC reports for any domain from SpyFu: organic keywords, monthly SEO clicks and value, Google Ads budget, paid keywords, top keywords, competitors, top countries and monthly history. Competitor research for agencies. Export CSV/JSON.
185 runs · 7 users · $0.008 / domain report
Trustpilot Reviews Scraper
Scrape Trustpilot reviews and company ratings by company domain or Trustpilot URL: star rating, title, text, reviewer name & country, verification, date, company reply, plus company TrustScore and total reviews.
146 runs · 4 users · $0.0006 / review scraped
ACRA Singapore Company Registry Scraper
Search and export Singapore's full ACRA corporate registry: UEN, entity name, status, incorporation date, address, SSIC industry codes, officers, former names and audit firms. Filter by name, status, entity type or industry. Public open data, no setup.
138 runs · 10 users · $0.01 / company scraped
Wayback Machine Scraper
List every Internet Archive (Wayback Machine) snapshot of a URL or whole domain: timestamp, snapshot URL, status code, MIME type and content digest. Filter by date, status and dedupe. For SEO, OSINT and historical research. No setup.
135 runs · 15 users · $0.002 / snapshot scrapedSend the site and the fields. We build it and you get it first.