CNN Fear & Greed Index Scraper
hipersoft/cnn-fear-greed-scraper
Scrape the CNN Fear & Greed Index: current market-sentiment score and rating, a full historical timeline, and all seven component indicators. Clean structured JSON, CSV or Excel for trading signals, backtesting, dashboards and alerting.
Total users
6Monthly users
2Total runs
547Per item scraped
$0.003Last rebuilt
Oct 26, 2026Overview
Scrape the CNN Fear & Greed Index as clean, structured JSON, CSV, Excel or XML: the current market-sentiment score and rating, a full historical timeline of daily readings, and every one of the component indicators behind the index. Track whether the market is in fear or greed, chart sentiment over time, and feed it straight into trading signals, dashboards and alerts. Fast and reliable, with no account to manage.
What does CNN Fear & Greed Index Scraper do?
This CNN Fear & Greed Index scraper turns market-sentiment data into a structured dataset. In one run it returns the headline index (score from 0–100 and its rating, from extreme fear to extreme greed), the day-by-day historical timeline for roughly the last year, and the current reading of each component indicator that drives the index. Use it to power sentiment dashboards, backtest strategies, build trading signals and monitor mood swings in the market, then export the results in any format the Apify platform supports.
What data can you scrape from the CNN Fear & Greed Index?
| Data point | Description |
|---|---|
| Current score | Latest Fear & Greed Index value, 0 (extreme fear) to 100 (extreme greed). |
| Current rating | Sentiment label: extreme fear, fear, neutral, greed or extreme greed. |
| Timestamp | When the current reading was published (ISO-8601). |
| Previous close | The index value at the previous close. |
| Previous 1 week | The index value one week ago. |
| Previous 1 month | The index value one month ago. |
| Previous 1 year | The index value one year ago. |
| Historical timeline | One row per day: date, score and rating over the history window. |
| Component score | Current score for each indicator that makes up the index. |
| Component rating | Fear/greed rating for each component indicator. |
| Component name | Human-readable name of each indicator (e.g. Market Momentum, Safe Haven Demand). |
The component indicators
The index is a composite of several market signals, and this scraper exposes each one's current reading:
- Market Momentum — the S&P 500 versus its moving average.
- Stock Price Strength — stocks hitting highs versus lows.
- Stock Price Breadth — trading volume in rising versus falling stocks.
- Put and Call Options — the balance of bearish versus bullish options.
- Market Volatility — the VIX and its moving average.
- Junk Bond Demand — the spread between junk and investment-grade yields.
- Safe Haven Demand — the return on stocks versus Treasuries.
Use cases
- Trading signals — turn extreme-fear or extreme-greed readings into buy/sell triggers.
- Backtesting sentiment — join the historical timeline with price data to test contrarian strategies.
- Market dashboards — display a live fear/greed gauge alongside your other market widgets.
- Alerting — notify a channel when the index crosses a threshold or flips fear ↔ greed.
- Research & reporting — study how sentiment moved around events, earnings or selloffs.
- Component analysis — break the headline number down into its underlying indicators.
- Dataset building — feed structured sentiment data into BI tools, notebooks or models.
How to scrape CNN Fear & Greed Index data
- Add CNN Fear & Greed Index Scraper to your Apify account and open its input.
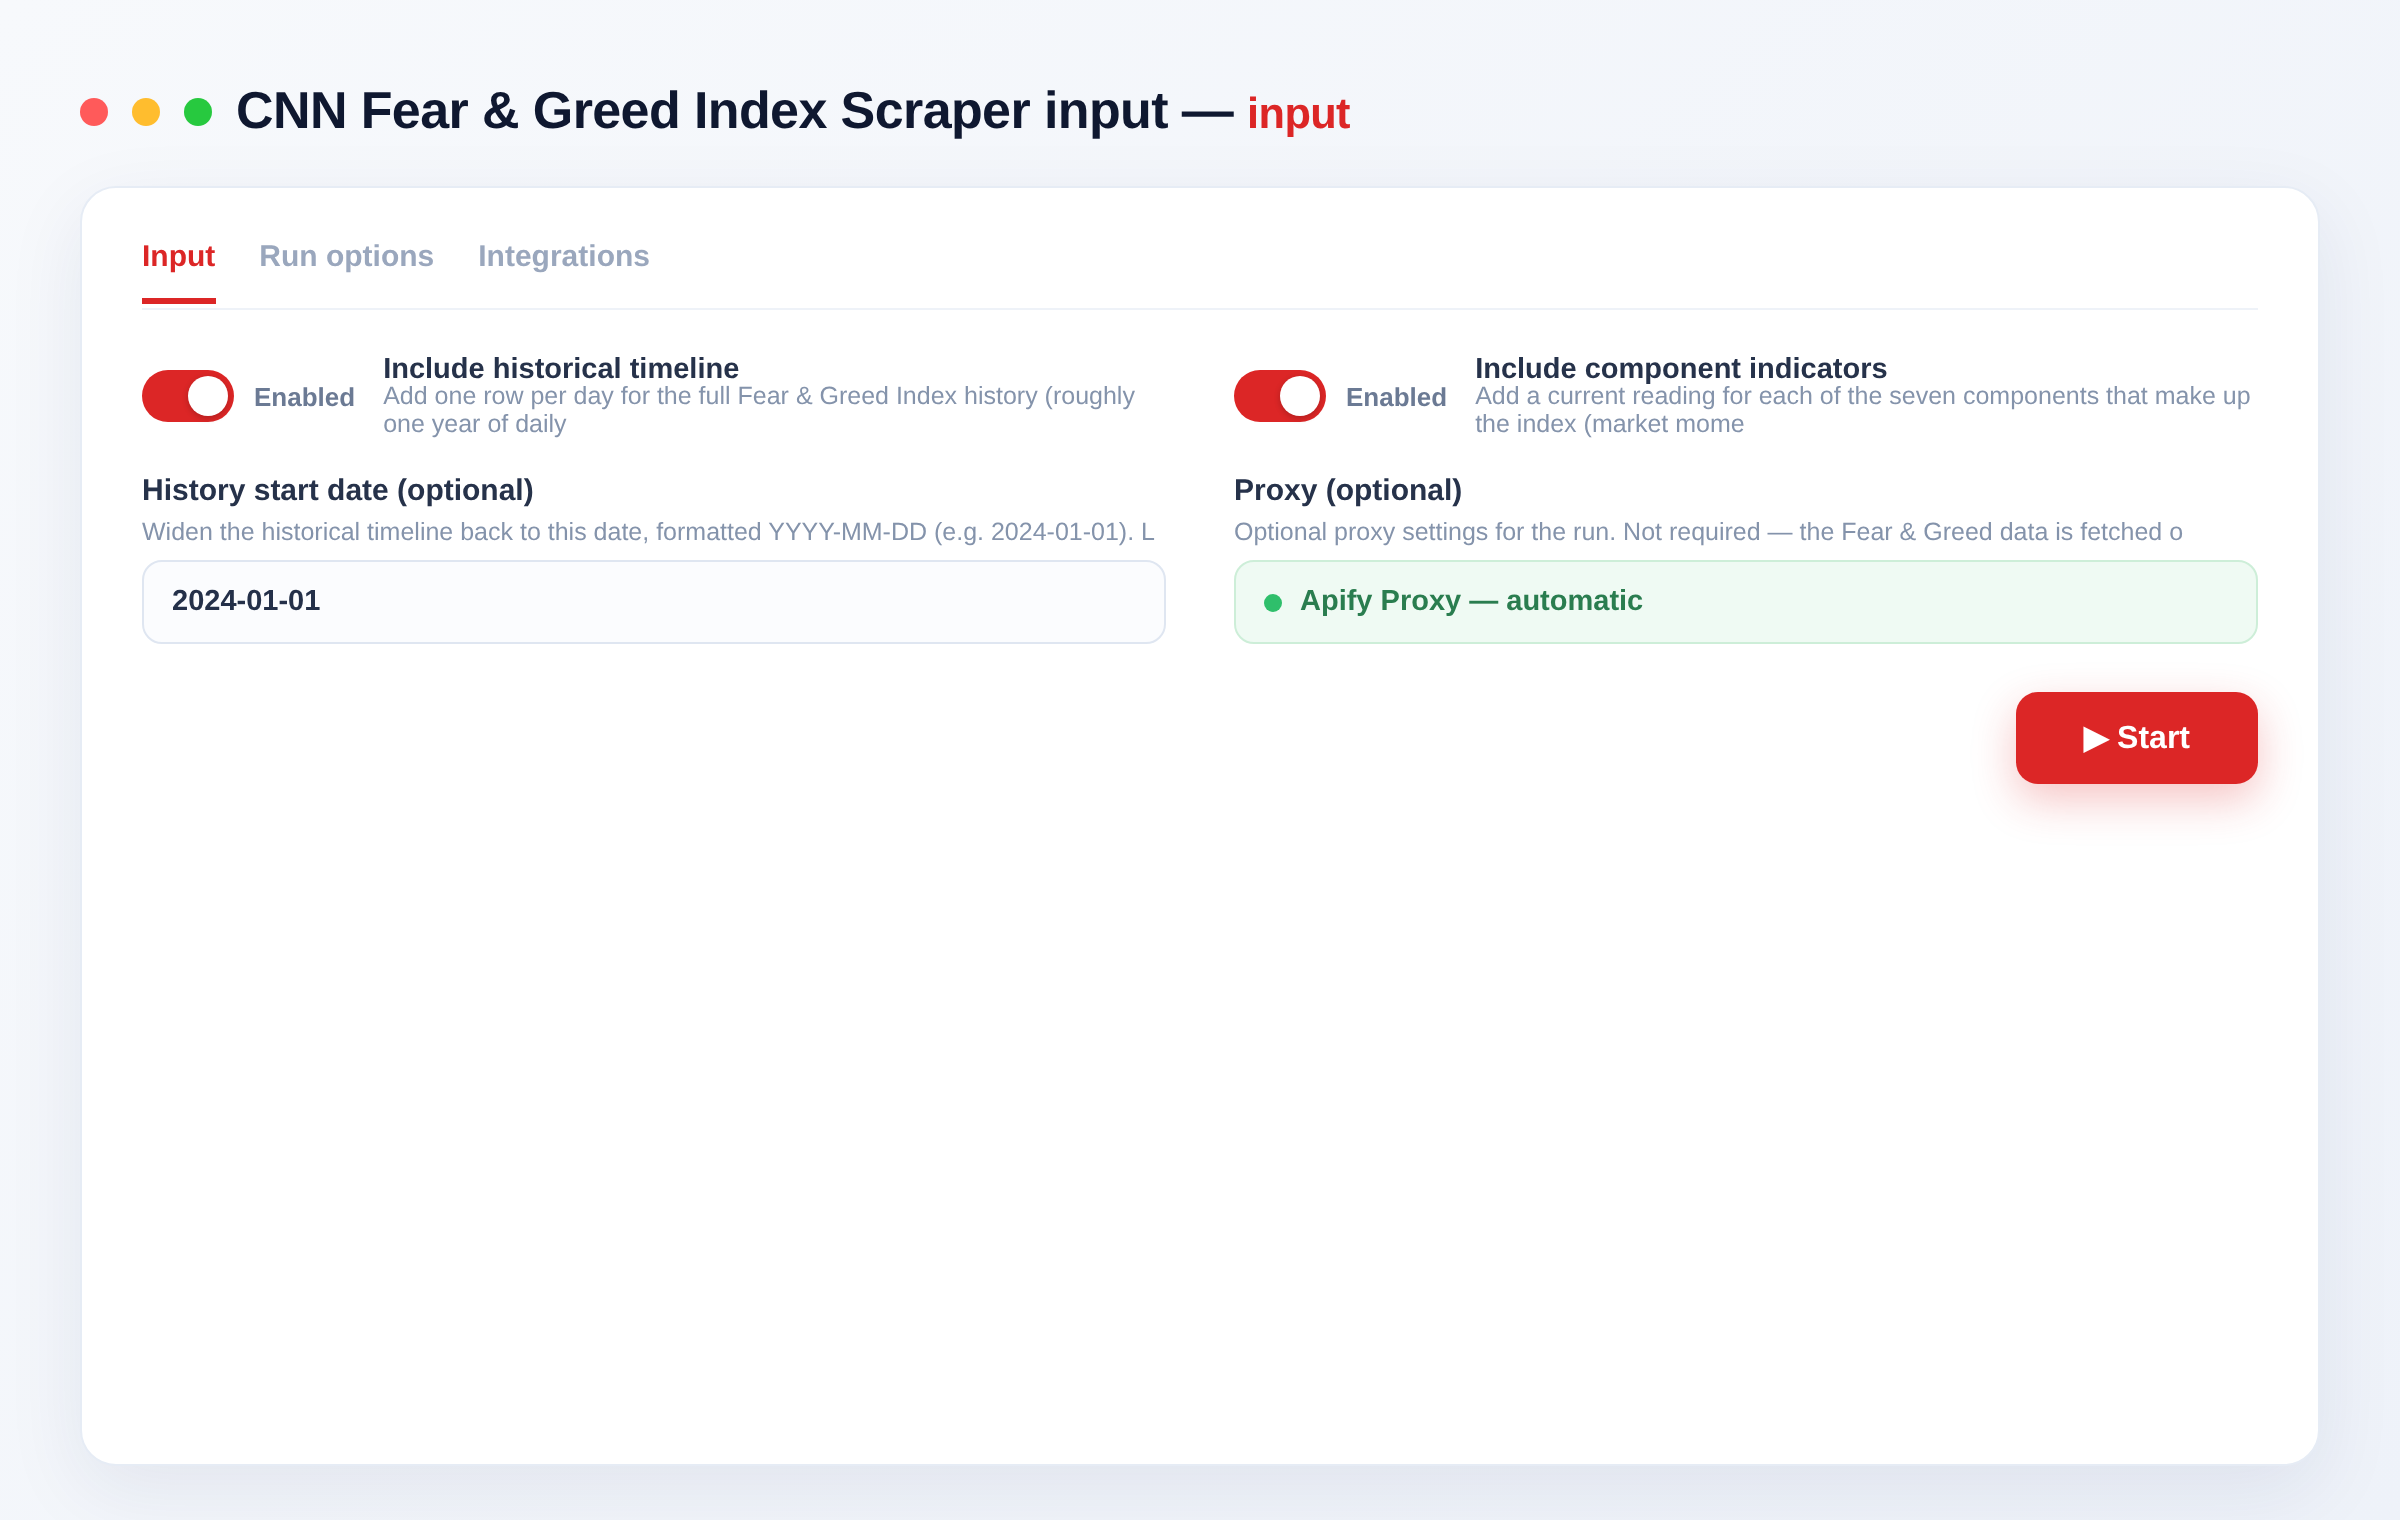
- Keep Include historical timeline on for the day-by-day history, or turn it off for just the current index.
- Keep Include component indicators on to also get each underlying signal's current reading.
- Optionally set a History start date (YYYY-MM-DD) to widen the timeline further back.
- Click Run, then export the results as JSON, CSV, Excel or XML, or fetch them through the Apify API.
Input
{
  "includeHistorical": true,
  "includeComponents": true,
  "startDate": "",
  "proxyConfiguration": { "useApifyProxy": false }
}
| Field | Description |
|---|---|
includeHistorical |
Add one row per day for the full index history (about a year of daily readings). |
includeComponents |
Add a current reading for each component indicator behind the index. |
startDate |
Optional. Widen the historical timeline back to this date, formatted YYYY-MM-DD. |
proxyConfiguration |
Optional Apify proxy settings for the run (not required). |
Output
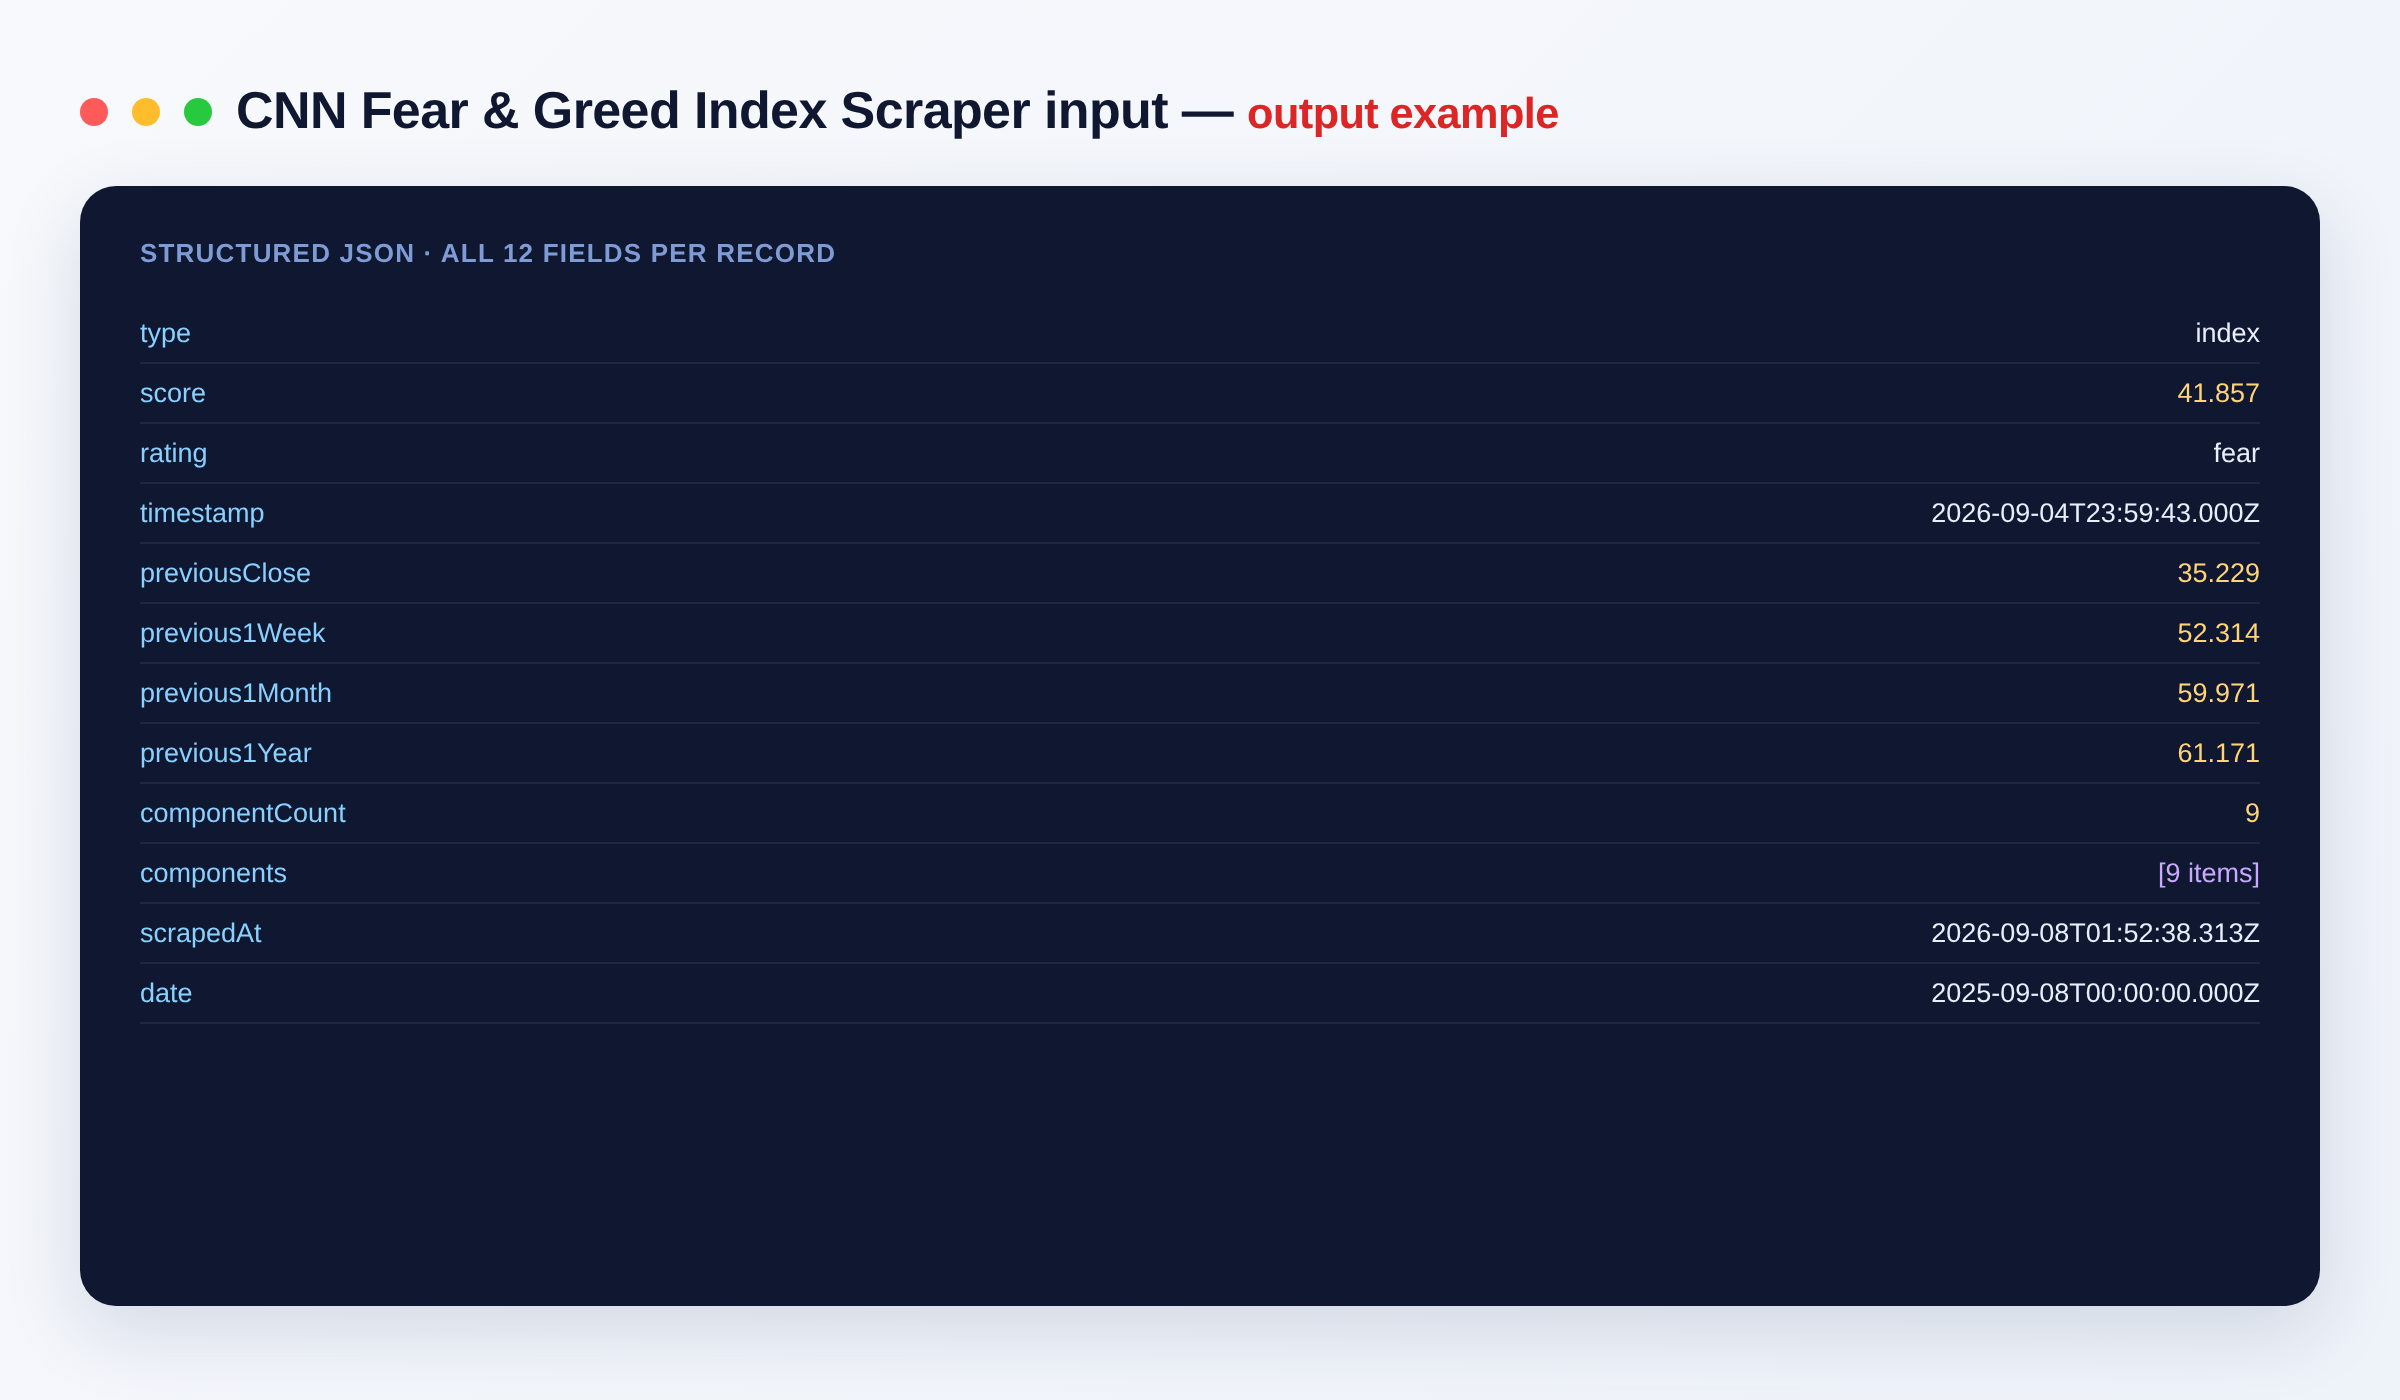
The dataset mixes three row types, each tagged with a type field so you can filter them apart: one index row, many historical rows, and one component row per indicator.
Current index (type: "index")
{
  "type": "index",
  "score": 41.86,
  "rating": "fear",
  "timestamp": "2026-09-04T23:59:43.000Z",
  "previousClose": 35.23,
  "previous1Week": 52.31,
  "previous1Month": 59.97,
  "previous1Year": 61.17,
  "componentCount": 9,
  "components": [
    { "key": "market_momentum_sp500", "name": "Market Momentum (S&P 500)", "score": 36.6, "rating": "fear", "timestamp": "2026-09-04T20:33:06.000Z" },
    { "key": "safe_haven_demand", "name": "Safe Haven Demand", "score": 26, "rating": "fear", "timestamp": "2026-09-04T19:59:55.000Z" }
  ],
  "scrapedAt": "2026-09-04T23:59:59.000Z"
}
Historical point (type: "historical")
{ "type": "historical", "date": "2026-09-04T23:59:43.000Z", "score": 41.86, "rating": "fear" }
Component reading (type: "component")
{ "type": "component", "component": "safe_haven_demand", "name": "Safe Haven Demand", "score": 26, "rating": "fear", "timestamp": "2026-09-04T19:59:55.000Z" }
Output schema
| Field | Type | Description |
|---|---|---|
type |
string | Row type: index, historical or component. |
score |
number | Sentiment score, 0 (extreme fear) to 100 (extreme greed). |
rating |
string | Sentiment label: extreme fear, fear, neutral, greed or extreme greed. |
timestamp |
string (ISO date) | When the reading was published (index and component rows). |
date |
string (ISO date) | Date of a historical daily reading. |
name |
string | Human-readable component name (index summary and component rows). |
component |
string | Machine key of the component indicator (component rows). |
previousClose |
number | Index value at the previous close (index row). |
previous1Week |
number | Index value one week ago (index row). |
previous1Month |
number | Index value one month ago (index row). |
previous1Year |
number | Index value one year ago (index row). |
componentCount |
integer | Number of component indicators included (index row). |
components |
array | Summary array of each component's current score and rating (index row). |
scrapedAt |
string (ISO date) | Timestamp when the run collected the data. |
Need more market data?
- CoinGecko Scraper — live crypto prices, market cap, volume and ATH/ATL.
- DefiLlama Scraper — DeFi protocols, yields, chains and stablecoins with TVL and APY.
- Yahoo Finance Scraper — live quotes and OHLCV history for stocks, ETFs, crypto and forex.
- TradingView Screener Scraper — screen stocks and crypto by dozens of technical and fundamental filters.
FAQ
Do I need an account or key? No login or key to manage — just set your inputs and click Run.
What does the score mean?
The index runs 0–100: lower values mean fear (and, at the extreme, panic selling), higher values mean greed. The rating field labels the zone as extreme fear, fear, neutral, greed or extreme greed.
How far back does the history go?
The default timeline covers roughly the last year of daily readings. Set a startDate to widen the window further back.
How fresh is the data? The current index, its comparison points and each component are pulled live at run time; every row carries a timestamp.
What are the component indicators? They are the underlying market signals the headline index blends together — market momentum, stock price strength and breadth, put/call options, market volatility, junk bond demand and safe-haven demand.
What export formats are available? JSON, CSV, Excel and XML, plus programmatic access through the Apify API.
Can I connect this to my other tools? The CNN Fear & Greed Index Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Is this official CNN data? The data reflects the public CNN Business Fear & Greed Index, but this actor is an independent tool and is not affiliated with or endorsed by CNN.
Notes
Original clean-room implementation. Returns only public market-sentiment data; you are responsible for compliant use. Not affiliated with CNN; all trademarks belong to their respective owners.
Input
| Field | Type | Description |
|---|---|---|
includeHistoricalInclude historical timeline | boolean | Add one row per day for the full Fear & Greed Index history (roughly one year of daily readings), so you can chart or backtest sentiment over time. Default: true |
includeComponentsInclude component indicators | boolean | Add a current reading for each of the seven components that make up the index (market momentum, stock price strength and breadth, put/call options, market volatility, junk bond demand and safe-haven demand). Default: true |
startDateHistory start date (optional) | string | Widen the historical timeline back to this date, formatted YYYY-MM-DD (e.g. 2024-01-01). Leave empty for the default window (about one year). |
proxyConfigurationProxy (optional) | object | Optional proxy settings for the run. Not required — the Fear & Greed data is fetched over plain HTTP. Default: {"useApifyProxy": false} |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~cnn-fear-greed-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/cnn-fear-greed-scraper").call(run_input={})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/cnn-fear-greed-scraper').call({});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Item scraped One Fear & Greed data point (index, historical point, or component reading). | $0.003 | $0.0015 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Divar Scraper
Scrape classified ads from Divar, Iran's largest marketplace: title, price (Toman), category, city, district, images and the listing URL. Search any Iranian city with an optional keyword and export one clean row per ad as JSON, CSV or Excel. For market research, price tracking and n8n.
224 runs · 22 users · $0.003 / listing scraped
Airbnb Scraper
Search Airbnb by location and scrape listings: name, property type, price, rating, reviews, coordinates, photos, badges and link. For short-term rental, pricing and market research.
122 runs · 2 users · $0.005 / listing scraped
Singapore HDB Property Information Scraper
Export master data for every HDB block in Singapore (~13,300 blocks): address, town, year completed, max floor, total units, unit mix by flat type (sold & rental) and amenities (market/hawker, carpark, commercial, pavilion). Filter by town, street, year. Public open data, no setup.
113 runs · 1 users · $0.002 / block scraped
PropertyGuru Singapore Scraper
Scrape PropertyGuru Singapore property listings: price, beds, baths, size, address, property type, agent and URL. For property research and lead generation.
106 runs · 3 users · $0.004 / listing scraped
EdgeProp Singapore Property Scraper
Scrape EdgeProp Singapore property listings for sale and rent: price, address, beds, baths, size, PSF and URL.
105 runs · 1 users · $0.004 / listing scraped
Crexi Commercial Real Estate Scraper
Scrape Crexi commercial real estate listings: price, address, property type, size, cap rate, broker and URL.
101 runs · 2 users · $0.0075 / listing scrapedSend the site and the fields. We build it and you get it first.